This is the multi-page printable view of this section.
Click here to print.
Return to the regular view of this page.
Latest
Kernel Versions
HUATUO supports Linux kernel 4.18 and later. The following guest environments
are covered by the distribution test matrix:
| No. |
OS |
Kernel |
Cgroup |
Clang |
libbpf |
glibc |
gcc |
make |
Python |
Java |
Rust |
| 1 |
Ubuntu 26.04 LTS |
7.0.0-30-generic |
v2 |
21.1.8 |
1.6.3 |
2.43 |
15.2.0 |
4.4.1 |
3.14.4 |
17.0.20.1+1 |
1.93.1 |
| 2 |
Ubuntu 24.04.4 LTS |
6.8.0-138-generic |
v2 |
15.0.7 |
1.3.0 |
2.39 |
13.3.0 |
4.3 |
3.12.3 |
17.0.20.1+1 |
1.75.0 |
| 3 |
Ubuntu 22.04.5 LTS |
5.15.0-190-generic |
v2 |
15.0.7 |
0.5.0 |
2.35 |
11.4.0 |
4.3 |
3.10.12 |
17.0.20.1+1 |
1.75.0 |
| 4 |
Ubuntu 20.04.6 LTS |
5.4.0-216-generic |
hybrid |
12.0.0 |
0.5.0 |
2.31 |
9.4.0 |
4.2.1 |
3.8.10 |
17.0.20.1+1 |
1.75.0 |
| 5 |
Debian 13 (trixie) |
6.12.107+deb13-cloud-amd64 |
v2 |
19.1.7 |
1.5.0 |
2.41 |
14.2.0 |
4.4.1 |
3.13.5 |
17.0.20.1+1 |
1.85.1 |
| 6 |
Debian 12 (bookworm) |
6.1.0-53-cloud-amd64 |
v2 |
15.0.6 |
1.1.2 |
2.36 |
12.2.0 |
4.3 |
3.11.2 |
17.0.20.1+1 |
1.63.0 |
| 7 |
Rocky Linux 9.8 |
5.14.0-687.10.1.el9_8.0.1.x86_64 |
v2 |
21.1.8 |
1.5.0 |
2.34 |
11.5.0 |
4.3 |
3.9.25 |
17.0.20.1+1 |
1.92.0 |
| 8 |
Rocky Linux 8.10 |
4.18.0-553.el8_10.x86_64 |
v1 |
21.1.8 |
0.5.0 |
2.28 |
8.5.0 |
4.2.1 |
3.6.8 |
17.0.20.1+1 |
1.92.0 |
| 9 |
Fedora Linux 44 |
6.19.10-300.fc44.x86_64 |
v2 |
22.1.8 |
1.6.3 |
2.43 |
16.2.1 |
4.4.1 |
3.14.3 |
17.0.20.1+1 |
1.98.1 |
| 10 |
openEuler 24.03 LTS-SP4 |
6.6.0-159.4.3.154.oe2403sp4.x86_64 |
v1 |
17.0.6 |
1.2.2 |
2.38 |
12.3.1 |
4.4.1 |
3.11.6 |
17.0.20.1+1 |
1.96.0 |
| 11 |
openEuler 22.03 LTS-SP4 |
5.10.0-216.0.0.115.oe2203sp4.x86_64 |
v1 |
12.0.1 |
0.8.1 |
2.34 |
10.3.1 |
4.3 |
3.9.9 |
17.0.20.1+1 |
1.82.0 |
| 12 |
Anolis OS 8.10 |
5.10.134-18.an8.x86_64 |
v1 |
18.1.8 |
0.5.0 |
2.28 |
8.5.0 |
4.2.1 |
3.6.8 |
17.0.20.1 |
1.79.0 |
| 13 |
OpenCloudOS 9.6 |
6.6.119-51.5.oc9.x86_64 |
v2 |
17.0.6 |
1.2.2 |
2.38 |
12.3.1 |
4.4.1 |
3.11.6 |
17.0.20.1 |
1.96.0 |
1 - Getting started
To help users quickly experience and deploy HUATUO, this document is divided into three sections: Quick Experience,Quick Start,Compilation & Deployment.
1. Quick Experience
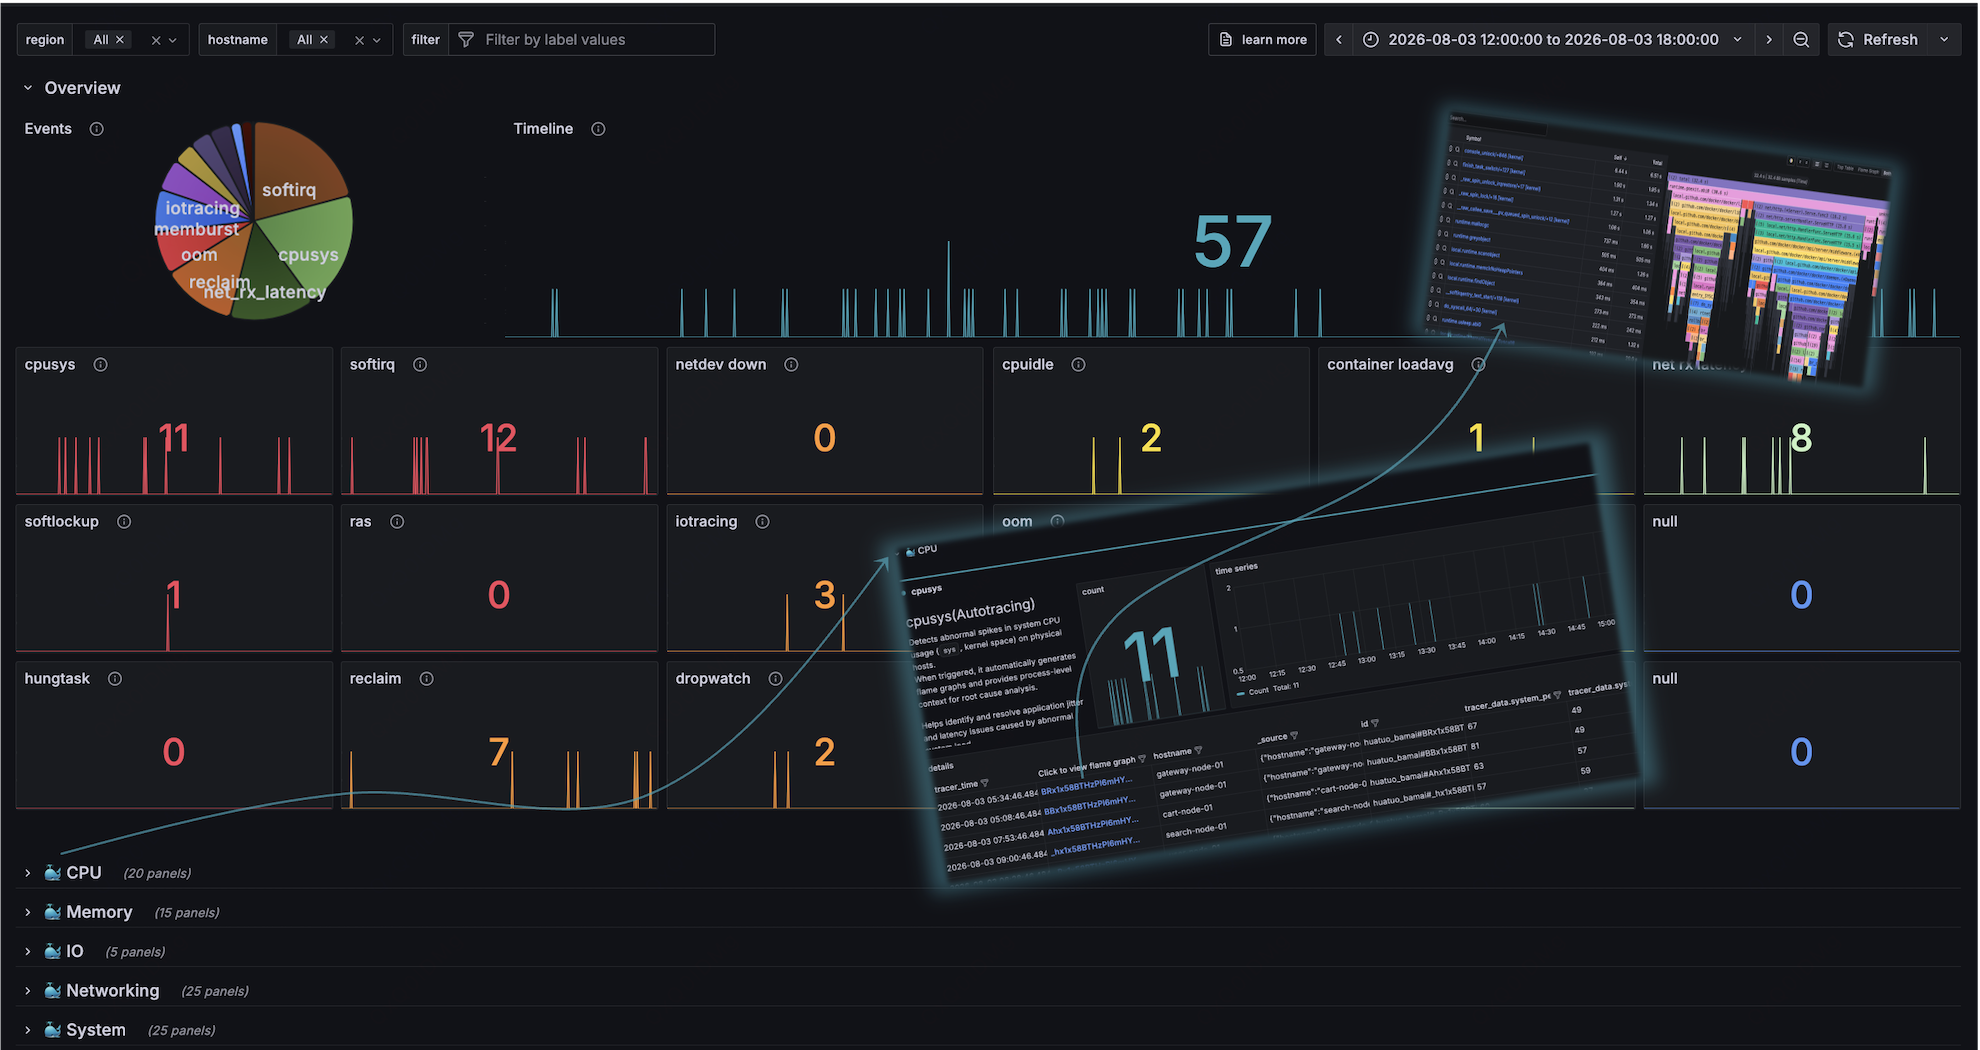
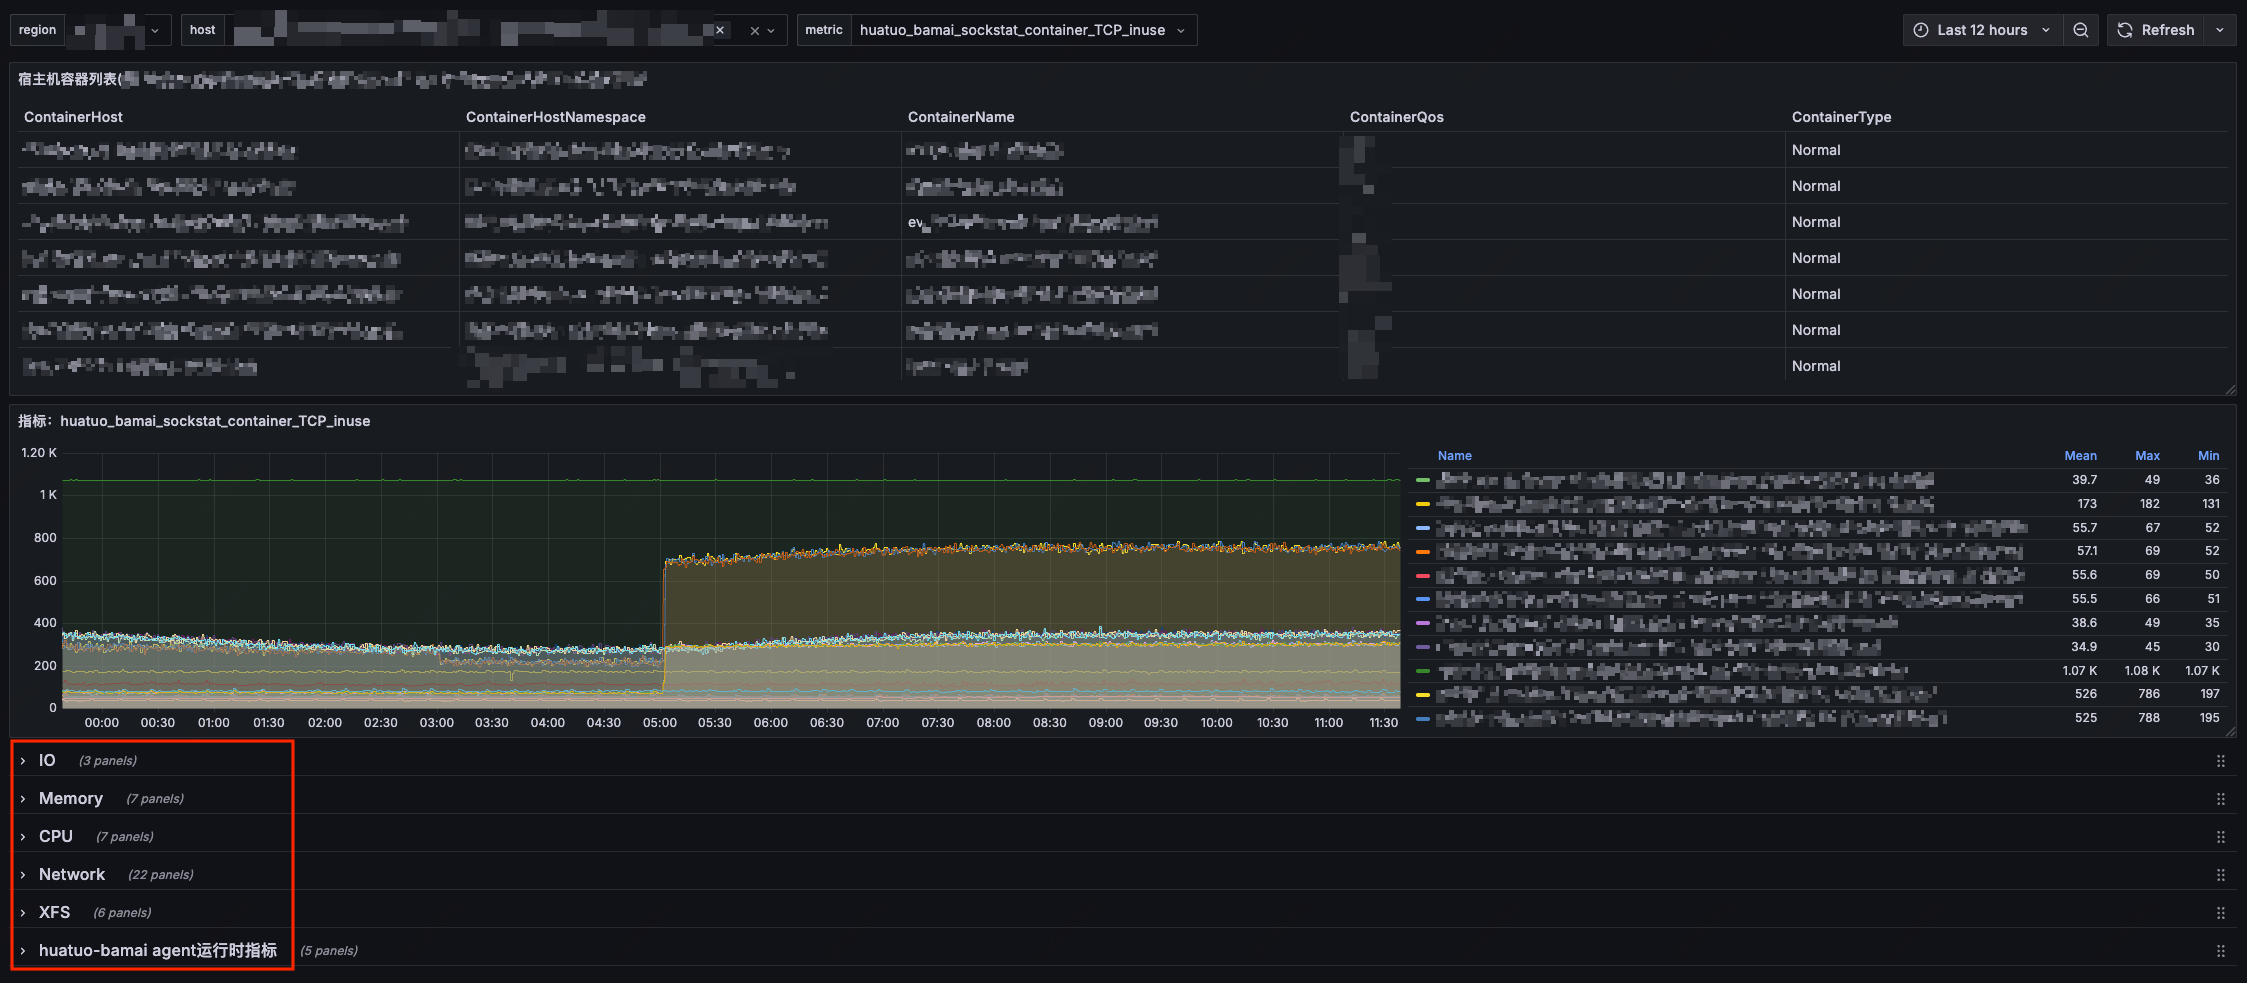
This section helps you quickly explore the frontend capabilities. You can directly access demo station, such as viewing exception event overviews, exception event context information, metric curves, etc. (Account: huatuo passwd: huatuo1024).
2. Quick Start
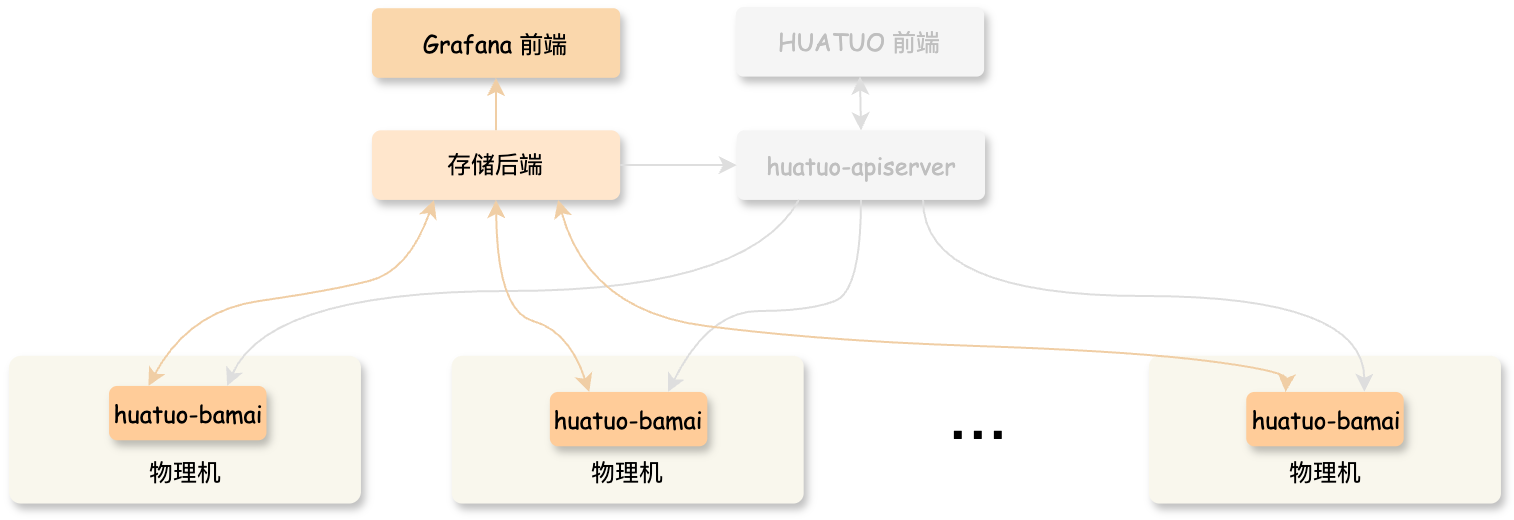
2.1 Quick Run
If you want to understand the underlying principles and deploy HUATUO to your own monitoring system, you can start pre-compiled container images via Docker (Note: This method disables container information retrieval and ES storage functionality by default).
-
Direct Execution:
$ docker run --privileged --pid=host --cgroupns=host --network=host -v /sys:/sys -v /proc:/proc -v /run:/run huatuo/huatuo-bamai:latest
-
Metric Collection:In another terminal, collect metrics
$ curl -s localhost:19704/metrics
-
View Exception Events (Events, AutoTracing):HUATUO stores collected kernel exception event information in ES (disabled by default) while retaining a copy in the local directory huatuo-local. Note: Typically, no files exist in this path (systems in normal state don’t trigger event collection). You can generate events by creating exception scenarios or modifying configuration thresholds.
2.2 Quick Setup
If you want to further understand HUATUO’s operational mechanisms, architecture design, monitoring dashboard, and custom deployment, you can quickly set up a complete local environment using docker compose.
$ docker compose --project-directory ./build/docker up
This command pulls the latest images and starts components including elasticsearch, prometheus, grafana,huatuo-bamai. After successful command execution, open your browser and visit http://localhost:3000 to access the monitoring dashboard (Grafana default admin account: admin, password: admin; Since your system is in normal state, the Events and AutoTracing dashboards typically won’t display data).
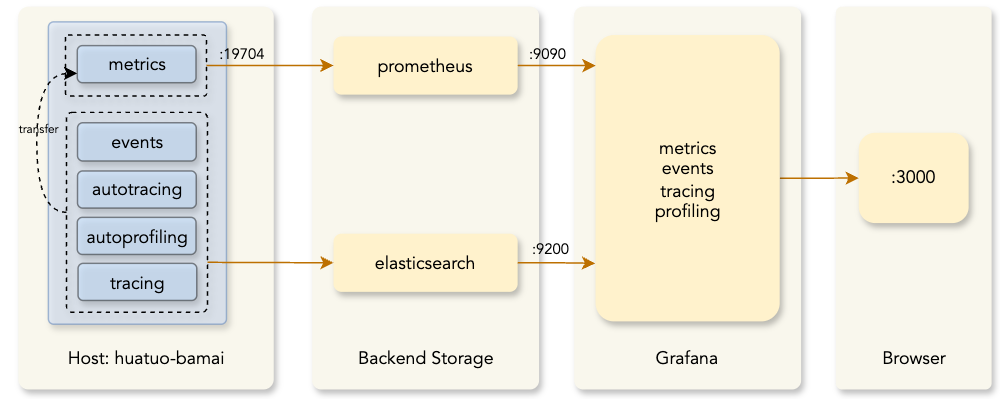
3. Compilation & Deployment
3.1 Compilation
To isolate the developer’s local environment and simplify the compilation process, we provide containerized compilation. You can directly use docker build to construct the completed image (including the underlying collector huatuo-bamai, BPF objects, tools, etc.). Run the following command in the project root directory:
$ docker build --network host -t huatuo/huatuo-bamai:latest .
3.2 Execution
-
Run container:
$ docker run --privileged --pid=host --cgroupns=host --network=host -v /sys:/sys -v /proc:/proc -v /run:/run huatuo/huatuo-bamai:latest
-
Or copy all files from the container path /home/huatuo-bamai and run manually locally:
$ ./huatuo-bamai --region example --config huatuo-bamai.conf
-
Management: Can be managed using systemd/supervisord/k8s-DaemonSet, etc.
3.3 Configuration
-
Container Information Configuration
HUATUO obtains POD/container information by calling the kubelet interface. Configure the access interface and certificates according to your actual environment. Empty configuration "" indicates disabling this functionality.
  [Pod]
    KubeletPodListURL = "http://127.0.0.1:10255/pods"
    KubeletPodListHTTPSURL = "https://127.0.0.1:10250/pods"
    KubeletPodClientCertPath = "/var/lib/kubelet/pki/kubelet-client-current.pem"
-
Storage Configuration
-
Metric Storage (Metric): All metrics are stored in Prometheus. You can access the :19704/metrics interface to obtain metrics.
-
Exception Event Storage (Events, AutoTracing): All kernel events and AutoTracing events are stored in ES. Note: If the configuration is empty, ES storage is not activated, and events are only stored in the local directory huatuo-local.
ES storage configuration is as follows:
[Storage.Elasticsearch]
    Address = "http://127.0.0.1:9200"
    Username = "elastic"
    Password = "huatuo-bamai"
    Index = "huatuo_bamai"
Local storage configuration is as follows:
# tracer's record data
# Path: all but the last element of path for per tracer
# RotationSizeMiB: maximum record file size before rotation
# MaxRotatedFiles: maximum number of rotated files to retain
[Storage.LocalFile]
    Path = "huatuo-local"
    RotationSizeMiB = 100
    MaxRotatedFiles = 10
-
Event Thresholds
All kernel event collections (Events and AutoTracing) can have configurable trigger thresholds. The default thresholds are empirical data repeatedly validated in actual production environments. You can modify thresholds in huatuo-bamai.conf according to your requirements.
-
Resource Limits
Kubernetes and systemd deployments let kubelet or systemd manage Huatuo cgroups by default, so Huatuo does not migrate its own PID. For direct execution without an external manager, pass --enable-cgroup and configure:
[Runtime]
    StartupCPULimitCores = 0.5
    CPULimitCores = 2.0
    MemoryLimitMiB = 2048
2 - Deployments
The HUATUO collector huatuo-bamai runs on physical machines or VMs. We provide both binary packages and Docker images, and you can deploy them in any way.
2.1 - Docker
Image Download
Image repository: https://hub.docker.com/r/huatuo/huatuo-bamai/tags
Start a container with Docker
docker run --detach \
  --name huatuo-bamai \
  --restart unless-stopped \
  --privileged \
  --pid=host \
  --cgroupns=host \
  --network=host \
  --cpus=2 \
  --memory=2g \
  --volume /sys:/sys \
  --volume /proc:/proc \
  --volume /run:/run \
  huatuo/huatuo-bamai:latest
Note: The built-in default configuration does not connect to kubelet or Elasticsearch.
Limit CPU and memory in production to isolate abnormal collection workloads.
Docker manages the container cgroup; Huatuo does not create its own cgroup by default,
so do not pass --enable-cgroup in a Docker deployment.
Verify that the limits are active and observe actual usage:
docker inspect huatuo-bamai \
  --format 'NanoCPUs={{.HostConfig.NanoCpus}} Memory={{.HostConfig.Memory}}'
docker stats huatuo-bamai
These values are an initial baseline. Adjust them based on node capacity,
collection jobs, and observed resource peaks.
Start containers with Docker
The docker compose command allows you to quickly set up a complete local environment where you manage the collector, Elasticsearch, Prometheus, Grafana, and other components yourself.
$ docker compose --project-directory ./build/docker up
For installation instructions, see https://docs.docker.com/compose/install/linux/.
2.2 - Kubernetes
This document describes how to deploy the Huatuo collector to a Kubernetes cluster using a DaemonSet.
1. Kubernetes Manifest Deployment
1.1 Download the configuration file
curl -L -o huatuo-bamai.conf https://github.com/ccfos/huatuo/raw/main/huatuo-bamai.conf
1.2 Modify the configuration file
Modify the configuration file for the deployment environment. For example, configure the storage backend and the method used to obtain Pod information. See the Configuration Guide for details.
1.3 Create the ConfigMap
kubectl create configmap huatuo-bamai-config \
  --namespace default \
  --from-file=./huatuo-bamai.conf \
  --dry-run=client -o yaml |
kubectl apply -f -
1.4 Deploy the collector
Download the DaemonSet manifest:
curl -L -o huatuo-daemonset.yaml \
  https://raw.githubusercontent.com/ccfos/huatuo/main/build/huatuo-daemonset.minimal.yaml
Before deploying to production, set the huatuo container resources to this
initial baseline:
resources:
  limits:
    cpu: "2"
    memory: 2Gi
  requests:
    cpu: "2"
    memory: 2Gi
Apply the modified manifest:
kubectl apply -f ./huatuo-daemonset.yaml
requests provide scheduling guarantees, while limits are enforced by the
Pod cgroup managed by kubelet. Huatuo does not create its own cgroup by default,
so it remains under kubepods and can be reclaimed normally after containerd
restart or Pod deletion.
These values are an initial baseline with matching requests and limits, so the
Pod has Guaranteed QoS. [Runtime] applies only when --enable-cgroup is
explicitly passed; do not pass that flag in Kubernetes.
1.5 Verify the deployment
kubectl rollout status daemonset/huatuo \
  --namespace default \
  --timeout=10m

kubectl get pods \
  --namespace default \
  --selector app=huatuo \
  --output wide

kubectl get daemonset huatuo \
  --namespace default \
  --output jsonpath='{.spec.template.spec.containers[?(@.name=="huatuo")].resources}'
After updating huatuo-bamai.conf, rerun section 1.3 to update the ConfigMap, then manually restart the DaemonSet:
kubectl rollout restart daemonset/huatuo --namespace default
2. Helm Deployment
The Helm Chart is located at build/charts/.
2.1 Check the deployment environment
Helm and kubectl must be installed on the management host, which must be able to access the target Kubernetes cluster.
(command -v helm || curl -fsSL https://raw.githubusercontent.com/helm/helm/main/scripts/get-helm-3 | bash) && helm version

TARGET_CONTEXT="$(kubectl config get-contexts -o name | sed -n '1p')"
kubectl --context "${TARGET_CONTEXT}" get nodes
Verify that the target Nodes are Ready.
2.2 Prepare the configuration file
Download and modify huatuo-bamai.conf as described in sections 1.1 and 1.2.
Create values-production.yaml:
image:
  repository: <registry-accessible-to-all-nodes>/huatuo-bamai
  tag: "<release-version>"
  pullPolicy: IfNotPresent

resources:
  limits:
    cpu: "2"
    memory: 2Gi
  requests:
    cpu: "2"
    memory: 2Gi

nodeSelector:
  kubernetes.io/os: linux

tolerations:
  - operator: Exists

hostPaths:
  proc: /proc
  sys: /sys
  run: /run
  var: /var
  etc: /etc
  data: /var/log/huatuo/huatuo-local
2.4 Validate the Helm Chart
helm lint ./build/charts \
  -f ./values-production.yaml \
  --set-file config.content=./huatuo-bamai.conf

helm template huatuo ./build/charts \
  --namespace huatuo \
  -f ./values-production.yaml \
  --set-file config.content=./huatuo-bamai.conf \
  >/dev/null
2.5 Deploy the collector
helm upgrade --install huatuo ./build/charts \
  --kube-context "${TARGET_CONTEXT}" \
  --namespace huatuo \
  --create-namespace \
  -f ./values-production.yaml \
  --set-file config.content=./huatuo-bamai.conf \
  --atomic \
  --timeout 10m
2.6 Verify the deployment
helm status huatuo \
  --kube-context "${TARGET_CONTEXT}" \
  --namespace huatuo

kubectl --context "${TARGET_CONTEXT}" \
  --namespace huatuo \
  get daemonset,configmap,pod --output wide

kubectl --context "${TARGET_CONTEXT}" \
  --namespace huatuo \
  rollout status daemonset/huatuo \
  --timeout=10m
Inspect the collector logs:
kubectl --context "${TARGET_CONTEXT}" \
  --namespace huatuo \
  logs \
  --selector app.kubernetes.io/name=huatuo \
  --prefix \
  --tail=100
2.7 Upgrade and roll back
After changing the image version or huatuo-bamai.conf, rerun the command in section 2.5.
List the release history and roll back to a selected revision:
helm history huatuo \
  --kube-context "${TARGET_CONTEXT}" \
  --namespace huatuo

helm rollback huatuo <revision> \
  --kube-context "${TARGET_CONTEXT}" \
  --namespace huatuo \
  --wait \
  --timeout 10m
2.3 - Bare-Metal
Production resource limits
systemd owns resource limits and process lifecycle for huatuo-bamai.service. The service unit disables Huatuo self-managed cgroups and uses native controls:
[Service]
CPUAccounting=yes
CPUQuota=200%
MemoryAccounting=yes
MemoryMax=2G
TasksAccounting=yes
TasksMax=32768
KillMode=control-group
CPUQuota=200% allows up to 2 CPU cores and MemoryMax=2G caps service memory. Adjust these values for the host, collection jobs, and observed peaks. Do not pass --enable-cgroup in a systemd deployment; it would move the process out of the service cgroup.
After starting the service, check its status and cgroup:
systemctl status huatuo-bamai --no-pager
systemd-cgls --unit huatuo-bamai.service
Binary
The HUATUO release provides static Linux tar packages for amd64 and arm64. The tar package contains the huatuo-bamai and huatuo-apiserver binaries, configuration files, and BPF objects.
This section applies to releases that provide assets named huatuo-bamai-<version>-static-linux-<arch>.tar.gz. This naming starts with v2.2.0 in the current releases. The v2.0.0 and v2.1.0 tar packages use different names, so the commands below do not apply to them directly.
The commands below use HUATUO_VERSION for the target version. Change it to the release version you want to install, for example v2.2.0:
HUATUO_VERSION="<release-version>"
1. Download the tar package
For x86_64 hosts, download the amd64 package:
wget "https://github.com/ccfos/huatuo/releases/download/${HUATUO_VERSION}/huatuo-bamai-${HUATUO_VERSION}-static-linux-amd64.tar.gz"
For aarch64 hosts, download the arm64 package:
wget "https://github.com/ccfos/huatuo/releases/download/${HUATUO_VERSION}/huatuo-bamai-${HUATUO_VERSION}-static-linux-arm64.tar.gz"
2. Install the tar package
Create the installation, log, and data directories:
sudo install -d -m 0755 /opt/huatuo-bamai /var/log/huatuo-bamai /var/lib/huatuo-bamai
For amd64:
sudo tar -xzf "huatuo-bamai-${HUATUO_VERSION}-static-linux-amd64.tar.gz" --strip-components=1 --no-same-owner -C /opt/huatuo-bamai
For arm64:
sudo tar -xzf "huatuo-bamai-${HUATUO_VERSION}-static-linux-arm64.tar.gz" --strip-components=1 --no-same-owner -C /opt/huatuo-bamai
3. Install the service unit files
Download the service unit files from the matching source version:
sudo wget -O /etc/systemd/system/huatuo-bamai.service "https://raw.githubusercontent.com/ccfos/huatuo/${HUATUO_VERSION}/build/rpm/huatuo-bamai.service"
sudo wget -O /etc/systemd/system/huatuo-apiserver.service "https://raw.githubusercontent.com/ccfos/huatuo/${HUATUO_VERSION}/build/rpm/huatuo-apiserver.service"
4. Modify the configurations
Edit /opt/huatuo-bamai/conf/huatuo-bamai.conf and /opt/huatuo-bamai/conf/huatuo-apiserver.conf to match the deployment environment. For detailed configuration options, see the huatuo-bamai configuration and huatuo-apiserver configuration.
Set CPUQuota, MemoryMax, and TasksMax in the service unit. Configure [Runtime] only for direct execution with --enable-cgroup.
5. Register the HUATUO services
Reload the systemd configuration:
sudo systemctl daemon-reload
6. Start the HUATUO services
Start the services and enable them at system startup:
sudo systemctl enable --now huatuo-bamai huatuo-apiserver
RPM Package
The OpenCloudOS repository provides HUATUO v2.1.0 RPM packages for x86_64 and aarch64. The RPM package installs the HUATUO files and systemd service unit file.
1. Download the RPM package
Download the package for the host architecture:
For x86_64:
wget https://mirrors.opencloudos.tech/epol/9/Everything/x86_64/os/Packages/huatuo-bamai-2.1.0-2.oc9.x86_64.rpm
For aarch64:
wget https://mirrors.opencloudos.tech/epol/9/Everything/aarch64/os/Packages/huatuo-bamai-2.1.0-2.oc9.aarch64.rpm
2. Install the RPM package
For x86_64:
sudo dnf install ./huatuo-bamai-2.1.0-2.oc9.x86_64.rpm
For aarch64:
sudo dnf install ./huatuo-bamai-2.1.0-2.oc9.aarch64.rpm
3. Modify the configuration
Edit /etc/huatuo-bamai/huatuo-bamai.conf to match the deployment environment. For detailed configuration options, see the huatuo-bamai configuration.
Set CPUQuota, MemoryMax, and TasksMax in the service unit. Configure [Runtime] only for direct execution with --enable-cgroup.
4. Start the HUATUO service
The RPM package installs the huatuo-bamai.service service unit file. Start the service and enable it at system startup:
sudo systemctl enable --now huatuo-bamai
For complete RPM installation instructions, see https://mp.weixin.qq.com/s/Gmst4_FsbXUIhuJw1BXNnQ.
3 - Building from Source
1. Container Build
Run the following command to build the project and run static code checks.
$ sh build/build-run-testing-image.sh
Or run each step separately:
1. Prepare the build environment
$ docker build --network host -t huatuo/huatuo-bamai-dev:latest -f ./Dockerfile.devel .
2. Start the build container
$ docker run -it --pid=host --privileged --cgroupns=host --network=host -v $(pwd):/go/huatuo-bamai huatuo/huatuo-bamai-dev:latest sh
3. Build inside the container
2. Publishing the Image
Use docker build to publish the latest binary container image.
docker build --network host -t huatuo/huatuo-bamai:latest .
3.1 Install Dependencies
Ubuntu 24.04:
apt install make git clang libbpf-dev linux-tools-common curl capnproto
Fedora 40:
dnf install make git clang libbpf-devel bpftool curl capnproto capnproto-devel glibc-static
go install mvdan.cc/gofumpt@v0.8.0
go install mvdan.cc/sh/v3/cmd/shfmt@v3.11.0
go install golang.org/x/tools/cmd/goimports@v0.36.0
go install github.com/golangci/golangci-lint/cmd/golangci-lint@v1.62.2
go install github.com/vektra/mockery/v2@v2.53.6
go install capnproto.org/go/capnp/v3/capnpc-go@v3.1.0-alpha.2
3.2 Build
4. BPF Debug Build
Set BPF_DEBUG=1 to pass -DDEBUG_BPF to clang and compile the debug code into the BPF object:
$ make BPF_DEBUG=1 # Or regenerate artifacts only: make BPF_DEBUG=1 gen-build
See Debugging for trace points, runtime switches,
and log output.
4 - Configuration Guide
Configuration guides for huatuo-bamai and huatuo-apiserver.
4.1 - huatuo-bamai Configuration
1. Overview
huatuo-bamai is the core collector of HUATUO (a BPF-based metrics and anomaly inspector). Its configuration file defines the data collection scope, probe enablement strategy, metric output format, anomaly detection rules, and logging behavior.
The configuration file uses TOML format and includes multiple sections such as global blacklist, logging, runtime resource limits, storage configuration, and AutoTracing. Each configuration item comes with detailed comments explaining its purpose, default value, and important notes. This document provides a clear and detailed English explanation for every configuration item to help users understand and safely customize the settings.
Note: Most parameters are provided as commented defaults (prefixed with #). Uncomment and adjust as needed. Changes take effect after restarting huatuo-bamai. In production, avoid enabling high-overhead features unnecessarily.
2. Global Blacklist
# Global tracing and metrics configuration.
#
# - BlackList
# Global blacklist for tracing and metrics.
#
BlackList = ["netdev_hw", "netdev_qdisc", "metax_gpu", "ascend_npu", "diskio", "tcp_retransmit", "mthreads_gpu"]
-
BlackList: Global blacklist for tracing and metrics.
Modules or hardware to exclude from tracing and metric collection. The default is ["netdev_hw", "netdev_qdisc", "metax_gpu", "ascend_npu", "diskio", "tcp_retransmit", "mthreads_gpu"], which disables tracing and metrics for the network device hardware layer, qdisc statistics, Metax GPU, Ascend NPU, procfs-based disk I/O statistics, TCP retransmission tracing, and Moore Threads GPU. Remove diskio to enable disk I/O metrics, tcp_retransmit to enable TCP retransmission tracing, or mthreads_gpu to enable Moore Threads GPU metric collection on hosts with MT GPUs. Local correlation does not require the standalone dropwatch tracer. Supports arrays; extend as needed.
3. Logging
# Log Configuration
[Log]
    # - Level
    # The log level for huatuo-bamai: Debug, Info, Warn, Error, Panic.
    # Default: Info
    #
    # - File
    # Store logs to where the logging file is. If it is empty, don't write log
    # to any file.
    # Default: empty
    #
    # Level = "Info"
    # File = ""
-
Level: Log verbosity. Values: Debug, Info, Warn, Error, Panic. Default: Info. Use Info or Warn in production; Debug for troubleshooting.
-
File: Log file path.
Specifies the path to the log file. If left empty, logs are not written to any file (output goes to stdout or system logs).
Default: empty.
Description: In containerized deployments, configure a specific path and integrate with a log collection system for persistence.
4. Runtime Resource Limits
Huatuo does not create its own cgroup by default. This section applies only when --enable-cgroup is passed; Kubernetes and systemd deployments should use their native resource controls.
# Runtime limits for the huatuo-bamai process.
[Runtime]
    # - StartupCPULimitCores
    # CPU limit during startup, in cores.
    # Default: 0.5
    #
    # - CPULimitCores
    # CPU limit after startup, in cores.
    # Default: 2.0
    #
    # - MemoryLimitMiB
    # Memory limit in MiB.
    # Default: 2048
    #
    # StartupCPULimitCores = 0.5
    # CPULimitCores = 2.0
    # MemoryLimitMiB = 2048
- StartupCPULimitCores limits CPU usage during initialization. Default:
0.5 cores.
- CPULimitCores limits CPU usage after startup. Default:
2.0 cores.
- MemoryLimitMiB limits process memory. Default:
2048 MiB.
The configured values remain in their documented units. Memory is converted
to bytes only when the cgroup limit is applied.
5. HTTP Server and On-demand Operations
# HTTP server configuration.
[HTTPServer]
    # - ListenAddress
    # Listen address in "host:port" form.
    # Default: ":19704"
    #
    # - MaxEventStreamClients
    # Maximum number of concurrent clients allowed to hold an open
    # /v1/events/watch SSE connection. Once the limit is reached, new requests
    # are rejected with HTTP 429 until an existing client disconnects.
    # Default: 100
    #
    # - EventStreamKeepAliveIntervalSeconds
    # Interval in seconds at which the server sends an SSE comment ping to each
    # connected client. The ping keeps the connection alive through load
    # balancers and proxies that would otherwise time out idle connections. If
    # writing the ping fails three consecutive times, the server closes the
    # connection.
    # Default: 30
    #
    # ListenAddress = ":19704"
    # MaxEventStreamClients = 100
    # EventStreamKeepAliveIntervalSeconds = 30

[HTTPServer.Auth]
    # Required service credential used by huatuo-apiserver.
    BearerToken = "REPLACE_WITH_RANDOM_HEX"

# Shared lifecycle policy for Profiling and Tracing operations.
[Operations]
    # MaxConcurrent = 10
    # LaunchTimeoutSeconds = 10
    # StopGracePeriodSeconds = 5
    # FinalizationTimeoutSeconds = 30
    # TerminalRetentionPeriodSeconds = 600

# Node-local profiler execution settings.
[Profiling]
    # AggregationIntervalSeconds = 10
    # MaxConcurrentProcesses = 10
    # CommandOutputLimitBytes = 65536
    # ToolDir = "/opt/huatuo/tools"
- ListenAddress uses
host:port form. An empty host listens on all
interfaces.
- HTTPServer.Auth.BearerToken is required and must match the independent
Node credential configured for huatuo-apiserver. Replace the example value
before deployment.
- Operations.MaxConcurrent is one process-wide limit shared by Profiling
and Tracing. New operations are rejected instead of queued when it is full.
- The four operation time settings independently limit process launch,
graceful stop, result finalization, and terminal-state retention.
- Profiling.ToolDir is the shared external tool root, passed unchanged as
profiler
--tool-path. Java requires bin/asprof and
lib/libasyncProfiler.so beneath this root; Python requires
py-spy. Only the requested language’s tools are checked. Native profiling
does not require this setting. Unsupported node environments reject the request
without creating an operation.
The generated Node API exposes its contract at GET /openapi.json. Profiling
and Tracing Start, Get, and Stop routes, POST /v1/events/watch, and
PUT /v1/config require the service bearer token. /readyz, metrics, version,
and the OpenAPI document remain public.
5.1 Update Configuration through the Node API
PUT /v1/config accepts one non-empty config object. Keys use the same
dot-separated paths as the TOML structure, while values retain their JSON
types:
curl -i -X PUT 'http://127.0.0.1:19704/v1/config' \
  -H 'Authorization: Bearer REPLACE_WITH_RANDOM_HEX' \
  -H 'Content-Type: application/json' \
  --data '{
    "config": {
      "BlackList": ["dropwatch", "netdev_hw"],
      "Runtime.CPULimitCores": 1.5,
      "Runtime.MemoryLimitMiB": 1024
    }
  }'
A successful update returns 204 No Content. The Node Agent validates the
complete candidate configuration, atomically replaces the configuration file,
and only then publishes the new in-memory snapshot. Validation or persistence
failure leaves the current snapshot unchanged. Unknown keys, invalid value
types, and empty update objects return 400 Bad Request.
Components that read configuration dynamically can observe the new snapshot
without a restart. Settings consumed during startup, including the HTTP
listener and authentication, storage initialization, and cgroup setup, are
persisted but take effect only after restarting huatuo-bamai.
The event stream settings control POST /v1/events/watch. When
MaxEventStreamClients is reached, new streams receive HTTP 429.
EventStreamKeepAliveIntervalSeconds controls SSE heartbeat comments used to
keep proxy and load-balancer connections alive. After three consecutive write
failures, the server closes the stream. Set the interval below any upstream
idle timeout; 15–60 seconds is typical.
6. Storage
6.1 Elasticsearch and OpenSearch Storage
# Storage configuration
[Storage]
    # Elasticsearch and OpenSearch Storage
    #
    # Disable ES/OS storage if one of Address, Username, Password is empty.
    # Store the tracing and events data of linux kernel to ES/OS.
    #
    # - Address
    # Port 9200 is commonly used for Elasticsearch/OpenSearch HTTP APIs.
    # e.g.
    # http://127.0.0.1:9200
    # https://127.0.0.1:9200
    #
    # - Index
    # Elasticsearch or OpenSearch index, a logical namespace that holds a collection of
    # documents for huatuo-bamai.
    # Default: huatuo_bamai
    #
    # - Username
    # - Password
    # Address, Username, and Password must be either all empty (disabled) or
    # all configured (enabled). Partial connection settings are invalid.
    #
    [Storage.Elasticsearch]
        # Address = "http://127.0.0.1:9200"
        # Index = "huatuo_bamai"
        # Username = "elastic"
        # Password = "REPLACE_WITH_PASSWORD"
-
Address: ElasticSearch/OpenSearch service address.
No default value.
Description: Used to store kernel tracing and event data. ES/OS storage
is disabled when Address, Username, and Password are all empty. All three
values are required when storage is enabled; a partial configuration
prevents startup.
-
Index: Index name.
Default: huatuo_bamai.
Description: Logical namespace for organizing huatuo-bamai tracing and event documents.
-
Username: Authentication username.
No default value.
Description: Used for Basic Auth.
-
Password: Authentication password.
No default value.
Description: Used together with the username. In production, use a strong password and enable TLS encryption.
Overall: ES/OS storage persists kernel tracing and event data for later search and analysis.
6.2 Local File Storage
# LocalFile Storage
#
# Store data to local directory for troubleshooting on the host machine.
#
# - Path
# The directory for storing data. If the Path is empty, LocalFile will be disabled.
# Default: "huatuo-local"
#
# - RotationSizeMiB
# The maximum size in Megabytes of a record file before it gets rotated
# per kernel tracer.
# Default: 100MB
#
# - MaxRotatedFiles
# The maximum number of old log files to retain for per tracer.
# Default: 10
#
[Storage.LocalFile]
    # Path = "huatuo-local"
    # RotationSizeMiB = 100
    # MaxRotatedFiles = 10
-
Path: Local data storage directory.
Default: huatuo-local. If empty, local file storage is disabled.
Description: Stores data locally on the host for on-site troubleshooting. Use an absolute path.
-
RotationSizeMiB: Single file rotation size.
Maximum size of a record file before rotation (per tracer).
Default: 100 MB.
Description: Prevents any single file from growing too large and consuming excessive disk space.
-
MaxRotatedFiles: Maximum number of rotated files to retain.
Default: 10.
Description: Oldest files are automatically deleted once the limit is reached, controlling disk usage.
7. Automatic Tracing
The automatic tracing module is one of HUATUO’s intelligent features. It triggers specific performance tracing based on thresholds, reducing manual intervention.
7.1 CPUIdle Automatic Tracing — Sudden High CPU Usage in Containers
# Autotracing configuration
[AutoTracing]
    # cpuidle
    #
    # For sudden high CPU usage in containers.
    #
    # - UserThreshold
    # User CPU usage threshold, when cpu usage reaches this threshold, cpu
    # performance tracing will be triggered.
    # Default: 75%
    #
    # - SysThreshold
    # System CPU usage threshold, when reaching this threshold, cpu performance
    # tracing will be triggered.
    # Default: 45%
    #
    # - UsageThreshold
    # The total cpu usage (system + user cpu usage) threshold, when reaching
    # this threshold, cpu performance tracing will be triggered.
    # Default: 45%
    #
    # - DeltaUserThreshold
    # The range of this user cpu changes within a short period of time.
    # Default: 45%
    #
    # - DeltaSysThreshold
    # The range of this system cpu changes within a short period of time.
    # Default: 20%
    #
    # - DeltaUsageThreshold
    # The range of this cpu usage changes within a short period of time.
    # Default: 55%
    #
    # - Interval
    # The sample interval of the cpu usage for all containers.
    # Default: 10s
    #
    # - IntervalTracing
    # Time since last run. Avoid frequently executing this tracing to prevent
    # performance impact.
    # Default: 1800s
    #
    # - RunTracingToolTimeout
    # Execution timeout of this tracing tool (seconds).
    # Default: 10s
    #
# NOTE:
# Profiling triggers when:
# 1. UserThreshold AND DeltaUserThreshold are exceeded, or
# 2. SysThreshold AND DeltaSysThreshold are exceeded, or
# 3. UsageThreshold AND DeltaUsageThreshold are exceeded
    #
    [AutoTracing.CPUIdle]
        # UserThreshold = 75
        # SysThreshold = 45
        # UsageThreshold = 90
        # DeltaUserThreshold = 45
        # DeltaSysThreshold = 20
        # DeltaUsageThreshold = 55
        # Interval = 10
        # IntervalTracing = 1800
        # RunTracingToolTimeout = 10
-
UserThreshold: User-mode CPU usage threshold (%).
Default: 75%.
-
SysThreshold: System-mode CPU usage threshold (%).
Default: 45%.
-
UsageThreshold: Total CPU usage threshold (%).
Default: 90% (as shown in comments).
-
DeltaUserThreshold: Short-term user CPU change threshold (%).
Default: 45%.
-
DeltaSysThreshold: Short-term system CPU change threshold (%).
Default: 20%.
-
DeltaUsageThreshold: Short-term total CPU change threshold (%).
Default: 55%.
-
Interval: CPU usage sampling interval (seconds).
Default: 10s.
-
IntervalTracing: Minimum interval between runs (seconds).
Default: 1800s (30 minutes).
-
RunTracingToolTimeout: Single tracing execution timeout (seconds).
Default: 10s.
Trigger Logic: Tracing runs when any of the following is true:
- Both UserThreshold and DeltaUserThreshold are met, or
- Both SysThreshold and DeltaSysThreshold are met, or
- Both UsageThreshold and DeltaUsageThreshold are met.
Filter Container Filtering: Use Included/Excluded rule arrays to control monitoring scope.
    # Each rule contains Field (filter field) and Pattern (regex).
    # Field: container_host_namespace | container_hostname | container_qos
    #
    # [[AutoTracing.CPUIdle.Filter.Excluded]]
    #     Field = "container_qos"
    #     Pattern = "besteffort"
    # [[AutoTracing.CPUIdle.Filter.Included]]
    #     Field = "container_host_namespace"
    #     Pattern = "^application-"
-
Filter: Container filtering rules. Defined using [[double-bracket]] syntax with multiple rules, each containing Field (filter field) and Pattern (regex). Filtering logic:
- No rules: monitor all containers
Excluded only: blacklist, skip matched containersIncluded only: whitelist, only monitor matched containers- Both: must match Included AND not match Excluded
Default: no rules, all containers monitored.
7.2 CPUSys Automatic Tracing — Sudden High System CPU on Host
# cpusys
#
# For sudden high system cpu usage on the host machine.
#
# - SysThreshold
# System CPU usage threshold, when reaching this threshold, cpu performance
# tracing will be triggered.
# Default: 45%
#
# - DeltaSysThreshold
# The range of system cpu changes within a short period of time.
# Default: 20%
#
# - Interval
# The sample interval of the cpu usage for host machine.
# Default: 10s
#
# - IntervalTracing
# Minimum time between profiling runs.
# Default: 1800s
#
# - RunTracingToolTimeout
# Execution timeout of this tracing tool (seconds).
# Default: 10s
#
# NOTE:
# Profiling triggers when:
# SysThreshold AND DeltaSysThreshold are exceeded.
#
[AutoTracing.CPUSys]
	# SysThreshold = 45
	# DeltaSysThreshold = 20
	# Interval = 10
	# IntervalTracing = 1800
	# RunTracingToolTimeout = 10
-
SysThreshold: System CPU usage threshold (%).
Default: 45%.
-
DeltaSysThreshold: Short-term system CPU change threshold (%).
Default: 20%.
-
Interval: Host CPU usage sampling interval (seconds).
Default: 10s.
-
IntervalTracing: Minimum time between profiling runs. Default: 1800s.
-
RunTracingToolTimeout: Tracing execution timeout (seconds).
Default: 10s.
Trigger Logic: Tracing is triggered when both SysThreshold and DeltaSysThreshold are satisfied.
7.3 Dload AutoTracing — D-State Task Profiling for Containers
# dload
#
# linux tasks D state profiling for containers.
#
# - ThresholdLoad
# Load average threshold. When exceeded, D-state profiling triggers.
# Default: 5
#
# - Interval
# The sample interval of the load for all containers.
# Default: 10s
#
# - IntervalTracing
# Time since last run. Avoid frequently executing this tracing to prevent
# performance impact.
# Default: 1800s
#
[AutoTracing.Dload]
	# ThresholdLoad = 5
	# Interval = 10
	# IntervalTracing = 1800
-
ThresholdLoad: System load average (loadavg) threshold for containers.
Default: 5. Triggers D-state (uninterruptible sleep) task profiling when loadavg reaches this value.
-
Interval: Monitoring interval.
Default: 10s.
-
IntervalTracing: Minimum time between consecutive tracings.
Default: 1800s (30 minutes).
# iotracing
#
# io profiling for containers.
#
# - WbpsThreshold
# Max write bytes per second threshold. When exceeded, iotracing is triggered.
# For NVMe devices, UtilThreshold must also be met.
# Default: 1500 MB/s
#
# - RbpsThreshold
# Max read bytes per second threshold. When exceeded, iotracing is triggered.
# For NVMe devices, UtilThreshold must also be met.
# Default: 2000 MB/s
#
# - UtilThreshold
# Disk utilization (%). Consistently above 80-90% indicates a bottleneck.
# Default: 90%
#
# - AwaitThreshold
# Await (Average IO wait time in ms): High values indicate slow disk response times.
# Default: 100ms
#
# - RunTracingToolTimeout
# Execution timeout of this tracing tool (seconds).
# Default: 10s
#
# - MaxProcDump
# The number of processes displayed by iotracing tool.
# Default: 10
#
# - MaxFilesPerProcDump
# The number of files per process displayed by iotracing tool.
# Default: 5
#
[AutoTracing.IOTracing]
	# WbpsThreshold = 1500
	# RbpsThreshold = 2000
	# UtilThreshold = 90
	# AwaitThreshold = 100
	# RunTracingToolTimeout = 10
	# MaxProcDump = 10
	# MaxFilesPerProcDump = 5
-
WbpsThreshold: Max write bytes per second threshold (MB/s).
Default: 1500. (For NVMe, must also meet UtilThreshold.)
-
RbpsThreshold: Max read bytes per second threshold (MB/s).
Default: 2000.
-
UtilThreshold: Disk utilization threshold (%).
Default: 90%.
-
AwaitThreshold: Average IO wait time threshold (ms).
Default: 100ms.
-
RunIOTracingTimeout: IO tracing tool timeout (seconds).
Default: 10s.
-
MaxProcDump: Maximum number of processes to display.
Default: 10.
-
MaxFilesPerProcDump: Maximum files per process to display.
Default: 5.
Description: Used for diagnosing IO hotspots in containers, especially under high disk load.
7.5 MemoryBurst AutoTracing
This module detects sudden memory usage spikes on the host and automatically captures kernel context to help diagnose memory pressure events.
# memory burst
#
# Capture kernel context on sudden host memory usage spikes.
#
# - Interval
# Memory usage sampling interval (seconds).
# Default: 10s
#
# - DeltaMemoryBurst
# Growth percentage threshold for memory usage. 100% means, e.g.,
# memory usage increased from 200MB to 400MB.
# Default: 100%
#
# - DeltaAnonThreshold
# Growth percentage threshold for anonymous memory. 100% means, e.g.,
# anon memory increased from 200MB to 400MB.
# Default: 70%
#
# - IntervalTracing
# Time since last run. Avoid frequently executing this tracing
# to prevent performance impact.
# Default: 1800s
#
# - DumpProcessMaxNum
# Number of processes to dump when triggered.
# Default: 10
#
[AutoTracing.MemoryBurst]
	# DeltaMemoryBurst = 100
	# DeltaAnonThreshold = 70
	# Interval = 10
	# IntervalTracing = 1800
	# SlidingWindowLength = 60
	# DumpProcessMaxNum = 10
-
DeltaMemoryBurst: Memory usage burst growth percentage threshold.
Default: 100%.
-
DeltaAnonThreshold: Anonymous memory burst growth percentage threshold.
Default: 70%.
-
Interval: Memory usage sampling interval (seconds).
Default: 10s.
-
IntervalTracing: Minimum interval between runs (seconds).
Default: 1800s.
-
SlidingWindowLength: Sliding window length (seconds).
Default: 60s.
-
DumpProcessMaxNum: Maximum processes to dump on trigger.
Default: 10.
7.6 Memory Threshold Runtime Snapshots
memory_threshold_snapshot is enabled by default. Add it to the global BlackList
and restart huatuo-bamai to disable it.
This feature attempts a Go, HotSpot, or CPython snapshot
after a container memory-pressure notification; completion before OOM is not
guaranteed. Candidates are ranked by an approximate kernel OOM score.
The persisted victim_pid, victim_process_name, and victim_oom_score_adj
fields describe the process selected for snapshot capture.
[AutoTracing.MemoryThresholdSnapshot]
    # ThresholdPercent = 90
    # IntervalTracing = 300
    # RunTracingToolTimeout = 2
    # MaxMemoryObjectEntries = 10
Commented values are defaults.
| Parameter |
Meaning |
| ThresholdPercent |
Required memory usage-to-limit percentage, from 1 to 100 |
| IntervalTracing |
Node-wide minimum interval after a successful or failed capture attempt, in seconds; defaults to 300 and must be positive |
| RunTracingToolTimeout |
Cooperative capture timeout shared by Go, Java, and Python, in seconds; defaults to 2 and must be positive |
| MaxMemoryObjectEntries |
Maximum number of ranked memory object entries in a snapshot, from 1 to 100; defaults to 10; final JSON is trimmed to at most 512 KiB |
Runtime detection and persistence are not included in the capture budget.
Runtime detection has no separate timeout. Timeouts cannot interrupt synchronous reads
already executing, so they do not bound the total operation time.
Trigger conditions:
- Cgroup v1: Registers the memory threshold corresponding to
ThresholdPercent through cgroup.event_control.
- Cgroup v2: Watches increases in the
high or max counters of
memory.events.local (falling back to memory.events when absent), then
checks memory.current / memory.max against the configured percentage.
This feature does not set memory.high. When it is max, the hard-limit
max counter can still trigger a check. This is a late notification and
does not guarantee detection at the configured percentage or before OOM.
Both versions check usage once after registration and when the hard limit
changes. One watcher manages all targets without periodic sampling. Repeated
notifications for a target are coalesced; they do not count every crossing or
report recovery below the threshold. Capture rechecks current usage and identity.
This feature requires the pod manager. It actively maintains the container view
from shared CSS lifecycle hints and supplies an initial view followed by events
with instance generations, init PIDs, and memory cgroup paths. The snapshot module
no longer scans the cgroup tree. Subscription overflow recovers from a complete
pod view; synchronization failure suspends capture and never implies deletion.
Running ordinary containers and restartable init sidecars are monitored;
ephemeral debug containers and ordinary init containers are excluded. Ordinary
registration errors and target capacity exhaustion are logged and the directory
instance is skipped. Invalidated registrations are removed without automatic
retries or backfilling. Repeated events, full views, and container generation changes
do not restore a failed watch. A replacement directory, a new tracking lifetime
after the previous container departs, or a huatuo-bamai restart allows a new attempt.
Fatal errors such as host resource exhaustion still stop the current watcher.
Each monitored container must have its own memory cgroup directory. A watch
and its capture observations bind directly to one container instance. If registration
returns a watch already owned by another container, the feature stops, cancels capture,
and releases its watches. Correct the cgroup isolation and restart huatuo-bamai;
the feature does not retry this conflict. Directory replacement invalidates the old
registration through the watcher’s removal notification.
Before capture and saving, the feature verifies the container generation and live
binding, directory identity, and selected process identity and cgroup membership.
Recorded memory usage and limits belong to that container’s cgroup.
See section 14 for deployment limitations and output lookup.
7.7 IRQTracing AutoTracing
This module detects abnormal irq+softirq utilization on one CPU and invokes
irqtracing to collect softirq source and victim stacks.
[AutoTracing.IRQTracing]
    Interval = 2
    RunTracingToolTimeout = 3
    IntervalTracing = 300
    MaxEventsPerSecond = 1000
    MinCPUs = 3
    DeltaUsageThreshold = 20
    RelativeIncreaseThreshold = 30
    SustainedIntervals = 10
    UsageThreshold = 80
- Interval: Sampling interval for per-CPU irq+softirq utilization from
/proc/stat. Default: 2s.
- RunTracingToolTimeout: Duration of one
irqtracing collection. Default:
3s.
- IntervalTracing: Minimum interval between triggers. Default: 300s.
- MaxEventsPerSecond: Combined source and victim stack-sample limit per
second on the traced CPU. Default: 1000. The daemon divides it as evenly as
possible between
softirq_raise and softirq_entry; the default is 500
events/s per stream. The value must be between 2 and 8589934590.
- MinCPUs, DeltaUsageThreshold, and RelativeIncreaseThreshold:
Configure the multi-CPU irq+softirq spike rule. The two thresholds are the
increase in percentage points and the increase relative to the previous
sample, respectively.
- SustainedIntervals and UsageThreshold: Configure the consecutive
sample count and utilization threshold for the single-CPU sustained rule.
7.8 Known Issue Filtering (IssuesList)
# Autotracing configuration.
#
# - IssuesList
# Known issue filters for autotracing.
#
[AutoTracing]
    IssuesList = []
-
IssuesList: Known issue filter. Format: [["name", "regex"], ...]. When a collected stack trace matches the regex, it is labeled with the issue name. Default [].
Example: IssuesList = [["known_issue1", "softlockup"], ["known_issue2", "alloc_pages.*failed"]]
Note: Only supports dload tracing of known issues filtering, other events are not supported.
8. Event Tracing
This section captures key kernel events and latency, including scheduler tick intervals, memory reclaim, network receive latency, network device events, and packet drops. It is the core module for kernel-level anomaly context collection in HUATUO.
8.1 Scheduler Tick Interval Tracing
# linux kernel events capturing configuration
[EventTracing]
	# scheduler tick
	#
	# Trace long scheduler tick intervals.
	#
	# - IntervalThreshold
	# When the scheduler tick interval reaches the threshold, huatuo-bamai
	# will collect kernel context.
	# Default: 10000000 in nanoseconds, 10ms
	#
	[EventTracing.SchedTick]
		# IntervalThreshold = 10000000
-
IntervalThreshold: Scheduler tick interval threshold, in nanoseconds.
Default: 10,000,000 ns (10ms).
Description: The event infers CPU stalls from long scheduler tick intervals. It does not by itself prove that softirqs were disabled.
8.2 Memory Reclaim Blocking Tracing
# memreclaim
#
# The memory reclaim may block the process, if one process is blocked
# for a long time, reporting the events to userspace.
#
# - BlockedThreshold
# The blocked time when memory reclaiming.
# Default: 900000000ns, 900ms
#
[EventTracing.MemoryReclaim]
	# BlockedThreshold = 900000000
-
BlockedThreshold: Memory reclaim blocking time threshold (nanoseconds).
Default: 900,000,000 ns (900ms). When a process is blocked by memory reclaim for longer than this time, an event is reported to userspace with context.
Description: Memory reclaim blocking is a common cause of process stalls, especially in memory-constrained cloud-native environments.
8.3 Network Receive Latency Tracing
# networking rx latency
#
# linux net stack rx latency for every tcp skbs.
#
# - Driver2NetRx
# The latency from driver to net rx, e.g., netif_receive_skb.
# Default: 5ms
#
# - Driver2TCP
# The latency from driver to tcp rx, e.g., tcp_v4_rcv.
# Default: 10ms
#
# - Driver2Userspace
# The latency from driver to userspace copy data, e.g., skb_copy_datagram_iovec.
# Default: 115ms
#
# - ExcludedContainerQos
# Blacklist: skip containers whose qos level matches.
# Values: "guaranteed", "burstable", "besteffort" (case-insensitive).
# Default: [].
#
# - ExcludedHostNetnamespace
# Exclude packets in the host network namespace.
# Default: true
#
[EventTracing.NetRxLatency]
	# Driver2NetRx = 5
	# Driver2TCP = 10
	# Driver2Userspace = 115
	# ExcludedContainerQos = []
	ExcludedContainerQos = ["besteffort"]
	# ExcludedHostNetnamespace = true
-
Driver2NetRx: Latency threshold from driver to network receive layer (e.g., netif_receive_skb).
Default: 5ms.
-
Driver2TCP: Latency threshold from driver to TCP receive (e.g., tcp_v4_rcv).
Default: 10ms.
-
Driver2Userspace: Latency threshold from driver to userspace data copy (e.g., skb_copy_datagram_iovec).
Default: 115ms.
-
ExcludedContainerQos: Container QoS levels to exclude (blacklist).
Default: []. Corresponds to Kubernetes Pod QoS levels (Guaranteed, Burstable, BestEffort).
-
ExcludedHostNetnamespace: Whether to exclude packets in the host network namespace.
Default: true.
8.4 Network Device Event Monitoring
# netdev events
#
# Monitor network device events.
#
# - DeviceList
# The net devices we monitor.
# Default: [] (empty, meaning no devices).
#
[EventTracing.Netdev]
	DeviceList = ["eth0", "eth1", "bond4", "lo"]
-
DeviceList: List of network device full-match regex patterns to monitor. Literal names such as "eth0" keep exact-match behavior; patterns such as "bond[0-9]+" can select multiple devices.
Default example includes “eth0”, “eth1”, “bond4”, “lo”. An empty list means no devices are monitored.
Description: Monitors physical link status events for specified network interfaces.
8.5 Packet Drop Monitoring
[EventTracing.Dropwatch]
    # Filter for standalone dropwatch.
    # Default: "tcp"
    Filter = "tcp"

    # Forwarded to dropwatch --max-events-per-second.
    # Default: 100; 0 disables rate limiting.
    MaxEventsPerSecond = 100

    # Reserved configuration field. It is not currently consumed by the
    # dropwatch event path and therefore has no filtering effect.
    # Default: []
    ExcludeContainers = []
-
Filter: tcpdump-style packet filter passed only to standalone dropwatch. TCP retransmission correlation uses TCPRetransmit.Filter for both of its inputs.
Default: "tcp".
-
MaxEventsPerSecond: Maximum number of dropwatch events emitted by BPF per second.
Default: 100. Set to 0 to disable rate limiting.
-
ExcludeContainers: Reserved container-exclusion list.
Default: []. The field exists in the configuration schema, but the current dropwatch event path does not read or forward it, so configuring it has no effect. Use EventTracing.IssuesList for operator-defined dropwatch call-stack suppression.
8.6 TCP Retransmission Tracing ([EventTracing.TCPRetransmit])
[EventTracing.TCPRetransmit]
    # Retransmission filter. Local correlation applies it to both inputs.
    # Default: empty (no flag when disabled; "tcp" when enabled).
    Filter = ""

    # Forwarded as tcpshark --enable-tlp. Default: false.
    EnableTLP = false

    # Run tcpshark with an embedded dropwatch source. Default: false.
    EnableDropwatch = false

    # Forwarded as tcpshark --max-events-per-second.
    # Default: 100; 0 disables rate limiting.
    MaxEventsPerSecond = 100
-
EnableTLP: Whether to collect tcp_send_loss_probe events.
Default: false.
-
Filter: Tcpdump-style retransmission filter used in both modes. Local correlation applies the normalized expression to both tcpshark inputs and defaults an empty value to tcp. When correlation is disabled, an empty value passes no --filter flag. Dropwatch.Filter independently controls standalone dropwatch.
-
EnableDropwatch: Whether tcpshark should load a private dropwatch source and finalize retransmissions locally. The default is false. tcp_retransmit must be removed from BlackList; standalone dropwatch may remain blacklisted. Retransmissions wait up to 100 ms for delayed delivery, and candidate drops must precede them by no more than one second in kernel monotonic time. The embedded source automatically detects and enables devlink DROP traps. A strict same-namespace match reports software or hardware according to source, with the same drop_source, drop_reason, and hardware drop_reason_group semantics as dropwatch; every finalized event has one correlation_reason (matched, unsupported, warmup, wait_timeout, queue_full, or interrupted). warmup applies only to expired waits whose retransmit timestamp predates source readiness; retransmissions at or after readiness receive wait_timeout on expiry, and other termination paths retain their own reasons. Unmatched events report drop_location=unknown with the namespace diagnostic and dropwatch counters, including map-counter availability.
-
MaxEventsPerSecond: Maximum TCP retransmission events emitted by BPF per second. Correlation mode gives embedded dropwatch an independent limiter with the same value, so 100 permits up to 100 events/s on each input.
Default: 100. Set to 0 for unlimited output. When the limit is exceeded, tcpshark logs rate limit hit.
8.7 Hardware Error Event Tracing (EventTracing.Ras)
# ras
#
# Hardware error event tracing (RAS: Reliability, Availability, Serviceability).
# Captures MCE, EDAC, ACPI/GHES, PCIe AER, and MCE threshold (THR) events via eBPF.
#
# - MceThrBackoff
# Minimum interval in seconds between consecutive MCE threshold (THR) event saves.
# THR events are fired by the local-APIC threshold interrupt and can storm at high
# frequency; this cooldown prevents flooding storage with redundant records.
# Default: 1800s (30 minutes)
#
[EventTracing.Ras]
    # MceThrBackoff = 1800
-
MceThrBackoff: Minimum cooldown in seconds between MCE threshold (THR) event saves.
Default: 1800s (30 minutes).
Description: THR events are generated by the CPU’s local-APIC threshold interrupt when correctable hardware errors accumulate. These can fire at very high frequency during hardware degradation. The backoff suppresses redundant saves while ensuring at least one record is captured per interval. Lower values provide more granular event records at the cost of higher storage throughput; in environments with frequent correctable errors, consider raising this value to reduce noise.
8.8 Moore Threads GPU Event Tracing (EventTracing.MthreadsGPU)
# mthreads_gpu
#
# Moore Threads GPU XID error event tracing.
[EventTracing.MthreadsGPU]
    # MthreadsXidLevel = ""
-
MthreadsXidLevel: Minimum severity level for XID error reporting.
Valid values: "" (disabled), "notify", "warning", "fatal".
Default: "" (disabled).
Description: Controls which XID error events are reported. Set to enable XID error tracking for Moore Threads GPUs. XID errors below the specified severity level are filtered out. To enable this feature, ensure that mthreads_xid is removed from the global BlackList (if present) and set this field to one of the valid severity levels ("notify", "warning", "fatal"). Additionally, the MUSA driver must be installed on the host. The feature polls /proc/driver/musa/gpu*/event_report files every second to capture XID error events. Each XID event contains detailed information including UUID, XID ID, severity, scope, PCI BDF, process ID, and additional context.
8.9 Known Issue Filtering (IssuesList)
# Linux kernel event tracing configuration.
#
# - IssuesList
# Known issue filters for event tracing.
#
[EventTracing]
    IssuesList = []
-
IssuesList: Known-issue suppression rules in the form [["name", "regex"], ...]. Default [].
For net_rx_latency, each regex is matched against the generated event title. For dropwatch, it is matched against the newline-joined kernel call stack. A match causes the event to be discarded; the configured name identifies the rule but is not added to the saved event.
Example: IssuesList = [["ignored_process", "comm=ignored_process"], ["neighbor_cleanup", "neigh_invalidate/"]]
9. Metric Collector
This section defines collection rules for various system and network metrics. All Included/Excluded fields share the same filter logic (regex):
- No rules: all items are collected
- Excluded only: blacklist, matched items are skipped
- Included only: whitelist, only matched items are collected
- Both: must match Included AND not match Excluded
9.1 Netdev Statistics
# Metric Collector
[MetricCollector]
	# Netdev statistic
	#
	# - EnableNetlink
	# Use netlink instead of procfs net/dev to get netdev statistic.
	# Only support the host environment to use `netlink` now.
	# Default is "false".
	#
	# - DeviceIncluded
	# Accept special devices in netdev statistic.
	# Default: "" (empty), meaning include all.
	#
	# - DeviceExcluded
	# Exclude special devices in netdev statistic.
	# Default: "" (empty), meaning exclude nothing.
	#
	# Filter logic see MetricCollector section header.
	#
	[MetricCollector.NetdevStats]
		# EnableNetlink = false
		# DeviceIncluded = ""
		DeviceExcluded = "^(lo)|(docker\\w*)|(veth\\w*)$"
-
EnableNetlink: Use netlink instead of procfs to collect netdev statistics.
Default: false. Currently only supported on the host.
-
DeviceIncluded: Regex to include specific devices. Default: include all.
-
DeviceExcluded: Regex to exclude devices. Example: “^(lo)|(docker\w*)|(veth\w*)$”, meaning exclude loopback, docker, and veth interfaces.
9.2 Netdev DCB Collection
# netdev dcb, DCB (Data Center Bridging)
#
# Collecting the DCB PFC (Priority-based Flow Control).
#
# - DeviceList
# The net devices we monitor.
# Default: [] (empty, meaning no devices).
#
[MetricCollector.NetdevDCB]
	DeviceList = ["eth0", "eth1"]
9.3 Netdev Hardware Statistics
# netdev hardware statistic
#
# Collecting the hardware statistic of net devices, e.g, rx_dropped.
#
# - DeviceList
# The net devices we monitor.
# Default: [] (empty, meaning no devices).
#
[MetricCollector.NetdevHW]
	DeviceList = ["eth0", "eth1"]
9.4 Qdisc Collection
# Qdisc
#
# - DeviceIncluded / DeviceExcluded
# Same as above.
#
[MetricCollector.Qdisc]
	# DeviceIncluded = ""
	DeviceExcluded = "^(lo)|(docker\\w*)|(veth\\w*)$"
- DeviceIncluded / DeviceExcluded: Same as above.
9.5 vmstat Metric Collection
# vmstat
#
# This metric supports host vmstat and cgroup vmstat.
# - IncludedOnHost / ExcludedOnHost: same as above, for host /proc/vmstat.
# - IncludedOnContainer / ExcludedOnContainer: same, for cgroup containers memory.stat.
#
[MetricCollector.Vmstat]
	IncludedOnHost = "allocstall|nr_active_anon|nr_active_file|nr_boost_pages|nr_dirty|nr_free_pages|nr_inactive_anon|nr_inactive_file|nr_kswapd_boost|nr_mlock|nr_shmem|nr_slab_reclaimable|nr_slab_unreclaimable|nr_unevictable|nr_writeback|numa_pages_migrated|pgdeactivate|pgrefill|pgscan_direct|pgscan_kswapd|pgsteal_direct|pgsteal_kswapd"
	ExcludedOnHost = "total"
	IncludedOnContainer = "active_anon|active_file|dirty|inactive_anon|inactive_file|pgdeactivate|pgrefill|pgscan_direct|pgscan_kswapd|pgsteal_direct|pgsteal_kswapd|shmem|unevictable|writeback|pgscan_globaldirect|pgscan_globalkswapd|pgscan_cswapd|pgsteal_cswapd|pgsteal_globaldirect|pgsteal_globalkswapd"
	ExcludedOnContainer = "total"
9.6 Other Metric Collections
# MemoryEvents/Netstat/MountPointStat
#
# - Included / Excluded: same as above.
# - MountPointsIncluded: whitelist only (no Excluded), same logic.
#
[MetricCollector.MemoryEvents]
	Included = "watermark_inc|watermark_dec"
	# Excluded = ""
[MetricCollector.Netstat]
	# Excluded = ""
	# Included = ""

# MountPointStat
[MetricCollector.MountPointStat]
	MountPointsIncluded = "(^/home$)|(^/$)|(^/boot$)"
-
Included / Excluded: Same as above.
-
MountPointsIncluded: Regex for mount points to collect. Default includes /, /home, /boot.
9.7 Moore Threads GPU Metrics
# MetricCollector.Mthreads
#
# Moore Threads GPU metric collection via the MTML (Moore Threads Management
# Library) shared library. The library is discovered automatically at startup
# using SONAME search (libmtml.so.2, then libmtml.so) through the system
# dynamic linker; no hardcoded path is required.
#
# Remove "mthreads_gpu" from BlackList to enable this collector.
#
# - EnableHealth
# Enable health metrics: temperature, power, utilization, clocks, fans, pstate, VPU.
# Default: true
#
# - EnablePCIe
# Enable PCIe link metrics: current speed/width and replay counter.
# Default: false
#
# - EnableMTLink
# Enable MtLink interconnect metrics: per-link state and bandwidth.
# Default: false
#
[MetricCollector.Mthreads]
    # EnableHealth = true
    # EnablePCIe = false
    # EnableMTLink = false
-
EnableHealth: Controls collection of health-related metrics.
Default: true. When enabled, collects: GPU/memory temperature (gpu_temperature_celsius, memory_temperature_celsius), power usage and limits (device_power_watts, gpu_power_limit_watts, gpu_power_default_limit_watts), GPU/memory utilization (gpu_utilization_percent, memory_utilization_percent), clock frequencies (gpu_clock_mhz, gpu_max_clock_mhz, memory_clock_mhz, memory_max_clock_mhz), voltage (gpu_voltage_volts), memory capacity (memory_total_bytes, memory_used_bytes), fan speed (fan_rpm, fan_speed_percent), performance state (gpu_pstate), and VPU metrics (vpu_utilization_percent, vpu_encoder_utilization_percent, vpu_decoder_utilization_percent, vpu_clock_mhz).
-
EnablePCIe: Controls collection of PCIe link metrics.
Default: false. When enabled, collects: current PCIe link speed and width (pcie_link_speed_gt_per_sec, pcie_link_width_lanes), max capability (pcie_link_max_speed_gt_per_sec, pcie_link_max_width_lanes), and replay counter (pcie_replay_total).
-
EnableMTLink: Controls collection of MtLink interconnect metrics.
Default: false. When enabled, collects: device-level static specs (per-link bandwidth mtlink_link_bandwidth_gb_s and link count mtlink_link_count) and per-link state (mtlink_state).
Library discovery: At startup, the collector searches for libmtml.so.2 then libmtml.so via the system dynamic linker (respecting LD_LIBRARY_PATH and /etc/ld.so.cache). If no library is found, the collector logs a warning and is disabled for the lifetime of the process. Library discovery is performed only at startup: changing LD_LIBRARY_PATH or installing a new MTML version also requires a restart.
Hot-reload semantics: EnableHealth, EnablePCIe, and EnableMTLink are read from the latest config snapshot on every scrape, so toggling them takes effect on the next Prometheus scrape without restarting huatuo-bamai. A false → true → false transition emits and suppresses the corresponding metric groups on the next scrape after each change.
Note: enabling the collector itself (i.e. removing mthreads_gpu from BlackList after the process has already started with the collector disabled because libmtml.so was missing at startup) requires a restart. The collector factory runs only during initialization, so a successful late library load will not register a new collector.
10. Pod
This section configures how to fetch Pod information from kubelet to enable container/Pod-level labeling and metric isolation.
# Pod Configuration
#
# Configure these parameters for fetching pods from kubelet.
#
# - KubeletReadOnlyPort
# The KubeletReadOnlyPort is kubelet read-only port for the Kubelet to serve on with
# no authentication/authorization. The port number must be between 1 and 65535, inclusive.
# Setting this field to 0 disables fetching pods from kubelet read-only service.
# Default: 10255
#
# - KubeletAuthorizedPort
# The port is the HTTPs port of the kubelet. The port number must be between 1 and 65535,
# inclusive. Setting this field to 0 disables fetching pods from kubelet HTTPS port.
# Default: 10250
#
# - KubeletClientCertPath
# https://kubernetes.io/docs/setup/best-practices/certificates/
#
# Client certificate and private key file name. One file or two files:
# "/path/to/xxx-kubelet-client.crt,/path/to/xxx-kubelet-client.key",
# "/path/to/kubelet-client-current.pem"
#
# You can disable this kubelet fetching pods, for bare metal service, by
# KubeletReadOnlyPort = 0, and KubeletAuthorizedPort = 0.
#
[Pod]
	KubeletClientCertPath = "/etc/kubernetes/pki/apiserver-kubelet-client.crt,/etc/kubernetes/pki/apiserver-kubelet-client.key"
-
KubeletReadOnlyPort: Kubelet read-only port.
Default: 10255. Set to 0 to disable this method.
-
KubeletAuthorizedPort: Kubelet HTTPS authorized port.
Default: 10250. Set to 0 to disable.
-
KubeletClientCertPath: Path to kubelet client certificate and private key. Supports comma-separated files or single PEM file.
Description: Used for mTLS authentication on the HTTPS port. In non-Kubernetes (bare-metal) environments, set both ports to 0 to disable Pod fetching.
11. CLI Flags
huatuo-bamai supports the following command-line flags:
huatuo-bamai --region <region> [options]
| Flag |
Description |
Default |
--config |
Configuration file name |
huatuo-bamai.conf |
--config-dir |
Configuration file directory |
conf |
--bpf-dir |
BPF object file directory |
bpf |
--tools-bin-dir |
Tracing tool binary directory |
bin |
--region |
Deployment region (required) |
- |
--disable-kubelet |
Disable kubelet Pod fetching |
false |
--disable-storage |
Disable storage backends |
false |
--enable-cgroup |
Enable self cgroup resource limits (disabled by default) |
false |
--disable-tracing |
Disable specified tracing modules (may be repeated) |
- |
--log-debug |
Force log level to Debug |
false |
--dry-run |
Load-only test; exit gracefully after startup |
false |
--procfs-prefix |
procfs mount point prefix |
- |
12. Configuration Override Precedence
When the same configuration item is set in both command-line flags and the configuration file, the following precedence applies:
CLI flag > Configuration file > Built-in default
Specific rules:
-
Log level: --log-debug > config file [Log] Level > built-in default Info
--log-debug has the highest priority and forces the log level to Debug regardless of the Level value in the configuration file.- An explicit
Level in the configuration file overrides the built-in default.
- If neither is set, the default
Info is used.
-
Tracing blacklist: --disable-tracing is merged with the configuration file BlackList (they complement each other rather than override).
-
Other boolean switches (--disable-kubelet, --disable-storage): When explicitly set on the command line, they override the configuration file.
13. Best Practices and Important Notes
- Resource Control: Kubernetes uses Pod resources and systemd uses service limits.
Use
--enable-cgroup and [Runtime] only for direct execution without an
external manager.
- Storage Choice: For small-scale deployments, prefer [Storage.LocalFile] for local troubleshooting. For large clusters, configure Elasticsearch for centralized storage and querying.
- AutoTracing Tuning: Adjust thresholds based on workload characteristics. Thresholds that are too low cause frequent triggering; thresholds that are too high may miss issues. Validate gradually in a test environment.
- Security: Use strong passwords for ES configuration and consider enabling HTTPS. Avoid hard-coding sensitive information in the configuration file.
- Compatibility: Configuration parameters may be affected by kernel version and hardware environment. Always verify with the official HUATUO documentation for your specific setup.
By properly configuring huatuo-bamai.conf, you can fully leverage HUATUO’s capabilities in kernel-level anomaly detection and intelligent tracing, significantly improving observability and troubleshooting efficiency in cloud-native systems.
If you need deeper customization for a specific scenario, feel free to provide more details about your environment.
14. Memory Threshold Snapshot Deployment and Troubleshooting
14.1 Requirements and Limitations
- Requires Linux, memory cgroup v1/v2, host PID/procfs/cgroup views,
kubelet metadata, kernel BTF, and BPF load/attach permissions.
- Requires target-memory read permission (usually
CAP_SYS_PTRACE),
procfs/cgroup access, and v1 cgroup.event_control write access.
Yama, SELinux, or AppArmor may block access.
- Selects only direct cgroup members, excluding
oom_score_adj = -1000.
Selection is skipped above 4096 PIDs, 64 KiB of PID data, or a one-second budget.
- At most 4096 containers are watched. Targets come from pod events without
scanning the cgroup tree. Ordinary registration errors and capacity exhaustion
are logged and skipped; invalidated registrations are removed without retries
or backfilling. Resource recovery or a full view does not re-register the same
instance, so pressure monitoring may remain unavailable for that instance.
- Failed identity checks or missing container metadata prevent capture or saving.
- Process selection and capture both use
/proc in Huatuo’s PID namespace.
Changing --procfs-prefix does not redirect memory snapshot reads.
This table describes experimental implementation coverage, not validation of
every listed version:
| Runtime |
Experimental coverage |
Main limitations |
| Go |
Go 1.18–1.26, 64-bit ELF |
Instruction recovery for stripped executables is x86-64 only |
| Java |
Java 8+, little-endian 64-bit ELF HotSpot, G1 GC |
Requires recognizable VMStruct/VMType metadata |
| Python |
CPython 3.8–3.14, little-endian 64-bit ELF |
Requires discoverable _PyRuntime and recognizable version/layout |
Recorded manual validation: x86-64 Linux, cgroup v1 (legacy/hybrid), Go 1.24.0.
Verify pressure-triggered, non-empty snapshots in your environment;
skipped tests and unavailable results do not prove compatibility.
14.2 Output and Troubleshooting
Info logs record watcher state and capture attempts.
Process selection and persistence details use Debug logs. Locate attempts by
container/cgroup and use process-selection logs to identify the PID. Inspect
stored snapshot status and status_reason fields for runtime diagnostics.
If a capture attempt starts but does not finish, inspect bamai’s
/debug/pprof/goroutine?debug=2 with appropriate authorization for the blocked stack.
No logs alone do not prove that monitoring has stopped.
tracer_data.process_memory reads /proc/<pid>/status once after runtime detection
returns without error, including for unrecognized runtimes such as C/C++.
Provider failures produce a failed snapshot and retain this summary.
Detection or output-processing errors prevent persistence; inspect the capture
attempt logs for the error. Target identity changes or cancellation discard the result.
It provides no PSS, mapping rankings, or allocation stacks.
| Field (bytes) |
Source / meaning |
virtual_bytes |
VmSize, virtual address space, not physical memory usage |
rss_bytes |
VmRSS, resident memory |
rss_anon_bytes |
RssAnon, anonymous resident memory |
rss_file_bytes |
RssFile, file-backed resident memory |
rss_shmem_bytes |
RssShmem, shared resident memory |
swap_bytes |
VmSwap, swapped private anonymous memory, excluding shmem swap |
page_table_bytes |
VmPTE, page-table memory |
Missing/invalid fields are omitted, not zero-filled: status is partial,
or unavailable with status_reason if nothing can be read.
Values are approximate, not an OOM-time snapshot or proof of a leak.
The selected process may not be the eventual OOM victim.
Results use the existing [Storage] configuration (section 6); no separate
storage setup is needed. The LocalFile filename is memory_threshold_snapshot.
Query tracing_documents with tracer_name = memory_threshold_snapshot and
tracer_type = autotracing.
started_timestamp records when the capture attempt starts, before process selection.
observed_timestamp records when snapshot collection starts, after process selection
and before runtime detection.
The kind and measurement semantics of tracer_data.snapshot.entries are:
| Runtime |
kind |
objects |
bytes |
| Go |
inuse_space_objects |
Estimated unfreed object count from published statistics, corrected for sampling and grouped by complete allocation stack |
Estimated unfreed bytes for those objects |
| Java |
object_class |
Estimated instance count grouped by class |
Estimated memory occupied by the objects themselves (shallow heap) |
| Python |
gc_tracked_object_type |
GC-tracked object count grouped by type |
Estimated shallow size of those objects |
Go’s bytes and objects correspond to pprof’s inuse_space and inuse_objects
metrics. Java does not compute retained heap; Python covers only GC-tracked
objects, not the entire Python heap. Older records may use allocation_site
for Go and object_type for Java; consumers reading historical records should
accept those values.
For Go entries, name remains the plain function name of the first non-runtime
frame, or the first frame when all frames belong to the runtime. stack remains
a string array ordered from the allocation site toward its callers. When both
file and line are available, each frame uses function, source_file:line, with
one space after the comma. For example:
{
  "kind": "inuse_space_objects",
  "name": "example/cache.allocate",
  "bytes": 131072,
  "objects": 32,
  "average_bytes": 4096,
  "stack": [
    "example/cache.allocate, example/cache/cache.go:123",
    "example/service.load, example/service/load.go:58",
    "main.main, example/cmd/server/main.go:42"
  ]
}
Locations come from the binary’s Go line table; source files need not exist on
the target machine. Paths retain their compiled values, which may reflect
-trimpath and may not identify files on the target machine. A missing file or
an invalid line leaves only the function name; an unresolved function leaves the
hexadecimal PC. Consumers should also accept historical frames containing only
names or addresses. Function names and paths may themselves contain commas, so
splitting indiscriminately on commas is not reliable. Source locations identify
allocation sites, not object owners, and do not guarantee a fully expanded
inline call chain.
Go subtracts frees from allocations using only the runtime’s published active
counters, then corrects for sampling. Unpublished future[0..2] counters are
excluded. Publication is delayed until the corresponding GC sweep frees are
accounted for, so recent allocation spikes may be absent. Results are external
samples of the published heap profile, not heap usage at the trigger instant.
Collection does not acquire runtime locks, flush counters, or trigger GC in the
target. Fields or buckets may still reflect different publication stages, so
the result does not provide pprof’s atomic consistency.
If a complete scan observes no nonzero active counters, it returns unavailable
with status_reason set to Go heap profile has no published statistics, without
falling back to future. This can occur before the first GC and does not mean
that the process has no heap objects. Published counters whose sampled objects
have all been freed can still produce complete with empty entries. An
interrupted scan preserves partial and its reason rather than treating
unobserved data as unpublished.
Go aggregates complete stack keys up to 32 frames for Go 1.18–1.22 and 1024 frames for Go 1.23–1.26; the shared output limit may shorten displayed stacks to 64 frames and sets output_truncated. An invalid bucket type, an excessive stack depth, or a cyclic bucket chain stops the scan with partial; repeated buckets are never counted twice.
Once a scan becomes partial, it stops traversing further buckets and selects at most MaxMemoryObjectEntries entries by descending byte count from the valid samples retained from earlier batches and the current batch, within the aggregation budget. The status_reason records only the first cause; finishing the current batch does not append further causes.
Any bucket header, record, or stack read failure, including a short read, fails the entire Go collection attempt and discards all runtime entries, including those from earlier batches. The collector reports failed with the read error; individual ranges are not retried.
Samples with a stack depth of zero produce no allocation-site entry; an empty stack alone does not make the scan partial.
Go snapshots require a known, enabled sampling rate and a nonempty bucket list. An unknown or disabled rate, or an empty bucket list, yields unavailable with a status_reason and no entries.
Go collection uses a single request timeout across runtime reads, scanning,
ranking, and entry construction. When it expires, runtime entries are discarded
and the collector emits failed with a timeout reason; it still attempts to
read the process memory summary. Cancellation is cooperative, so an in-flight
system call or non-cancelable parsing step can finish after the deadline.
Inspect tracer_data.snapshot.status (complete, partial,
unavailable, or failed) together with status_reason, runtime_version,
duration_ms, and output_truncated.
status_reason explains why collection is partial, unavailable, or failed;
it is omitted when empty. Both snapshot and process_memory use this field.
Older records may use reason; readers of historical and new records should
accept both names.
duration_ms measures the provider stage, rounded up to milliseconds, for both
successful and failed snapshots, including timeouts. It excludes runtime
detection, process memory summary reads, output processing, and persistence.
| Problem |
Checks |
| No output |
Enable and restart; check BlackList; see section 7.6 for v2 trigger conditions |
| Event without a candidate |
Check direct cgroup membership, OOM-kill eligibility, and enumeration limits |
unavailable / failed |
Check runtime/layout restrictions, access permissions, container metadata, and target exit; inspect status_reason |
| Event stops after resource exhaustion |
Check RLIMIT_NOFILE, fs.inotify.max_user_watches, and fs.inotify.max_user_instances; adjust and restart; this stop does not stop other events |
4.2 - huatuo-apiserver Configuration
1. Overview
huatuo-apiserver uses a strictly decoded TOML configuration file. Unknown
or obsolete options prevent startup. Commented options use the built-in
defaults shown below.
2. Logging and Runtime Limits
huatuo-apiserver does not create its own cgroup by default. The [Runtime] section
applies only when --enable-cgroup is explicitly passed; Kubernetes and systemd
deployments should use their native resource controls.
# Log Configuration
[Log]
    # - Level
    # The log level for huatuo-apiserver: Debug, Info, Warn, Error, Panic.
    # Default: Info
    #
    # Level = "Info"

# Runtime limits for the huatuo-apiserver process.
[Runtime]
    # - CPULimitCores
    # CPU limit in cores.
    # Default: 20
    #
    # - MemoryLimitMiB
    # Memory limit in MiB.
    # Default: 4096
    #
    # CPULimitCores = 20
    # MemoryLimitMiB = 4096
Log.Level supports Debug, Info, Warn, Error, and Panic.CPULimitCores limits the API server process in CPU cores.MemoryLimitMiB limits the API server process in MiB.
All resource limits must be greater than zero. --log-debug overrides
Log.Level.
3. HTTP Server
# HTTP server configuration.
[APIServer]
    # - ListenAddress
    # Listen address in "host:port" form.
    # Default: ":12740"
    #
    # ListenAddress = ":12740"

    # Request rate limiting.
    [APIServer.RateLimit]
        # - RequestsPerSecond
        # Maximum process-wide request rate per second.
        # Default: 200
        #
        # - Burst
        # Maximum process-wide request burst.
        # Default: 200
        #
        # RequestsPerSecond = 200
        # Burst = 200
ListenAddress uses host:port form. An empty host listens on all
interfaces. RateLimit is a process-wide token bucket; both values must be
positive. HTTP timeouts and request-size limits are fixed service safeguards
and are not user configurable.
4. Jobs and Agent Communication
# Job persistence.
[Jobs]
    # - StoreDSN
    # SQLite DSN. Relative paths are resolved from this file's directory.
    # Default: "jobs.db"
    #
    # StoreDSN = "jobs.db"

    # Job records use an internal revision for concurrent updates. Only records
    # written by this server version are supported; stop the old service and
    # remove or replace an incompatible database before starting this version.

    # Profiling and tracing retain independent quotas because their resource
    # costs and expected concurrency differ.
    [Jobs.Profiling]
        # - MaxConcurrentPerHost
        # Maximum concurrent profiling jobs on one host.
        # Default: 3
        #
        # - MaxConcurrent
        # Maximum concurrent profiling jobs across all hosts.
        # Default: 500
        #
        # MaxConcurrentPerHost = 3
        # MaxConcurrent = 500

    [Jobs.Tracing]
        # - MaxConcurrentPerHost
        # Maximum concurrent tracing jobs on one host.
        # Default: 5
        #
        # - MaxConcurrent
        # Maximum concurrent tracing jobs across all hosts.
        # Default: 1000
        #
        # MaxConcurrentPerHost = 5
        # MaxConcurrent = 1000

    # Apiserver-owned Job lifecycle policy.
    [Jobs.Controller]
        # StatusPollIntervalSeconds = 5
        # PendingTimeoutSeconds = 30
        # CompletionGracePeriodSeconds = 60
        # NodeUnavailableGracePeriodSeconds = 30
        # JobRetentionPeriodHours = 720

# huatuo-bamai Agent HTTP client configuration.
[Agent]
    # - HTTPPort
    # Agent HTTP server port.
    # Default: 19704
    #
    # HTTPPort = 19704

    [Agent.Auth]
        # Must match HTTPServer.Auth.BearerToken on every Node.
        BearerToken = "REPLACE_WITH_RANDOM_HEX"
StoreDSN is the SQLite data source for durable job state. Relative paths are
resolved from the configuration directory.
Profiling and tracing use the same quota model but retain independent values.
Their resource cost and expected concurrency differ, so a shared limit would
allow one workload to starve the other.
Agent request transport safeguards use internal client defaults. Job polling,
deadlines, unavailable grace, and retention are owned independently by
Jobs.Controller; no runtime negotiation with the Node is performed.
During shutdown, the API server leaves active Node operations running. A
replacement API server recovers active Jobs from durable state and resumes
monitoring without replaying Start.
5. Elasticsearch/OpenSearch
# Optional Elasticsearch/OpenSearch backend for querying profiling data.
[Elasticsearch]
    # Address, Username, and Password must be configured together to enable
    # this backend.
    #
    # - Address
    # Elasticsearch or OpenSearch HTTP address.
    #
    # - Username
    # Elasticsearch or OpenSearch username.
    #
    # - Password
    # Elasticsearch or OpenSearch password.
    #
    # - Index
    # Index containing huatuo-bamai profiling data.
    # Default: "huatuo_bamai"
    #
    # Address = "https://elasticsearch.example.com:9200"
    # Username = "huatuo-apiserver"
    # Password = "REPLACE_WITH_STRONG_PASSWORD"
    # Index = "huatuo_bamai"
Storage is optional. Address, Username, and Password must either all be
empty or all be configured. Index defaults to huatuo_bamai and must match
the collector storage index. When disabled, raw-profile and flame graph query
routes are not registered.
6. Authentication and Authorization
# Authentication configuration.
[Auth]
    # - ID
    # Stable principal identifier stored with jobs.
    #
    # - BearerToken
    # Secret used only to authenticate requests. IDs and tokens must be unique.
    #
    # - Admin
    # Whether the principal has unrestricted API access.
    #
    # - Permissions
    # API method and path patterns granted to a restricted principal.
    #
    # Administrator example:
    # [[Auth.Users]]
    #     ID = "administrator"
    #     BearerToken = "REPLACE_WITH_RANDOM_HEX"
    #     Admin = true
    #
    # Restricted example:
    # [[Auth.Users]]
    #     ID = "huatuo-front"
    #     BearerToken = "REPLACE_WITH_ANOTHER_RANDOM_HEX"
    #     Permissions = [
    #         "GET /v1/tracing",
    #         "GET /v1/tracing/**",
    #         "GET /v1/profiling",
    #         "GET /v1/profiling/**",
    #     ]
ID is the required stable principal identifier stored with jobs.BearerToken is a required secret used only to authenticate requests.Admin grants access to all routes and ignores Permissions.Permissions is required for non-admin users. Entries may be path-only or
prefixed with an HTTP method. * matches one path segment and ** matches a
suffix.
IDs and bearer tokens must each be unique. Rotating a bearer token does not
change job ownership because tokens are never used as principal IDs.
/readyz, /metrics, and /version are public.
/debug/pprof/** and /v1/profiling/flamegraph/** require an administrator.
7. Profiling
# Profiling result-link configuration.
[Profiling]
    # - DashboardBaseURL
    # Optional dashboard base URL. Result URLs are omitted when empty.
    # Default: empty
    #
    # DashboardBaseURL = "https://grafana.example.com/d"
DashboardBaseURL is optional and must use HTTP or HTTPS when configured.
Result-capable jobs omit a dashboard URL when it is empty.
Profiler execution and aggregation settings are Node-local configuration.
5 - Key Feature
5.1 - Kernel-Wide Insight
Metrics supported in the current version:
CPU
Scheduling
The following metrics allow observation of process scheduling latency, i.e., the time from when a process becomes runnable (placed in the run queue) until it actually starts executing on the CPU.
# HELP huatuo_bamai_runqlat_container_latency cpu run queue latency for the containers
# TYPE huatuo_bamai_runqlat_container_latency gauge
huatuo_bamai_runqlat_container_latency{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev",zone="0"} 226
huatuo_bamai_runqlat_container_latency{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev",zone="1"} 0
huatuo_bamai_runqlat_container_latency{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev",zone="2"} 0
huatuo_bamai_runqlat_container_latency{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev",zone="3"} 0

# HELP huatuo_bamai_runqlat_latency cpu run queue latency for the host
# TYPE huatuo_bamai_runqlat_latency gauge
huatuo_bamai_runqlat_latency{host="hostname",region="dev",zone="0"} 35100
huatuo_bamai_runqlat_latency{host="hostname",region="dev",zone="1"} 0
huatuo_bamai_runqlat_latency{host="hostname",region="dev",zone="2"} 0
huatuo_bamai_runqlat_latency{host="hostname",region="dev",zone="3"} 0
| Metric |
Description |
Unit |
Target |
Source |
Labels |
| runqlat_container_latency |
scheduling latency histogram buckets:
zone0: 0–10 ms
zone1: 10–20 ms
zone2: 20–50 ms
zone3: 50+ ms |
count |
Container |
eBPF |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region, zone |
| runqlat_latency |
scheduling latency histogram buckets:
zone0, 0~10ms
zone1, 10-20ms
zone2, 20-50ms
zone3, 50+ms |
count |
Host |
eBPF |
host, region, zone |
SoftIRQ
SoftIRQ response latency on different CPUs (currently only NET_RX and NET_TX are collected).
# HELP huatuo_bamai_softirq_latency softirq latency
# TYPE huatuo_bamai_softirq_latency gauge
huatuo_bamai_softirq_latency{cpuid="0",host="hostname",region="dev",type="NET_RX",zone="0"} 125
huatuo_bamai_softirq_latency{cpuid="0",host="hostname",region="dev",type="NET_RX",zone="1"} 2
huatuo_bamai_softirq_latency{cpuid="0",host="hostname",region="dev",type="NET_RX",zone="2"} 0
huatuo_bamai_softirq_latency{cpuid="0",host="hostname",region="dev",type="NET_RX",zone="3"} 0
huatuo_bamai_softirq_latency{cpuid="0",host="hostname",region="dev",type="NET_TX",zone="0"} 0
huatuo_bamai_softirq_latency{cpuid="0",host="hostname",region="dev",type="NET_TX",zone="1"} 0
huatuo_bamai_softirq_latency{cpuid="0",host="hostname",region="dev",type="NET_TX",zone="2"} 0
huatuo_bamai_softirq_latency{cpuid="0",host="hostname",region="dev",type="NET_TX",zone="3"} 0
huatuo_bamai_softirq_latency{cpuid="1",host="hostname",region="dev",type="NET_RX",zone="0"} 110
huatuo_bamai_softirq_latency{cpuid="1",host="hostname",region="dev",type="NET_RX",zone="1"} 0
huatuo_bamai_softirq_latency{cpuid="1",host="hostname",region="dev",type="NET_RX",zone="2"} 1
huatuo_bamai_softirq_latency{cpuid="1",host="hostname",region="dev",type="NET_RX",zone="3"} 0
huatuo_bamai_softirq_latency{cpuid="1",host="hostname",region="dev",type="NET_TX",zone="0"} 0
huatuo_bamai_softirq_latency{cpuid="1",host="hostname",region="dev",type="NET_TX",zone="1"} 0
huatuo_bamai_softirq_latency{cpuid="1",host="hostname",region="dev",type="NET_TX",zone="2"} 0
| Metric |
Description |
Unit |
Target |
Source |
Labels |
| softirq_latency |
SoftIRQ response latency histogram buckets:
zone0, 0-10us
zone1, 10-100us
zone2, 100-1000us
zone3, 1+ms |
count |
Host |
eBPF |
cpuid, host, region, type, zone |
Utilization
Metrics showing CPU usage on hosts and containers (Prometheus format):
# HELP huatuo_bamai_cpu_util_sys cpu sys for the host
# TYPE huatuo_bamai_cpu_util_sys gauge
huatuo_bamai_cpu_util_sys{host="hostname",region="dev"} 6.268857848549965e-06
# HELP huatuo_bamai_cpu_util_total cpu total for the host
# TYPE huatuo_bamai_cpu_util_total gauge
huatuo_bamai_cpu_util_total{host="hostname",region="dev"} 1.7736934944144352e-05
# HELP huatuo_bamai_cpu_util_usr cpu usr for the host
# TYPE huatuo_bamai_cpu_util_usr gauge
huatuo_bamai_cpu_util_usr{host="hostname",region="dev"} 1.1468077095594387e-05

# HELP huatuo_bamai_cpu_util_container_sys cpu sys for the containers
# TYPE huatuo_bamai_cpu_util_container_sys gauge
huatuo_bamai_cpu_util_container_sys{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 1.6708593420881415e-07
# HELP huatuo_bamai_cpu_util_container_total cpu total for the containers
# TYPE huatuo_bamai_cpu_util_container_total gauge
huatuo_bamai_cpu_util_container_total{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 3.379584661890774e-07
# HELP huatuo_bamai_cpu_util_container_usr cpu usr for the containers
# TYPE huatuo_bamai_cpu_util_container_usr gauge
huatuo_bamai_cpu_util_container_usr{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 1.7087253017325962e-07
| Metric |
Description |
Unit |
Target |
Labels |
| cpu_util_sys |
CPU system (kernel) time % |
% |
Host |
host, region |
| cpu_util_usr |
CPU user time % |
% |
Host |
host, region |
| cpu_util_total |
CPU total utilization % |
% |
Host |
host, region |
| cpu_util_container_sys |
Container CPU system time % |
% |
Container |
container_host,container_hostnamespace,container_level,container_name,container_type,host,region |
| cpu_util_container_usr |
Container CPU user time % |
% |
Container |
container_host,container_hostnamespace,container_level,container_name,container_type,host,region |
| cpu_util_container_total |
Container CPU total % |
% |
Container |
container_host,container_hostnamespace,container_level,container_name,container_type,host,region |
Allocation
Container CPU resource configuration:
# HELP huatuo_bamai_cpu_util_container_cores cpu core number for the containers
# TYPE huatuo_bamai_cpu_util_container_cores gauge
huatuo_bamai_cpu_util_container_cores{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="Burstable",container_name="coredns",container_type="Normal",host="hostname",region="dev"} 6
| Metric |
Description |
Unit |
Target |
Labels |
| cpu_util_container_cores |
Number of CPU cores |
cores |
Container |
(same as above) |
Contention
Metrics reflecting container throttling and contention:
# HELP huatuo_bamai_cpu_stat_container_nr_throttled throttle nr for the containers
# TYPE huatuo_bamai_cpu_stat_container_nr_throttled gauge
huatuo_bamai_cpu_stat_container_nr_throttled{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_cpu_stat_container_throttled_time throttle time for the containers
# TYPE huatuo_bamai_cpu_stat_container_throttled_time gauge
huatuo_bamai_cpu_stat_container_throttled_time{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
| Metric |
Description |
Unit |
Target |
Labels |
| cpu_stat_container_nr_throttled |
Number of times the cgroup was throttled |
count |
Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
| cpu_stat_container_throttled_time |
Total time the cgroup was throttled |
nanoseconds |
Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
Ref:
The following metric is available when the kernel exports wait_sum:
# HELP huatuo_bamai_cpu_stat_container_wait_sum_percent percentage of CFS cgroup schedulable time spent waiting on the parent runqueue (requires kernel.sched_schedstats=1)
# TYPE huatuo_bamai_cpu_stat_container_wait_sum_percent gauge
huatuo_bamai_cpu_stat_container_wait_sum_percent{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
Burst Behavior
Metrics showing burst usage beyond quota:
# HELP huatuo_bamai_cpu_stat_container_nr_bursts burst nr for the containers
# TYPE huatuo_bamai_cpu_stat_container_nr_bursts gauge
huatuo_bamai_cpu_stat_container_nr_bursts{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
huatuo_bamai_cpu_stat_container_nr_bursts{container_host="coredns-855c4dd65d-mnpqf",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_cpu_stat_container_burst_time burst time for the containers
# TYPE huatuo_bamai_cpu_stat_container_burst_time gauge
huatuo_bamai_cpu_stat_container_burst_time{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
huatuo_bamai_cpu_stat_container_burst_time{container_host="coredns-855c4dd65d-mnpqf",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
| Metric |
Description |
Unit |
Target |
Labels |
| cpu_stat_container_burst_time |
Cumulative wall-clock time spent above quota across all periods |
nanoseconds |
Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
| cpu_stat_container_nr_bursts |
Number of periods in which usage exceeded quota |
count |
Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
Load
Load average and runnable/uninterruptible task counts:
# HELP huatuo_bamai_loadavg_load1 system load average, 1 minute
# TYPE huatuo_bamai_loadavg_load1 gauge
huatuo_bamai_loadavg_load1{host="hostname",region="dev"} 0.3
# HELP huatuo_bamai_loadavg_load15 system load average, 15 minutes
# TYPE huatuo_bamai_loadavg_load15 gauge
huatuo_bamai_loadavg_load15{host="hostname",region="dev"} 0.22
# HELP huatuo_bamai_loadavg_load5 system load average, 5 minutes
# TYPE huatuo_bamai_loadavg_load5 gauge
huatuo_bamai_loadavg_load5{host="hostname",region="dev"} 0.2
# HELP huatuo_bamai_loadavg_container_nr_running nr_running of container
# TYPE huatuo_bamai_loadavg_container_nr_running gauge
huatuo_bamai_loadavg_container_nr_running{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 1
# HELP huatuo_bamai_loadavg_container_nr_uninterruptible nr_uninterruptible of container
# TYPE huatuo_bamai_loadavg_container_nr_uninterruptible gauge
huatuo_bamai_loadavg_container_nr_uninterruptible{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
| Metric |
Description |
Unit |
Target |
Labels |
|
| loadavg_load1 |
1-minute system load average |
count |
Host |
host, region |
|
| loadavg_load5 |
5-minute system load average |
count |
Host |
host, region |
|
| loadavg_load15 |
15-minute system load average |
count |
Host |
host, region |
|
| loadavg_container_container_nr_running |
Number of running tasks in container |
count |
Container |
host, region |
cgroup v1 only |
| loadavg_container_container_nr_uninterruptible |
Number of uninterruptible tasks in container |
count |
Container |
host, region |
cgroup v1 only |
Memory System
Reclaim
Metrics showing time spent stalled due to memory reclaim/compaction:
# HELP huatuo_bamai_memory_free_allocpages_stall time stalled in alloc pages
# TYPE huatuo_bamai_memory_free_allocpages_stall gauge
huatuo_bamai_memory_free_allocpages_stall{host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_free_compaction_stall time stalled in memory compaction
# TYPE huatuo_bamai_memory_free_compaction_stall gauge
huatuo_bamai_memory_free_compaction_stall{host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_reclaim_container_directstall counter of cgroup reclaim when try_charge
# TYPE huatuo_bamai_memory_reclaim_container_directstall gauge
huatuo_bamai_memory_reclaim_container_directstall{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
| Metric |
Description |
Unit |
Target |
Source |
Labels |
| memory_free_allocpages_stall |
Time stalled waiting for page allocation |
nanoseconds |
Host |
eBPF |
host, region |
| memory_free_compaction_stall |
Time stalled in memory compaction |
nanoseconds |
Host |
eBPF |
host, region |
| memory_reclaim_container_directstall |
Number of direct reclaim events in container |
count |
Container |
eBPF |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
Note: The memory_others_container_directstall_time, memory_others_container_asyncreclaim_time, and memory_others_container_local_direct_reclaim_time metrics read memory cgroup extension interfaces provided by the Didi Cloud custom kernel (memory.directstall_stat, memory.asynreclaim_stat, memory.local_direct_reclaim_time). Mainline and common distribution kernels do not expose these interfaces, so these metrics are simply not emitted there — this is expected, and no extra kernel module can provide them. To observe container direct reclaim behavior on standard kernels, use the eBPF-based memory_reclaim_container_directstall listed above.
State
From cgroup memory.stat:
# HELP huatuo_bamai_memory_vmstat_container_active_anon cgroup memory.stat active_anon
# TYPE huatuo_bamai_memory_vmstat_container_active_anon gauge
huatuo_bamai_memory_vmstat_container_active_anon{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 1.47456e+07
# HELP huatuo_bamai_memory_vmstat_container_active_file cgroup memory.stat active_file
# TYPE huatuo_bamai_memory_vmstat_container_active_file gauge
huatuo_bamai_memory_vmstat_container_active_file{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 2.3617536e+07
# HELP huatuo_bamai_memory_vmstat_container_file_dirty cgroup memory.stat file_dirty
# TYPE huatuo_bamai_memory_vmstat_container_file_dirty gauge
huatuo_bamai_memory_vmstat_container_file_dirty{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_vmstat_container_file_writeback cgroup memory.stat file_writeback
# TYPE huatuo_bamai_memory_vmstat_container_file_writeback gauge
huatuo_bamai_memory_vmstat_container_file_writeback{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_vmstat_container_inactive_anon cgroup memory.stat inactive_anon
# TYPE huatuo_bamai_memory_vmstat_container_inactive_anon gauge
huatuo_bamai_memory_vmstat_container_inactive_anon{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_vmstat_container_inactive_file cgroup memory.stat inactive_file
# TYPE huatuo_bamai_memory_vmstat_container_inactive_file gauge
huatuo_bamai_memory_vmstat_container_inactive_file{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 65536
# HELP huatuo_bamai_memory_vmstat_container_pgdeactivate cgroup memory.stat pgdeactivate
# TYPE huatuo_bamai_memory_vmstat_container_pgdeactivate gauge
huatuo_bamai_memory_vmstat_container_pgdeactivate{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_vmstat_container_pgrefill cgroup memory.stat pgrefill
# TYPE huatuo_bamai_memory_vmstat_container_pgrefill gauge
huatuo_bamai_memory_vmstat_container_pgrefill{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_vmstat_container_pgscan_direct cgroup memory.stat pgscan_direct
# TYPE huatuo_bamai_memory_vmstat_container_pgscan_direct gauge
huatuo_bamai_memory_vmstat_container_pgscan_direct{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_vmstat_container_pgscan_kswapd cgroup memory.stat pgscan_kswapd
# TYPE huatuo_bamai_memory_vmstat_container_pgscan_kswapd gauge
huatuo_bamai_memory_vmstat_container_pgscan_kswapd{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_vmstat_container_pgsteal_direct cgroup memory.stat pgsteal_direct
# TYPE huatuo_bamai_memory_vmstat_container_pgsteal_direct gauge
huatuo_bamai_memory_vmstat_container_pgsteal_direct{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_vmstat_container_pgsteal_kswapd cgroup memory.stat pgsteal_kswapd
# TYPE huatuo_bamai_memory_vmstat_container_pgsteal_kswapd gauge
huatuo_bamai_memory_vmstat_container_pgsteal_kswapd{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_vmstat_container_shmem cgroup memory.stat shmem
# TYPE huatuo_bamai_memory_vmstat_container_shmem gauge
huatuo_bamai_memory_vmstat_container_shmem{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_vmstat_container_shmem_thp cgroup memory.stat shmem_thp
# TYPE huatuo_bamai_memory_vmstat_container_shmem_thp gauge
huatuo_bamai_memory_vmstat_container_shmem_thp{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_vmstat_container_unevictable cgroup memory.stat unevictable
# TYPE huatuo_bamai_memory_vmstat_container_unevictable gauge
huatuo_bamai_memory_vmstat_container_unevictable{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
| Metric |
Description |
Unit |
Target |
Labels |
| memory_vmstat_container_active_file |
Active file-backed memory |
Bytes |
Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
| memory_vmstat_container_active_anon |
Active anonymous memory |
Bytes |
Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
| memory_vmstat_container_inactive_file |
Inactive file-backed memory |
Bytes |
Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
| memory_vmstat_container_inactive_anon |
Inactive anonymous memory |
Bytes |
Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
| memory_vmstat_container_file_dirty |
Dirty file pages not yet written back |
Bytes |
Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
| memory_vmstat_container_file_writeback |
File pages currently being written back |
Bytes |
Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
| memory_vmstat_container_unevictable |
Unevictable pages (mlocked, hugetlbfs, etc.) |
Bytes |
Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
| … (pgscan_direct, pgsteal_kswapd, etc.) |
Standard vmstat reclaim / scanning counters |
Bytes |
Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
Host memory state.
# HELP huatuo_bamai_memory_vmstat_allocstall_device /proc/vmstat allocstall_device
# TYPE huatuo_bamai_memory_vmstat_allocstall_device gauge
huatuo_bamai_memory_vmstat_allocstall_device{host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_vmstat_allocstall_dma /proc/vmstat allocstall_dma
# TYPE huatuo_bamai_memory_vmstat_allocstall_dma gauge
huatuo_bamai_memory_vmstat_allocstall_dma{host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_vmstat_allocstall_dma32 /proc/vmstat allocstall_dma32
# TYPE huatuo_bamai_memory_vmstat_allocstall_dma32 gauge
huatuo_bamai_memory_vmstat_allocstall_dma32{host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_vmstat_allocstall_movable /proc/vmstat allocstall_movable
# TYPE huatuo_bamai_memory_vmstat_allocstall_movable gauge
huatuo_bamai_memory_vmstat_allocstall_movable{host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_vmstat_allocstall_normal /proc/vmstat allocstall_normal
# TYPE huatuo_bamai_memory_vmstat_allocstall_normal gauge
huatuo_bamai_memory_vmstat_allocstall_normal{host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_vmstat_nr_active_anon /proc/vmstat nr_active_anon
# TYPE huatuo_bamai_memory_vmstat_nr_active_anon gauge
huatuo_bamai_memory_vmstat_nr_active_anon{host="hostname",region="dev"} 155449
# HELP huatuo_bamai_memory_vmstat_nr_active_file /proc/vmstat nr_active_file
# TYPE huatuo_bamai_memory_vmstat_nr_active_file gauge
huatuo_bamai_memory_vmstat_nr_active_file{host="hostname",region="dev"} 212425
# HELP huatuo_bamai_memory_vmstat_nr_dirty /proc/vmstat nr_dirty
# TYPE huatuo_bamai_memory_vmstat_nr_dirty gauge
huatuo_bamai_memory_vmstat_nr_dirty{host="hostname",region="dev"} 19047
# HELP huatuo_bamai_memory_vmstat_nr_dirty_background_threshold /proc/vmstat nr_dirty_background_threshold
# TYPE huatuo_bamai_memory_vmstat_nr_dirty_background_threshold gauge
huatuo_bamai_memory_vmstat_nr_dirty_background_threshold{host="hostname",region="dev"} 379858
# HELP huatuo_bamai_memory_vmstat_nr_dirty_threshold /proc/vmstat nr_dirty_threshold
# TYPE huatuo_bamai_memory_vmstat_nr_dirty_threshold gauge
huatuo_bamai_memory_vmstat_nr_dirty_threshold{host="hostname",region="dev"} 760646
# HELP huatuo_bamai_memory_vmstat_nr_free_pages /proc/vmstat nr_free_pages
# TYPE huatuo_bamai_memory_vmstat_nr_free_pages gauge
huatuo_bamai_memory_vmstat_nr_free_pages{host="hostname",region="dev"} 3.20535e+06
# HELP huatuo_bamai_memory_vmstat_nr_inactive_anon /proc/vmstat nr_inactive_anon
# TYPE huatuo_bamai_memory_vmstat_nr_inactive_anon gauge
huatuo_bamai_memory_vmstat_nr_inactive_anon{host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_vmstat_nr_inactive_file /proc/vmstat nr_inactive_file
# TYPE huatuo_bamai_memory_vmstat_nr_inactive_file gauge
huatuo_bamai_memory_vmstat_nr_inactive_file{host="hostname",region="dev"} 428518
# HELP huatuo_bamai_memory_vmstat_nr_mlock /proc/vmstat nr_mlock
# TYPE huatuo_bamai_memory_vmstat_nr_mlock gauge
huatuo_bamai_memory_vmstat_nr_mlock{host="hostname",region="dev"} 6821
# HELP huatuo_bamai_memory_vmstat_nr_shmem /proc/vmstat nr_shmem
# TYPE huatuo_bamai_memory_vmstat_nr_shmem gauge
huatuo_bamai_memory_vmstat_nr_shmem{host="hostname",region="dev"} 541
# HELP huatuo_bamai_memory_vmstat_nr_shmem_hugepages /proc/vmstat nr_shmem_hugepages
# TYPE huatuo_bamai_memory_vmstat_nr_shmem_hugepages gauge
huatuo_bamai_memory_vmstat_nr_shmem_hugepages{host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_vmstat_nr_shmem_pmdmapped /proc/vmstat nr_shmem_pmdmapped
# TYPE huatuo_bamai_memory_vmstat_nr_shmem_pmdmapped gauge
huatuo_bamai_memory_vmstat_nr_shmem_pmdmapped{host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_vmstat_nr_slab_reclaimable /proc/vmstat nr_slab_reclaimable
# TYPE huatuo_bamai_memory_vmstat_nr_slab_reclaimable gauge
huatuo_bamai_memory_vmstat_nr_slab_reclaimable{host="hostname",region="dev"} 22322
# HELP huatuo_bamai_memory_vmstat_nr_slab_unreclaimable /proc/vmstat nr_slab_unreclaimable
# TYPE huatuo_bamai_memory_vmstat_nr_slab_unreclaimable gauge
huatuo_bamai_memory_vmstat_nr_slab_unreclaimable{host="hostname",region="dev"} 24168
# HELP huatuo_bamai_memory_vmstat_nr_unevictable /proc/vmstat nr_unevictable
# TYPE huatuo_bamai_memory_vmstat_nr_unevictable gauge
huatuo_bamai_memory_vmstat_nr_unevictable{host="hostname",region="dev"} 6839
# HELP huatuo_bamai_memory_vmstat_nr_writeback /proc/vmstat nr_writeback
# TYPE huatuo_bamai_memory_vmstat_nr_writeback gauge
huatuo_bamai_memory_vmstat_nr_writeback{host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_vmstat_nr_writeback_temp /proc/vmstat nr_writeback_temp
# TYPE huatuo_bamai_memory_vmstat_nr_writeback_temp gauge
huatuo_bamai_memory_vmstat_nr_writeback_temp{host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_vmstat_numa_pages_migrated /proc/vmstat numa_pages_migrated
# TYPE huatuo_bamai_memory_vmstat_numa_pages_migrated gauge
huatuo_bamai_memory_vmstat_numa_pages_migrated{host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_vmstat_pgdeactivate /proc/vmstat pgdeactivate
# TYPE huatuo_bamai_memory_vmstat_pgdeactivate gauge
huatuo_bamai_memory_vmstat_pgdeactivate{host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_vmstat_pgrefill /proc/vmstat pgrefill
# TYPE huatuo_bamai_memory_vmstat_pgrefill gauge
huatuo_bamai_memory_vmstat_pgrefill{host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_vmstat_pgscan_direct /proc/vmstat pgscan_direct
# TYPE huatuo_bamai_memory_vmstat_pgscan_direct gauge
huatuo_bamai_memory_vmstat_pgscan_direct{host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_vmstat_pgscan_direct_throttle /proc/vmstat pgscan_direct_throttle
# TYPE huatuo_bamai_memory_vmstat_pgscan_direct_throttle gauge
huatuo_bamai_memory_vmstat_pgscan_direct_throttle{host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_vmstat_pgscan_kswapd /proc/vmstat pgscan_kswapd
# TYPE huatuo_bamai_memory_vmstat_pgscan_kswapd gauge
huatuo_bamai_memory_vmstat_pgscan_kswapd{host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_vmstat_pgsteal_direct /proc/vmstat pgsteal_direct
# TYPE huatuo_bamai_memory_vmstat_pgsteal_direct gauge
huatuo_bamai_memory_vmstat_pgsteal_direct{host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_vmstat_pgsteal_kswapd /proc/vmstat pgsteal_kswapd
# TYPE huatuo_bamai_memory_vmstat_pgsteal_kswapd gauge
huatuo_bamai_memory_vmstat_pgsteal_kswapd{host="hostname",region="dev"} 0
Standard kernel vmstat counters (see kernel documentation for full details):
- nr_free_pages: total free pages in buddy allocator
- nr_active_anon / nr_inactive_anon: active / inactive anonymous pages
- nr_active_file / nr_inactive_file: active / inactive file pages
- nr_dirty / nr_writeback: dirty / under writeback pages
- nr_dirty_threshold / nr_dirty_background_threshold: dirty page writeback thresholds
- pgscan_kswapd / pgsteal_kswapd / … : reclaim & scanning statistics
- allocstall_*: stalls due to allocation failure in different zones
- numa_hit / numa_miss / numa_foreign / numa_local / numa_other: NUMA allocation statistics
Ref:
Events
From memory.events:
# HELP huatuo_bamai_memory_events_container_high memory events high
# TYPE huatuo_bamai_memory_events_container_high gauge
huatuo_bamai_memory_events_container_high{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_events_container_low memory events low
# TYPE huatuo_bamai_memory_events_container_low gauge
huatuo_bamai_memory_events_container_low{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_events_container_max memory events max
# TYPE huatuo_bamai_memory_events_container_max gauge
huatuo_bamai_memory_events_container_max{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_events_container_oom memory events oom
# TYPE huatuo_bamai_memory_events_container_oom gauge
huatuo_bamai_memory_events_container_oom{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_events_container_oom_group_kill memory events oom_group_kill
# TYPE huatuo_bamai_memory_events_container_oom_group_kill gauge
huatuo_bamai_memory_events_container_oom_group_kill{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_memory_events_container_oom_kill memory events oom_kill
# TYPE huatuo_bamai_memory_events_container_oom_kill gauge
huatuo_bamai_memory_events_container_oom_kill{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
| Metric |
Description |
Unit |
Target |
Labels |
| memory_events_container_low |
Pages reclaimed below memory.low due to system pressure |
count |
Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
| memory_events_container_high |
Times usage exceeded memory.high (throttling / direct reclaim triggered) |
count |
Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
| memory_events_container_max |
Times approaching or hitting memory.max |
count |
Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
| memory_events_container_oom |
Times OOM path entered due to memory.max |
count |
Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
| memory_events_container_oom_kill |
Number of processes killed by OOM killer in cgroup |
count |
Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
| memory_events_container_oom_group_kill |
Number of times entire cgroup killed by OOM |
count |
Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
Buddyinfo
Free page block distribution per node/zone/order (from /proc/buddyinfo):
# HELP huatuo_bamai_memory_buddyinfo_blocks buddy info
# TYPE huatuo_bamai_memory_buddyinfo_blocks gauge
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="0",region="dev",zone="DMA"} 0
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="0",region="dev",zone="DMA32"} 3
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="0",region="dev",zone="Normal"} 7
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="1",region="dev",zone="DMA"} 0
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="1",region="dev",zone="DMA32"} 1
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="1",region="dev",zone="Normal"} 36
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="10",region="dev",zone="DMA"} 2
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="10",region="dev",zone="DMA32"} 743
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="10",region="dev",zone="Normal"} 2265
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="2",region="dev",zone="DMA"} 0
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="2",region="dev",zone="DMA32"} 3
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="2",region="dev",zone="Normal"} 10
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="3",region="dev",zone="DMA"} 0
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="3",region="dev",zone="DMA32"} 2
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="3",region="dev",zone="Normal"} 224
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="4",region="dev",zone="DMA"} 0
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="4",region="dev",zone="DMA32"} 1
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="4",region="dev",zone="Normal"} 376
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="5",region="dev",zone="DMA"} 0
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="5",region="dev",zone="DMA32"} 1
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="5",region="dev",zone="Normal"} 165
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="6",region="dev",zone="DMA"} 0
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="6",region="dev",zone="DMA32"} 3
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="6",region="dev",zone="Normal"} 118
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="7",region="dev",zone="DMA"} 0
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="7",region="dev",zone="DMA32"} 4
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="7",region="dev",zone="Normal"} 172
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="8",region="dev",zone="DMA"} 1
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="8",region="dev",zone="DMA32"} 4
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="8",region="dev",zone="Normal"} 35
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="9",region="dev",zone="DMA"} 2
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="9",region="dev",zone="DMA32"} 4
huatuo_bamai_memory_buddyinfo_blocks{host="hostname",node="0",order="9",region="dev",zone="Normal"} 25
| Metric |
Description |
Unit |
Target |
Labels |
| memory_buddyinfo_blocks |
Shows number of free blocks of each order (2^order pages) in each zone. |
count |
Host |
procfs |
Network
ARP
# HELP huatuo_bamai_arp_container_entries arp entries in container netns
# TYPE huatuo_bamai_arp_container_entries gauge
huatuo_bamai_arp_container_entries{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 1
# HELP huatuo_bamai_arp_entries host init namespace
# TYPE huatuo_bamai_arp_entries gauge
huatuo_bamai_arp_entries{host="hostname",region="dev"} 5
# HELP huatuo_bamai_arp_total all entries in arp_cache for containers and host netns
# TYPE huatuo_bamai_arp_total gauge
huatuo_bamai_arp_total{host="hostname",region="dev"} 12
| Metric |
Description |
Unit |
Scope |
Labels |
| arp_entries |
Number of ARP entries in the host’s network namespace |
count |
Host namespace |
host, region |
| arp_total |
Total number of ARP entries across all network namespaces on the host |
count |
Host |
host, region |
| arp_container_entries |
Number of ARP entries in the container’s network namespace |
count |
Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
Qdisc
Qdisc (Queueing Discipline) is a key module in the Linux kernel networking subsystem. Monitoring this module provides clear visibility into network packet processing and latency behavior.
# HELP huatuo_bamai_netdev_qdisc_backlog Number of bytes currently in queue to be sent.
# TYPE huatuo_bamai_netdev_qdisc_backlog gauge
huatuo_bamai_netdev_qdisc_backlog{device="ens2",host="hostname",kind="fq_codel",region="dev"} 0
# HELP huatuo_bamai_netdev_qdisc_bytes_total Number of bytes sent.
# TYPE huatuo_bamai_netdev_qdisc_bytes_total counter
huatuo_bamai_netdev_qdisc_bytes_total{device="ens2",host="hostname",kind="fq_codel",region="dev"} 2.578235443e+09
# HELP huatuo_bamai_netdev_qdisc_current_queue_length Number of packets currently in queue to be sent.
# TYPE huatuo_bamai_netdev_qdisc_current_queue_length gauge
huatuo_bamai_netdev_qdisc_current_queue_length{device="ens2",host="hostname",kind="fq_codel",region="dev"} 0
# HELP huatuo_bamai_netdev_qdisc_drops_total Number of packet drops.
# TYPE huatuo_bamai_netdev_qdisc_drops_total counter
huatuo_bamai_netdev_qdisc_drops_total{device="ens2",host="hostname",kind="fq_codel",region="dev"} 0
# HELP huatuo_bamai_netdev_qdisc_overlimits_total Number of packet overlimits.
# TYPE huatuo_bamai_netdev_qdisc_overlimits_total counter
huatuo_bamai_netdev_qdisc_overlimits_total{device="ens2",host="hostname",kind="fq_codel",region="dev"} 0
# HELP huatuo_bamai_netdev_qdisc_packets_total Number of packets sent.
# TYPE huatuo_bamai_netdev_qdisc_packets_total counter
huatuo_bamai_netdev_qdisc_packets_total{device="ens2",host="hostname",kind="fq_codel",region="dev"} 6.867714e+06
# HELP huatuo_bamai_netdev_qdisc_requeues_total Number of packets dequeued, not transmitted, and requeued.
# TYPE huatuo_bamai_netdev_qdisc_requeues_total counter
huatuo_bamai_netdev_qdisc_requeues_total{device="ens2",host="hostname",kind="fq_codel",region="dev"} 0
| Metric |
Description |
Unit |
Scope |
Labels |
| qdisc_backlog |
Bytes of packets currently queued for transmission (backlog) |
Bytes |
Host |
device, host, kind, region |
| qdisc_current_queue_length |
Number of packets currently queued |
count |
Host |
device, host, kind, region |
| qdisc_overlimits_total |
Total number of times the queue limit was exceeded |
count |
Host |
device, host, kind, region |
| qdisc_requeues_total |
Number of times packets were requeued due to temporary inability of the NIC/driver to transmit |
count |
Host |
device, host, kind, region |
| qdisc_drops_total |
Total number of packets actively dropped |
count |
Host |
device, host, kind, region |
| qdisc_bytes_total |
Total bytes transmitted |
Bytes |
Host |
device, host, kind, region |
| qdisc_packets_total |
Total number of packets transmitted |
count |
Host |
device, host, kind, region |
Hardware
This metric tracks packets dropped by the network interface card (NIC) hardware in the receive (RX) path, typically due to buffer overflow, CRC errors, or other hardware-level issues.
# HELP huatuo_bamai_netdev_hw_rx_dropped count of packets dropped at hardware level
# TYPE huatuo_bamai_netdev_hw_rx_dropped gauge
huatuo_bamai_netdev_hw_rx_dropped{device="eth0",driver="mlx5_core",host="hostname",region="dev"} 0
| Metric |
Description |
Unit |
Scope |
Labels |
| netdev_hw_rx_dropped |
Number of packets dropped by NIC hardware in the receive direction |
count |
Host |
eBPF |
Netdev
# HELP huatuo_bamai_netdev_container_receive_bytes_total Network device statistic receive_bytes.
# TYPE huatuo_bamai_netdev_container_receive_bytes_total counter
huatuo_bamai_netdev_container_receive_bytes_total{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",device="eth0",host="hostname",region="dev"} 6.4400018e+07
# HELP huatuo_bamai_netdev_container_receive_compressed_total Network device statistic receive_compressed.
# TYPE huatuo_bamai_netdev_container_receive_compressed_total counter
huatuo_bamai_netdev_container_receive_compressed_total{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",device="eth0",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netdev_container_receive_dropped_total Network device statistic receive_dropped.
# TYPE huatuo_bamai_netdev_container_receive_dropped_total counter
huatuo_bamai_netdev_container_receive_dropped_total{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",device="eth0",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netdev_container_receive_errors_total Network device statistic receive_errors.
# TYPE huatuo_bamai_netdev_container_receive_errors_total counter
huatuo_bamai_netdev_container_receive_errors_total{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",device="eth0",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netdev_container_receive_fifo_total Network device statistic receive_fifo.
# TYPE huatuo_bamai_netdev_container_receive_fifo_total counter
huatuo_bamai_netdev_container_receive_fifo_total{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",device="eth0",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netdev_container_receive_frame_total Network device statistic receive_frame.
# TYPE huatuo_bamai_netdev_container_receive_frame_total counter
huatuo_bamai_netdev_container_receive_frame_total{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",device="eth0",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netdev_container_receive_multicast_total Network device statistic receive_multicast.
# TYPE huatuo_bamai_netdev_container_receive_multicast_total counter
huatuo_bamai_netdev_container_receive_multicast_total{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",device="eth0",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netdev_container_receive_packets_total Network device statistic receive_packets.
# TYPE huatuo_bamai_netdev_container_receive_packets_total counter
huatuo_bamai_netdev_container_receive_packets_total{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",device="eth0",host="hostname",region="dev"} 693155
# HELP huatuo_bamai_netdev_container_transmit_bytes_total Network device statistic transmit_bytes.
# TYPE huatuo_bamai_netdev_container_transmit_bytes_total counter
huatuo_bamai_netdev_container_transmit_bytes_total{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",device="eth0",host="hostname",region="dev"} 6.2347911e+07
# HELP huatuo_bamai_netdev_container_transmit_carrier_total Network device statistic transmit_carrier.
# TYPE huatuo_bamai_netdev_container_transmit_carrier_total counter
huatuo_bamai_netdev_container_transmit_carrier_total{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",device="eth0",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netdev_container_transmit_colls_total Network device statistic transmit_colls.
# TYPE huatuo_bamai_netdev_container_transmit_colls_total counter
huatuo_bamai_netdev_container_transmit_colls_total{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",device="eth0",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netdev_container_transmit_compressed_total Network device statistic transmit_compressed.
# TYPE huatuo_bamai_netdev_container_transmit_compressed_total counter
huatuo_bamai_netdev_container_transmit_compressed_total{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",device="eth0",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netdev_container_transmit_dropped_total Network device statistic transmit_dropped.
# TYPE huatuo_bamai_netdev_container_transmit_dropped_total counter
huatuo_bamai_netdev_container_transmit_dropped_total{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",device="eth0",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netdev_container_transmit_errors_total Network device statistic transmit_errors.
# TYPE huatuo_bamai_netdev_container_transmit_errors_total counter
huatuo_bamai_netdev_container_transmit_errors_total{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",device="eth0",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netdev_container_transmit_fifo_total Network device statistic transmit_fifo.
# TYPE huatuo_bamai_netdev_container_transmit_fifo_total counter
huatuo_bamai_netdev_container_transmit_fifo_total{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",device="eth0",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netdev_container_transmit_packets_total Network device statistic transmit_packets.
# TYPE huatuo_bamai_netdev_container_transmit_packets_total counter
huatuo_bamai_netdev_container_transmit_packets_total{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",device="eth0",host="hostname",region="dev"} 660218
| Metric |
Description |
Unit |
Scope |
Labels |
| netdev_receive_bytes_total |
Total number of bytes successfully received |
count |
Host, Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
| netdev_receive_packets_total |
Total number of packets successfully received |
count |
Host, Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
| netdev_receive_compressed_total |
Number of compressed packets received |
count |
Host, Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
| netdev_receive_frame_total |
Number of frame alignment errors on receive |
count |
Host, Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
| netdev_receive_errors_total |
Total number of receive errors |
count |
Host, Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
| netdev_receive_dropped_total |
Number of received packets dropped by kernel or driver (various reasons) |
count |
Host, Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
| netdev_receive_fifo_total |
Number of receive FIFO/ring buffer overflow errors |
count |
Host, Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
| netdev_transmit_bytes_total |
Total number of bytes successfully transmitted |
count |
Host, Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
| netdev_transmit_packets_total |
Total number of packets successfully transmitted |
count |
Host, Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
| netdev_transmit_errors_total |
Total number of transmit errors |
count |
Host, Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
| netdev_transmit_dropped_total |
Number of packets dropped during transmission (queue full, policy, etc.) |
count |
Host, Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
| netdev_transmit_fifo_total |
Number of transmit FIFO/ring buffer errors |
count |
Host, Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
| netdev_transmit_carrier_total |
Number of carrier errors (link down or cable issues during transmission) |
count |
Host, Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
| netdev_transmit_compressed_total |
Number of compressed packets transmitted |
count |
Host, Container |
container_host, container_hostnamespace, container_level, container_name, container_type, host, region |
Tcp Memory
From /proc/net/netstat
# HELP huatuo_bamai_tcp_memory_limit_pages tcp memory pages limit
# TYPE huatuo_bamai_tcp_memory_limit_pages gauge
huatuo_bamai_tcp_memory_limit_pages{host="hostname",region="dev"} 380526
# HELP huatuo_bamai_tcp_memory_usage_bytes tcp memory bytes usage
# TYPE huatuo_bamai_tcp_memory_usage_bytes gauge
huatuo_bamai_tcp_memory_usage_bytes{host="hostname",region="dev"} 0
# HELP huatuo_bamai_tcp_memory_usage_pages tcp memory pages usage
# TYPE huatuo_bamai_tcp_memory_usage_pages gauge
huatuo_bamai_tcp_memory_usage_pages{host="hostname",region="dev"} 0
# HELP huatuo_bamai_tcp_memory_usage_percent tcp memory usage percent
# TYPE huatuo_bamai_tcp_memory_usage_percent gauge
huatuo_bamai_tcp_memory_usage_percent{host="hostname",region="dev"} 0
TcpExt
Linux-specific TCP extended statistics (see kernel Documentation/networking/snmp_counter.rst):
- TcpExtListenDrops / ListenOverflows: drops due to full listen queue
- TcpExtSyncookiesSent / Recv / Failed: SYN cookies handling
- TcpExtTCPRcvCoalesce: packets coalesced in receive path
- TcpExtTCPAutoCorking: packets corked automatically
- TcpExtTCPOrigDataSent: original data bytes sent (excluding retransmits)
- TcpExtTCPLossProbes / TCPLossProbeRecovery: tail loss probe statistics
- TcpExtTCPAbortOn*: various abort reasons
- … (many more – refer to kernel snmp_counter documentation for complete list)
# HELP huatuo_bamai_netstat_container_TcpExt_ArpFilter statistic TcpExtArpFilter.
# TYPE huatuo_bamai_netstat_container_TcpExt_ArpFilter gauge
huatuo_bamai_netstat_container_TcpExt_ArpFilter{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_BusyPollRxPackets statistic TcpExtBusyPollRxPackets.
# TYPE huatuo_bamai_netstat_container_TcpExt_BusyPollRxPackets gauge
huatuo_bamai_netstat_container_TcpExt_BusyPollRxPackets{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_DelayedACKLocked statistic TcpExtDelayedACKLocked.
# TYPE huatuo_bamai_netstat_container_TcpExt_DelayedACKLocked gauge
huatuo_bamai_netstat_container_TcpExt_DelayedACKLocked{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_DelayedACKLost statistic TcpExtDelayedACKLost.
# TYPE huatuo_bamai_netstat_container_TcpExt_DelayedACKLost gauge
huatuo_bamai_netstat_container_TcpExt_DelayedACKLost{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_DelayedACKs statistic TcpExtDelayedACKs.
# TYPE huatuo_bamai_netstat_container_TcpExt_DelayedACKs gauge
huatuo_bamai_netstat_container_TcpExt_DelayedACKs{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 4650
# HELP huatuo_bamai_netstat_container_TcpExt_EmbryonicRsts statistic TcpExtEmbryonicRsts.
# TYPE huatuo_bamai_netstat_container_TcpExt_EmbryonicRsts gauge
huatuo_bamai_netstat_container_TcpExt_EmbryonicRsts{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_IPReversePathFilter statistic TcpExtIPReversePathFilter.
# TYPE huatuo_bamai_netstat_container_TcpExt_IPReversePathFilter gauge
huatuo_bamai_netstat_container_TcpExt_IPReversePathFilter{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_ListenDrops statistic TcpExtListenDrops.
# TYPE huatuo_bamai_netstat_container_TcpExt_ListenDrops gauge
huatuo_bamai_netstat_container_TcpExt_ListenDrops{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_ListenOverflows statistic TcpExtListenOverflows.
# TYPE huatuo_bamai_netstat_container_TcpExt_ListenOverflows gauge
huatuo_bamai_netstat_container_TcpExt_ListenOverflows{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_LockDroppedIcmps statistic TcpExtLockDroppedIcmps.
# TYPE huatuo_bamai_netstat_container_TcpExt_LockDroppedIcmps gauge
huatuo_bamai_netstat_container_TcpExt_LockDroppedIcmps{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_OfoPruned statistic TcpExtOfoPruned.
# TYPE huatuo_bamai_netstat_container_TcpExt_OfoPruned gauge
huatuo_bamai_netstat_container_TcpExt_OfoPruned{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_OutOfWindowIcmps statistic TcpExtOutOfWindowIcmps.
# TYPE huatuo_bamai_netstat_container_TcpExt_OutOfWindowIcmps gauge
huatuo_bamai_netstat_container_TcpExt_OutOfWindowIcmps{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_PAWSActive statistic TcpExtPAWSActive.
# TYPE huatuo_bamai_netstat_container_TcpExt_PAWSActive gauge
huatuo_bamai_netstat_container_TcpExt_PAWSActive{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_PAWSEstab statistic TcpExtPAWSEstab.
# TYPE huatuo_bamai_netstat_container_TcpExt_PAWSEstab gauge
huatuo_bamai_netstat_container_TcpExt_PAWSEstab{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_PFMemallocDrop statistic TcpExtPFMemallocDrop.
# TYPE huatuo_bamai_netstat_container_TcpExt_PFMemallocDrop gauge
huatuo_bamai_netstat_container_TcpExt_PFMemallocDrop{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_PruneCalled statistic TcpExtPruneCalled.
# TYPE huatuo_bamai_netstat_container_TcpExt_PruneCalled gauge
huatuo_bamai_netstat_container_TcpExt_PruneCalled{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_RcvPruned statistic TcpExtRcvPruned.
# TYPE huatuo_bamai_netstat_container_TcpExt_RcvPruned gauge
huatuo_bamai_netstat_container_TcpExt_RcvPruned{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_SyncookiesFailed statistic TcpExtSyncookiesFailed.
# TYPE huatuo_bamai_netstat_container_TcpExt_SyncookiesFailed gauge
huatuo_bamai_netstat_container_TcpExt_SyncookiesFailed{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_SyncookiesRecv statistic TcpExtSyncookiesRecv.
# TYPE huatuo_bamai_netstat_container_TcpExt_SyncookiesRecv gauge
huatuo_bamai_netstat_container_TcpExt_SyncookiesRecv{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_SyncookiesSent statistic TcpExtSyncookiesSent.
# TYPE huatuo_bamai_netstat_container_TcpExt_SyncookiesSent gauge
huatuo_bamai_netstat_container_TcpExt_SyncookiesSent{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPACKSkippedChallenge statistic TcpExtTCPACKSkippedChallenge.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPACKSkippedChallenge gauge
huatuo_bamai_netstat_container_TcpExt_TCPACKSkippedChallenge{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPACKSkippedFinWait2 statistic TcpExtTCPACKSkippedFinWait2.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPACKSkippedFinWait2 gauge
huatuo_bamai_netstat_container_TcpExt_TCPACKSkippedFinWait2{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPACKSkippedPAWS statistic TcpExtTCPACKSkippedPAWS.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPACKSkippedPAWS gauge
huatuo_bamai_netstat_container_TcpExt_TCPACKSkippedPAWS{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPACKSkippedSeq statistic TcpExtTCPACKSkippedSeq.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPACKSkippedSeq gauge
huatuo_bamai_netstat_container_TcpExt_TCPACKSkippedSeq{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPACKSkippedSynRecv statistic TcpExtTCPACKSkippedSynRecv.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPACKSkippedSynRecv gauge
huatuo_bamai_netstat_container_TcpExt_TCPACKSkippedSynRecv{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPACKSkippedTimeWait statistic TcpExtTCPACKSkippedTimeWait.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPACKSkippedTimeWait gauge
huatuo_bamai_netstat_container_TcpExt_TCPACKSkippedTimeWait{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPAOBad statistic TcpExtTCPAOBad.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPAOBad gauge
huatuo_bamai_netstat_container_TcpExt_TCPAOBad{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPAODroppedIcmps statistic TcpExtTCPAODroppedIcmps.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPAODroppedIcmps gauge
huatuo_bamai_netstat_container_TcpExt_TCPAODroppedIcmps{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPAOGood statistic TcpExtTCPAOGood.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPAOGood gauge
huatuo_bamai_netstat_container_TcpExt_TCPAOGood{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPAOKeyNotFound statistic TcpExtTCPAOKeyNotFound.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPAOKeyNotFound gauge
huatuo_bamai_netstat_container_TcpExt_TCPAOKeyNotFound{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPAORequired statistic TcpExtTCPAORequired.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPAORequired gauge
huatuo_bamai_netstat_container_TcpExt_TCPAORequired{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPAbortFailed statistic TcpExtTCPAbortFailed.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPAbortFailed gauge
huatuo_bamai_netstat_container_TcpExt_TCPAbortFailed{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPAbortOnClose statistic TcpExtTCPAbortOnClose.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPAbortOnClose gauge
huatuo_bamai_netstat_container_TcpExt_TCPAbortOnClose{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 1
# HELP huatuo_bamai_netstat_container_TcpExt_TCPAbortOnData statistic TcpExtTCPAbortOnData.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPAbortOnData gauge
huatuo_bamai_netstat_container_TcpExt_TCPAbortOnData{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPAbortOnLinger statistic TcpExtTCPAbortOnLinger.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPAbortOnLinger gauge
huatuo_bamai_netstat_container_TcpExt_TCPAbortOnLinger{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPAbortOnMemory statistic TcpExtTCPAbortOnMemory.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPAbortOnMemory gauge
huatuo_bamai_netstat_container_TcpExt_TCPAbortOnMemory{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPAbortOnTimeout statistic TcpExtTCPAbortOnTimeout.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPAbortOnTimeout gauge
huatuo_bamai_netstat_container_TcpExt_TCPAbortOnTimeout{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPAckCompressed statistic TcpExtTCPAckCompressed.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPAckCompressed gauge
huatuo_bamai_netstat_container_TcpExt_TCPAckCompressed{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPAutoCorking statistic TcpExtTCPAutoCorking.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPAutoCorking gauge
huatuo_bamai_netstat_container_TcpExt_TCPAutoCorking{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPBacklogCoalesce statistic TcpExtTCPBacklogCoalesce.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPBacklogCoalesce gauge
huatuo_bamai_netstat_container_TcpExt_TCPBacklogCoalesce{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 3
# HELP huatuo_bamai_netstat_container_TcpExt_TCPBacklogDrop statistic TcpExtTCPBacklogDrop.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPBacklogDrop gauge
huatuo_bamai_netstat_container_TcpExt_TCPBacklogDrop{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPChallengeACK statistic TcpExtTCPChallengeACK.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPChallengeACK gauge
huatuo_bamai_netstat_container_TcpExt_TCPChallengeACK{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPDSACKIgnoredDubious statistic TcpExtTCPDSACKIgnoredDubious.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPDSACKIgnoredDubious gauge
huatuo_bamai_netstat_container_TcpExt_TCPDSACKIgnoredDubious{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPDSACKIgnoredNoUndo statistic TcpExtTCPDSACKIgnoredNoUndo.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPDSACKIgnoredNoUndo gauge
huatuo_bamai_netstat_container_TcpExt_TCPDSACKIgnoredNoUndo{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 1
# HELP huatuo_bamai_netstat_container_TcpExt_TCPDSACKIgnoredOld statistic TcpExtTCPDSACKIgnoredOld.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPDSACKIgnoredOld gauge
huatuo_bamai_netstat_container_TcpExt_TCPDSACKIgnoredOld{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPDSACKOfoRecv statistic TcpExtTCPDSACKOfoRecv.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPDSACKOfoRecv gauge
huatuo_bamai_netstat_container_TcpExt_TCPDSACKOfoRecv{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPDSACKOfoSent statistic TcpExtTCPDSACKOfoSent.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPDSACKOfoSent gauge
huatuo_bamai_netstat_container_TcpExt_TCPDSACKOfoSent{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPDSACKOldSent statistic TcpExtTCPDSACKOldSent.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPDSACKOldSent gauge
huatuo_bamai_netstat_container_TcpExt_TCPDSACKOldSent{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPDSACKRecv statistic TcpExtTCPDSACKRecv.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPDSACKRecv gauge
huatuo_bamai_netstat_container_TcpExt_TCPDSACKRecv{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 1
# HELP huatuo_bamai_netstat_container_TcpExt_TCPDSACKRecvSegs statistic TcpExtTCPDSACKRecvSegs.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPDSACKRecvSegs gauge
huatuo_bamai_netstat_container_TcpExt_TCPDSACKRecvSegs{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 1
# HELP huatuo_bamai_netstat_container_TcpExt_TCPDSACKUndo statistic TcpExtTCPDSACKUndo.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPDSACKUndo gauge
huatuo_bamai_netstat_container_TcpExt_TCPDSACKUndo{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPDeferAcceptDrop statistic TcpExtTCPDeferAcceptDrop.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPDeferAcceptDrop gauge
huatuo_bamai_netstat_container_TcpExt_TCPDeferAcceptDrop{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPDelivered statistic TcpExtTCPDelivered.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPDelivered gauge
huatuo_bamai_netstat_container_TcpExt_TCPDelivered{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 3.28098e+06
# HELP huatuo_bamai_netstat_container_TcpExt_TCPDeliveredCE statistic TcpExtTCPDeliveredCE.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPDeliveredCE gauge
huatuo_bamai_netstat_container_TcpExt_TCPDeliveredCE{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPFastOpenActive statistic TcpExtTCPFastOpenActive.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPFastOpenActive gauge
huatuo_bamai_netstat_container_TcpExt_TCPFastOpenActive{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPFastOpenActiveFail statistic TcpExtTCPFastOpenActiveFail.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPFastOpenActiveFail gauge
huatuo_bamai_netstat_container_TcpExt_TCPFastOpenActiveFail{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPFastOpenBlackhole statistic TcpExtTCPFastOpenBlackhole.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPFastOpenBlackhole gauge
huatuo_bamai_netstat_container_TcpExt_TCPFastOpenBlackhole{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPFastOpenCookieReqd statistic TcpExtTCPFastOpenCookieReqd.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPFastOpenCookieReqd gauge
huatuo_bamai_netstat_container_TcpExt_TCPFastOpenCookieReqd{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPFastOpenListenOverflow statistic TcpExtTCPFastOpenListenOverflow.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPFastOpenListenOverflow gauge
huatuo_bamai_netstat_container_TcpExt_TCPFastOpenListenOverflow{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPFastOpenPassive statistic TcpExtTCPFastOpenPassive.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPFastOpenPassive gauge
huatuo_bamai_netstat_container_TcpExt_TCPFastOpenPassive{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPFastOpenPassiveAltKey statistic TcpExtTCPFastOpenPassiveAltKey.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPFastOpenPassiveAltKey gauge
huatuo_bamai_netstat_container_TcpExt_TCPFastOpenPassiveAltKey{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPFastOpenPassiveFail statistic TcpExtTCPFastOpenPassiveFail.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPFastOpenPassiveFail gauge
huatuo_bamai_netstat_container_TcpExt_TCPFastOpenPassiveFail{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPFastRetrans statistic TcpExtTCPFastRetrans.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPFastRetrans gauge
huatuo_bamai_netstat_container_TcpExt_TCPFastRetrans{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPFromZeroWindowAdv statistic TcpExtTCPFromZeroWindowAdv.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPFromZeroWindowAdv gauge
huatuo_bamai_netstat_container_TcpExt_TCPFromZeroWindowAdv{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPFullUndo statistic TcpExtTCPFullUndo.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPFullUndo gauge
huatuo_bamai_netstat_container_TcpExt_TCPFullUndo{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPHPAcks statistic TcpExtTCPHPAcks.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPHPAcks gauge
huatuo_bamai_netstat_container_TcpExt_TCPHPAcks{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 616667
# HELP huatuo_bamai_netstat_container_TcpExt_TCPHPHits statistic TcpExtTCPHPHits.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPHPHits gauge
huatuo_bamai_netstat_container_TcpExt_TCPHPHits{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 9913
# HELP huatuo_bamai_netstat_container_TcpExt_TCPHystartDelayCwnd statistic TcpExtTCPHystartDelayCwnd.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPHystartDelayCwnd gauge
huatuo_bamai_netstat_container_TcpExt_TCPHystartDelayCwnd{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPHystartDelayDetect statistic TcpExtTCPHystartDelayDetect.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPHystartDelayDetect gauge
huatuo_bamai_netstat_container_TcpExt_TCPHystartDelayDetect{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPHystartTrainCwnd statistic TcpExtTCPHystartTrainCwnd.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPHystartTrainCwnd gauge
huatuo_bamai_netstat_container_TcpExt_TCPHystartTrainCwnd{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPHystartTrainDetect statistic TcpExtTCPHystartTrainDetect.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPHystartTrainDetect gauge
huatuo_bamai_netstat_container_TcpExt_TCPHystartTrainDetect{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPKeepAlive statistic TcpExtTCPKeepAlive.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPKeepAlive gauge
huatuo_bamai_netstat_container_TcpExt_TCPKeepAlive{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 20
# HELP huatuo_bamai_netstat_container_TcpExt_TCPLossFailures statistic TcpExtTCPLossFailures.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPLossFailures gauge
huatuo_bamai_netstat_container_TcpExt_TCPLossFailures{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPLossProbeRecovery statistic TcpExtTCPLossProbeRecovery.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPLossProbeRecovery gauge
huatuo_bamai_netstat_container_TcpExt_TCPLossProbeRecovery{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPLossProbes statistic TcpExtTCPLossProbes.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPLossProbes gauge
huatuo_bamai_netstat_container_TcpExt_TCPLossProbes{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 1
# HELP huatuo_bamai_netstat_container_TcpExt_TCPLossUndo statistic TcpExtTCPLossUndo.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPLossUndo gauge
huatuo_bamai_netstat_container_TcpExt_TCPLossUndo{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPLostRetransmit statistic TcpExtTCPLostRetransmit.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPLostRetransmit gauge
huatuo_bamai_netstat_container_TcpExt_TCPLostRetransmit{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPMD5Failure statistic TcpExtTCPMD5Failure.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPMD5Failure gauge
huatuo_bamai_netstat_container_TcpExt_TCPMD5Failure{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPMD5NotFound statistic TcpExtTCPMD5NotFound.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPMD5NotFound gauge
huatuo_bamai_netstat_container_TcpExt_TCPMD5NotFound{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPMD5Unexpected statistic TcpExtTCPMD5Unexpected.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPMD5Unexpected gauge
huatuo_bamai_netstat_container_TcpExt_TCPMD5Unexpected{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPMTUPFail statistic TcpExtTCPMTUPFail.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPMTUPFail gauge
huatuo_bamai_netstat_container_TcpExt_TCPMTUPFail{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPMTUPSuccess statistic TcpExtTCPMTUPSuccess.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPMTUPSuccess gauge
huatuo_bamai_netstat_container_TcpExt_TCPMTUPSuccess{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPMemoryPressures statistic TcpExtTCPMemoryPressures.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPMemoryPressures gauge
huatuo_bamai_netstat_container_TcpExt_TCPMemoryPressures{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPMemoryPressuresChrono statistic TcpExtTCPMemoryPressuresChrono.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPMemoryPressuresChrono gauge
huatuo_bamai_netstat_container_TcpExt_TCPMemoryPressuresChrono{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPMigrateReqFailure statistic TcpExtTCPMigrateReqFailure.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPMigrateReqFailure gauge
huatuo_bamai_netstat_container_TcpExt_TCPMigrateReqFailure{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPMigrateReqSuccess statistic TcpExtTCPMigrateReqSuccess.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPMigrateReqSuccess gauge
huatuo_bamai_netstat_container_TcpExt_TCPMigrateReqSuccess{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPMinTTLDrop statistic TcpExtTCPMinTTLDrop.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPMinTTLDrop gauge
huatuo_bamai_netstat_container_TcpExt_TCPMinTTLDrop{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPOFODrop statistic TcpExtTCPOFODrop.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPOFODrop gauge
huatuo_bamai_netstat_container_TcpExt_TCPOFODrop{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPOFOMerge statistic TcpExtTCPOFOMerge.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPOFOMerge gauge
huatuo_bamai_netstat_container_TcpExt_TCPOFOMerge{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPOFOQueue statistic TcpExtTCPOFOQueue.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPOFOQueue gauge
huatuo_bamai_netstat_container_TcpExt_TCPOFOQueue{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPOrigDataSent statistic TcpExtTCPOrigDataSent.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPOrigDataSent gauge
huatuo_bamai_netstat_container_TcpExt_TCPOrigDataSent{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 2.675557e+06
# HELP huatuo_bamai_netstat_container_TcpExt_TCPPLBRehash statistic TcpExtTCPPLBRehash.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPPLBRehash gauge
huatuo_bamai_netstat_container_TcpExt_TCPPLBRehash{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPPartialUndo statistic TcpExtTCPPartialUndo.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPPartialUndo gauge
huatuo_bamai_netstat_container_TcpExt_TCPPartialUndo{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPPureAcks statistic TcpExtTCPPureAcks.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPPureAcks gauge
huatuo_bamai_netstat_container_TcpExt_TCPPureAcks{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 2.095262e+06
# HELP huatuo_bamai_netstat_container_TcpExt_TCPRcvCoalesce statistic TcpExtTCPRcvCoalesce.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPRcvCoalesce gauge
huatuo_bamai_netstat_container_TcpExt_TCPRcvCoalesce{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 3
# HELP huatuo_bamai_netstat_container_TcpExt_TCPRcvCollapsed statistic TcpExtTCPRcvCollapsed.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPRcvCollapsed gauge
huatuo_bamai_netstat_container_TcpExt_TCPRcvCollapsed{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPRcvQDrop statistic TcpExtTCPRcvQDrop.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPRcvQDrop gauge
huatuo_bamai_netstat_container_TcpExt_TCPRcvQDrop{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPRenoFailures statistic TcpExtTCPRenoFailures.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPRenoFailures gauge
huatuo_bamai_netstat_container_TcpExt_TCPRenoFailures{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPRenoRecovery statistic TcpExtTCPRenoRecovery.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPRenoRecovery gauge
huatuo_bamai_netstat_container_TcpExt_TCPRenoRecovery{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPRenoRecoveryFail statistic TcpExtTCPRenoRecoveryFail.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPRenoRecoveryFail gauge
huatuo_bamai_netstat_container_TcpExt_TCPRenoRecoveryFail{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPRenoReorder statistic TcpExtTCPRenoReorder.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPRenoReorder gauge
huatuo_bamai_netstat_container_TcpExt_TCPRenoReorder{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPReqQFullDoCookies statistic TcpExtTCPReqQFullDoCookies.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPReqQFullDoCookies gauge
huatuo_bamai_netstat_container_TcpExt_TCPReqQFullDoCookies{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPReqQFullDrop statistic TcpExtTCPReqQFullDrop.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPReqQFullDrop gauge
huatuo_bamai_netstat_container_TcpExt_TCPReqQFullDrop{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPRetransFail statistic TcpExtTCPRetransFail.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPRetransFail gauge
huatuo_bamai_netstat_container_TcpExt_TCPRetransFail{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPSACKDiscard statistic TcpExtTCPSACKDiscard.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPSACKDiscard gauge
huatuo_bamai_netstat_container_TcpExt_TCPSACKDiscard{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPSACKReneging statistic TcpExtTCPSACKReneging.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPSACKReneging gauge
huatuo_bamai_netstat_container_TcpExt_TCPSACKReneging{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPSACKReorder statistic TcpExtTCPSACKReorder.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPSACKReorder gauge
huatuo_bamai_netstat_container_TcpExt_TCPSACKReorder{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPSYNChallenge statistic TcpExtTCPSYNChallenge.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPSYNChallenge gauge
huatuo_bamai_netstat_container_TcpExt_TCPSYNChallenge{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPSackFailures statistic TcpExtTCPSackFailures.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPSackFailures gauge
huatuo_bamai_netstat_container_TcpExt_TCPSackFailures{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPSackMerged statistic TcpExtTCPSackMerged.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPSackMerged gauge
huatuo_bamai_netstat_container_TcpExt_TCPSackMerged{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPSackRecovery statistic TcpExtTCPSackRecovery.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPSackRecovery gauge
huatuo_bamai_netstat_container_TcpExt_TCPSackRecovery{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPSackRecoveryFail statistic TcpExtTCPSackRecoveryFail.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPSackRecoveryFail gauge
huatuo_bamai_netstat_container_TcpExt_TCPSackRecoveryFail{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPSackShiftFallback statistic TcpExtTCPSackShiftFallback.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPSackShiftFallback gauge
huatuo_bamai_netstat_container_TcpExt_TCPSackShiftFallback{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPSackShifted statistic TcpExtTCPSackShifted.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPSackShifted gauge
huatuo_bamai_netstat_container_TcpExt_TCPSackShifted{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPSlowStartRetrans statistic TcpExtTCPSlowStartRetrans.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPSlowStartRetrans gauge
huatuo_bamai_netstat_container_TcpExt_TCPSlowStartRetrans{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPSpuriousRTOs statistic TcpExtTCPSpuriousRTOs.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPSpuriousRTOs gauge
huatuo_bamai_netstat_container_TcpExt_TCPSpuriousRTOs{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPSpuriousRtxHostQueues statistic TcpExtTCPSpuriousRtxHostQueues.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPSpuriousRtxHostQueues gauge
huatuo_bamai_netstat_container_TcpExt_TCPSpuriousRtxHostQueues{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPSynRetrans statistic TcpExtTCPSynRetrans.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPSynRetrans gauge
huatuo_bamai_netstat_container_TcpExt_TCPSynRetrans{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPTSReorder statistic TcpExtTCPTSReorder.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPTSReorder gauge
huatuo_bamai_netstat_container_TcpExt_TCPTSReorder{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPTimeWaitOverflow statistic TcpExtTCPTimeWaitOverflow.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPTimeWaitOverflow gauge
huatuo_bamai_netstat_container_TcpExt_TCPTimeWaitOverflow{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPTimeouts statistic TcpExtTCPTimeouts.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPTimeouts gauge
huatuo_bamai_netstat_container_TcpExt_TCPTimeouts{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPToZeroWindowAdv statistic TcpExtTCPToZeroWindowAdv.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPToZeroWindowAdv gauge
huatuo_bamai_netstat_container_TcpExt_TCPToZeroWindowAdv{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPWantZeroWindowAdv statistic TcpExtTCPWantZeroWindowAdv.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPWantZeroWindowAdv gauge
huatuo_bamai_netstat_container_TcpExt_TCPWantZeroWindowAdv{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPWinProbe statistic TcpExtTCPWinProbe.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPWinProbe gauge
huatuo_bamai_netstat_container_TcpExt_TCPWinProbe{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPWqueueTooBig statistic TcpExtTCPWqueueTooBig.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPWqueueTooBig gauge
huatuo_bamai_netstat_container_TcpExt_TCPWqueueTooBig{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TCPZeroWindowDrop statistic TcpExtTCPZeroWindowDrop.
# TYPE huatuo_bamai_netstat_container_TcpExt_TCPZeroWindowDrop gauge
huatuo_bamai_netstat_container_TcpExt_TCPZeroWindowDrop{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TW statistic TcpExtTW.
# TYPE huatuo_bamai_netstat_container_TcpExt_TW gauge
huatuo_bamai_netstat_container_TcpExt_TW{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 720624
# HELP huatuo_bamai_netstat_container_TcpExt_TWKilled statistic TcpExtTWKilled.
# TYPE huatuo_bamai_netstat_container_TcpExt_TWKilled gauge
huatuo_bamai_netstat_container_TcpExt_TWKilled{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TWRecycled statistic TcpExtTWRecycled.
# TYPE huatuo_bamai_netstat_container_TcpExt_TWRecycled gauge
huatuo_bamai_netstat_container_TcpExt_TWRecycled{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 2461
# HELP huatuo_bamai_netstat_container_TcpExt_TcpDuplicateDataRehash statistic TcpExtTcpDuplicateDataRehash.
# TYPE huatuo_bamai_netstat_container_TcpExt_TcpDuplicateDataRehash gauge
huatuo_bamai_netstat_container_TcpExt_TcpDuplicateDataRehash{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_netstat_container_TcpExt_TcpTimeoutRehash statistic TcpExtTcpTimeoutRehash.
# TYPE huatuo_bamai_netstat_container_TcpExt_TcpTimeoutRehash gauge
huatuo_bamai_netstat_container_TcpExt_TcpTimeoutRehash{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
Ref:
Socket
# HELP huatuo_bamai_sockstat_container_FRAG_inuse Number of FRAG sockets in state inuse.
# TYPE huatuo_bamai_sockstat_container_FRAG_inuse gauge
huatuo_bamai_sockstat_container_FRAG_inuse{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_sockstat_container_FRAG_memory Number of FRAG sockets in state memory.
# TYPE huatuo_bamai_sockstat_container_FRAG_memory gauge
huatuo_bamai_sockstat_container_FRAG_memory{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_sockstat_container_RAW_inuse Number of RAW sockets in state inuse.
# TYPE huatuo_bamai_sockstat_container_RAW_inuse gauge
huatuo_bamai_sockstat_container_RAW_inuse{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_sockstat_container_TCP_alloc Number of TCP sockets in state alloc.
# TYPE huatuo_bamai_sockstat_container_TCP_alloc gauge
huatuo_bamai_sockstat_container_TCP_alloc{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 171
# HELP huatuo_bamai_sockstat_container_TCP_inuse Number of TCP sockets in state inuse.
# TYPE huatuo_bamai_sockstat_container_TCP_inuse gauge
huatuo_bamai_sockstat_container_TCP_inuse{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 1
# HELP huatuo_bamai_sockstat_container_TCP_orphan Number of TCP sockets in state orphan.
# TYPE huatuo_bamai_sockstat_container_TCP_orphan gauge
huatuo_bamai_sockstat_container_TCP_orphan{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_sockstat_container_TCP_tw Number of TCP sockets in state tw.
# TYPE huatuo_bamai_sockstat_container_TCP_tw gauge
huatuo_bamai_sockstat_container_TCP_tw{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 75
# HELP huatuo_bamai_sockstat_container_UDPLITE_inuse Number of UDPLITE sockets in state inuse.
# TYPE huatuo_bamai_sockstat_container_UDPLITE_inuse gauge
huatuo_bamai_sockstat_container_UDPLITE_inuse{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_sockstat_container_UDP_inuse Number of UDP sockets in state inuse.
# TYPE huatuo_bamai_sockstat_container_UDP_inuse gauge
huatuo_bamai_sockstat_container_UDP_inuse{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 0
# HELP huatuo_bamai_sockstat_container_sockets_used Number of IPv4 sockets in use.
# TYPE huatuo_bamai_sockstat_container_sockets_used gauge
huatuo_bamai_sockstat_container_sockets_used{container_host="coredns-855c4dd65d-8v5kg",container_hostnamespace="kube-system",container_level="burstable",container_name="coredns",container_type="normal",host="hostname",region="dev"} 7
# HELP huatuo_bamai_sockstat_sockets_used Number of IPv4 sockets in use.
# TYPE huatuo_bamai_sockstat_sockets_used gauge
huatuo_bamai_sockstat_sockets_used{host="hostname",region="dev"} 409
| Metric |
Description |
Unit |
Scope |
Labels |
| sockstat_sockets_used |
Total number of sockets currently in use on the system |
count |
Host |
|
| sockstat_TCP_inuse |
Number of TCP sockets in active connection states |
count |
Host, Container |
|
| sockstat_TCP_orphan |
Number of TCP sockets without an owning process |
count |
Host, Container |
|
| sockstat_TCP_tw |
Number of TCP sockets currently in TIME_WAIT state |
count |
Host, Container |
|
| sockstat_TCP_alloc |
Total number of allocated TCP socket objects |
count |
Host, Container |
|
| sockstat_TCP_mem |
Number of memory pages currently used by TCP sockets |
count |
Host |
|
IO
iolatency tracks disk I/O latency distribution. A simple way to read it is: break one disk request into stages, then count how many requests fall into each latency bucket.
q2c: from entering the queue to completion, covering the full I/O lifecycled2c: from driver dispatch to completion, closer to device-side latencyfreeze: number of disk freeze events
The current version exposes both host-level and container-level metrics.
Queue
These metrics always include the common labels host and region. Container
metrics also always include container_host, container_name,
container_type, container_level, and container_hostnamespace.
# HELP huatuo_bamai_iolatency_blkdisk_d2c the disk d2c latency
# TYPE huatuo_bamai_iolatency_blkdisk_d2c gauge
huatuo_bamai_iolatency_blkdisk_d2c{disk="253:1",host="hostname",region="dev",zone="0"} 3
# HELP huatuo_bamai_iolatency_blkdisk_q2c the disk q2c latency
# TYPE huatuo_bamai_iolatency_blkdisk_q2c gauge
huatuo_bamai_iolatency_blkdisk_q2c{disk="253:1",host="hostname",region="dev",zone="0"} 3
# HELP huatuo_bamai_iolatency_container_blkdisk_d2c container blkio d2c latency
# TYPE huatuo_bamai_iolatency_container_blkdisk_d2c gauge
huatuo_bamai_iolatency_container_blkdisk_d2c{container_host="etcd-hostname",container_hostnamespace="kube-system",container_level="burstable",container_name="etcd",container_type="normal",disk="253:1",host="hostname",region="dev",zone="5"} 2
# HELP huatuo_bamai_iolatency_container_blkdisk_q2c container blkio q2c latency
# TYPE huatuo_bamai_iolatency_container_blkdisk_q2c gauge
huatuo_bamai_iolatency_container_blkdisk_q2c{container_host="etcd-hostname",container_hostnamespace="kube-system",container_level="burstable",container_name="etcd",container_type="normal",disk="253:1",host="hostname",region="dev",zone="5"} 2
| Metric |
Description |
Unit |
Scope |
Labels |
| iolatency_blkdisk_q2c |
Host disk latency statistics for the full I/O lifecycle, from queueing to completion. Buckets: zone0 20-30ms, zone1 30-50ms, zone2 50-100ms, zone3 100-200ms, zone4 200-400ms, zone5 400ms+ |
count |
Host |
host, region, disk, zone |
| iolatency_blkdisk_d2c |
Host disk latency statistics from driver dispatch to completion, closer to device processing time. Buckets: zone0 20-30ms, zone1 30-50ms, zone2 50-100ms, zone3 100-200ms, zone4 200-400ms, zone5 400ms+ |
count |
Host |
host, region, disk, zone |
| iolatency_container_blkdisk_q2c |
Container-caused latency statistics for the full I/O lifecycle, from queueing to completion. Buckets: zone0 20-30ms, zone1 30-50ms, zone2 50-100ms, zone3 100-200ms, zone4 200-400ms, zone5 400ms+ |
count |
Container |
host, region, container_host, container_name, container_type, container_level, container_hostnamespace, zone |
| iolatency_container_blkdisk_d2c |
Container-caused latency statistics from driver dispatch to completion. Buckets: zone0 20-30ms, zone1 30-50ms, zone2 50-100ms, zone3 100-200ms, zone4 200-400ms, zone5 400ms+ |
count |
Container |
host, region, container_host, container_name, container_type, container_level, container_hostnamespace, zone |
Hardware
# HELP huatuo_bamai_iolatency_blkdisk_freeze the disk freeze event count
# TYPE huatuo_bamai_iolatency_blkdisk_freeze gauge
huatuo_bamai_iolatency_blkdisk_freeze{disk="253:1",host="hostname",region="dev"} 0
| Metric |
Description |
Unit |
Scope |
Labels |
| iolatency_blkdisk_freeze |
Host disk freeze event count |
count |
Host |
host, region, disk |
Disk IO Statistics
diskio collects per-device disk IO metrics and system-wide CPU iowait by reading /proc/diskstats and /proc/stat. Unlike iolatency, diskio is procfs-based rather than eBPF-based, providing cumulative counters that support rate-based latency calculations.
The default configuration disables this collector through BlackList. Remove
diskio from BlackList to enable these metrics.
Counter metrics are cumulative; use Prometheus rate() for per-second values (IOPS, throughput). Gauge metrics are point-in-time values. Average latency is computed in PromQL by dividing the I/O time rate by the request rate.
# HELP huatuo_bamai_diskio_read_requests_total Total number of read requests completed successfully.
# TYPE huatuo_bamai_diskio_read_requests_total counter
huatuo_bamai_diskio_read_requests_total{device="sda",host="hostname",region="dev"} 1000
# HELP huatuo_bamai_diskio_write_requests_total Total number of write requests completed successfully.
# TYPE huatuo_bamai_diskio_write_requests_total counter
huatuo_bamai_diskio_write_requests_total{device="sda",host="hostname",region="dev"} 2000
# HELP huatuo_bamai_diskio_read_bytes_total Total number of bytes read from the device.
# TYPE huatuo_bamai_diskio_read_bytes_total counter
huatuo_bamai_diskio_read_bytes_total{device="sda",host="hostname",region="dev"} 2.56e+07
# HELP huatuo_bamai_diskio_written_bytes_total Total number of bytes written to the device.
# TYPE huatuo_bamai_diskio_written_bytes_total counter
huatuo_bamai_diskio_written_bytes_total{device="sda",host="hostname",region="dev"} 4.096e+07
# HELP huatuo_bamai_diskio_io_in_progress Number of I/O requests currently in flight (queue depth).
# TYPE huatuo_bamai_diskio_io_in_progress gauge
huatuo_bamai_diskio_io_in_progress{device="sda",host="hostname",region="dev"} 50
# HELP huatuo_bamai_diskio_read_time_seconds_total Total seconds spent by completed read requests.
# TYPE huatuo_bamai_diskio_read_time_seconds_total counter
huatuo_bamai_diskio_read_time_seconds_total{device="sda",host="hostname",region="dev"} 3
# HELP huatuo_bamai_diskio_write_time_seconds_total Total seconds spent by completed write requests.
# TYPE huatuo_bamai_diskio_write_time_seconds_total counter
huatuo_bamai_diskio_write_time_seconds_total{device="sda",host="hostname",region="dev"} 6
# HELP huatuo_bamai_diskio_disk_iowait_percent CPU time spent waiting for I/O during the collection interval.
# TYPE huatuo_bamai_diskio_disk_iowait_percent gauge
huatuo_bamai_diskio_disk_iowait_percent{host="hostname",region="dev"} 50
| Metric |
Description |
Unit |
Scope |
Labels |
| read_requests_total |
Cumulative read requests completed (field 4). Use rate() for read IOPS |
count |
Host |
host, region, device |
| write_requests_total |
Cumulative write requests completed (field 8). Use rate() for write IOPS |
count |
Host |
host, region, device |
| read_bytes_total |
Cumulative bytes read (field 6 × 512). Use rate() for read throughput |
bytes |
Host |
host, region, device |
| written_bytes_total |
Cumulative bytes written (field 10 × 512). Use rate() for write throughput |
bytes |
Host |
host, region, device |
| read_time_seconds_total |
Cumulative seconds spent by completed reads (field 7) |
seconds |
Host |
host, region, device |
| write_time_seconds_total |
Cumulative seconds spent by completed writes (field 11) |
seconds |
Host |
host, region, device |
| io_in_progress |
Current number of I/O requests in flight, i.e. queue depth (field 12) |
count |
Host |
host, region, device |
| disk_iowait_percent |
CPU time spent waiting for I/O during the collection interval |
percent |
Host |
host, region |
XFS Filesystem Statistics
xfs collects per-device statistics from sysfs. Metrics use the
huatuo_bamai_xfs_ prefix and device, host, region labels.
log_free_bytes is a gauge; _total metrics are cumulative counters.
| Metric suffix |
Description |
Unit |
| log_free_bytes |
Available log space |
bytes |
| log_space_sleep_total |
Cumulative waits for log space |
count |
| alloc_blocks_total |
Cumulative allocated blocks |
blocks |
| alloc_extents_total |
Cumulative allocated extents |
count |
| inode_attempts_total |
Cumulative inode cache requests |
count |
| inode_missed_total |
Cumulative inode cache misses |
count |
| buf_busy_locked_total |
Cumulative busy-locked buffer events |
count |
| buf_locked_waited_total |
Cumulative waits for buffer locks |
count |
log_free_bytes is omitted when log-space information is unavailable.
Restart the daemon after adding XFS mounts.
General System
Soft Lockup
# HELP huatuo_bamai_softlockup_total softlockup counter
# TYPE huatuo_bamai_softlockup_total counter
huatuo_bamai_softlockup_total{host="hostname",region="dev"} 0
| Metric |
Description |
Unit |
Target |
Source |
Labels |
| softlockup_total |
Count of soft lockup events |
count |
Host |
BPF |
|
HungTask
# HELP huatuo_bamai_hungtask_total hungtask counter
# TYPE huatuo_bamai_hungtask_total counter
huatuo_bamai_hungtask_total{host="hostname",region="dev"} 0
| Metric |
Description |
Unit |
Target |
Source |
Labels |
| hungtask_total |
Count of hung task events |
count |
Host |
BPF |
|
GPU
| Metric |
Description |
Unit |
Target |
Source |
| metax_gpu_sdk_info |
GPU SDK info. |
- |
version |
sml.GetSDKVersion |
| metax_gpu_driver_info |
GPU driver info. |
- |
version |
sml.GetGPUVersion with driver unit |
| metax_gpu_info |
GPU info. |
- |
gpu, model, uuid, bios_version, bdf, mode, die_count |
sml.GetGPUInfo |
| metax_gpu_board_power_watts |
GPU board power. |
W |
gpu |
sml.ListGPUBoardWayElectricInfos |
| metax_gpu_pcie_link_speed_gt_per_second |
GPU PCIe current link speed. |
GT/s |
gpu |
sml.GetGPUPcieLinkInfo |
| metax_gpu_pcie_link_width_lanes |
GPU PCIe current link width. |
lanes |
gpu |
sml.GetGPUPcieLinkInfo |
| metax_gpu_pcie_receive_bytes_per_second |
GPU PCIe receive throughput. |
B/s |
gpu |
sml.GetGPUPcieThroughputInfo |
| metax_gpu_pcie_transmit_bytes_per_second |
GPU PCIe transmit throughput. |
B/s |
gpu |
sml.GetGPUPcieThroughputInfo |
| metax_gpu_metaxlink_link_speed_gt_per_second |
GPU MetaXLink current link speed. |
GT/s |
gpu, metaxlink |
sml.ListGPUMetaXLinkLinkInfos |
| metax_gpu_metaxlink_link_width_lanes |
GPU MetaXLink current link width. |
lanes |
gpu, metaxlink |
sml.ListGPUMetaXLinkLinkInfos |
| metax_gpu_metaxlink_receive_bytes_per_second |
GPU MetaXLink receive throughput. |
B/s |
gpu, metaxlink |
sml.ListGPUMetaXLinkThroughputInfos |
| metax_gpu_metaxlink_transmit_bytes_per_second |
GPU MetaXLink transmit throughput. |
B/s |
gpu, metaxlink |
sml.ListGPUMetaXLinkThroughputInfos |
| metax_gpu_metaxlink_receive_bytes_total |
GPU MetaXLink receive data size. |
bytes |
gpu, metaxlink |
sml.ListGPUMetaXLinkTrafficStatInfos |
| metax_gpu_metaxlink_transmit_bytes_total |
GPU MetaXLink transmit data size. |
bytes |
gpu, metaxlink |
sml.ListGPUMetaXLinkTrafficStatInfos |
| metax_gpu_metaxlink_aer_errors_total |
GPU MetaXLink AER errors count. |
count |
gpu, metaxlink, error_type |
sml.ListGPUMetaXLinkAerErrorsInfos |
| metax_gpu_status |
GPU status, 0 means normal, other values means abnormal. Check the documentation to see the exceptions corresponding to each value. |
- |
gpu, die |
sml.GetDieStatus |
| metax_gpu_temperature_celsius |
GPU temperature. |
°C |
gpu, die |
sml.GetDieTemperature |
| metax_gpu_utilization_percent |
GPU utilization, ranging from 0 to 100. |
% |
gpu, die, ip |
sml.GetDieUtilization |
| metax_gpu_memory_total_bytes |
Total vram. |
bytes |
gpu, die |
sml.GetDieMemoryInfo |
| metax_gpu_memory_used_bytes |
Used vram. |
bytes |
gpu, die |
sml.GetDieMemoryInfo |
| metax_gpu_clock_mhz |
GPU clock. |
MHz |
gpu, die, ip |
sml.ListDieClocks |
| metax_gpu_clocks_throttling |
Reason(s) for GPU clocks throttling. |
- |
gpu, die, reason |
sml.GetDieClocksThrottleStatus |
| metax_gpu_dpm_performance_level |
GPU DPM performance level. |
- |
gpu, die, ip |
sml.GetDieDPMPerformanceLevel |
| metax_gpu_ecc_memory_errors_total |
GPU ECC memory errors count. |
count |
gpu, die, memory_type, error_type |
sml.GetDieECCMemoryInfo |
| metax_gpu_ecc_memory_retired_pages_total |
GPU ECC memory retired pages count. |
count |
gpu, die |
sml.GetDieECCMemoryInfo |
MThreads GPU monitoring via the MTML (Moore Threads Management Library). The library is discovered automatically at startup using SONAME search (libmtml.so.2 then libmtml.so) through the system dynamic linker. Static device info is cached and only rebuilt on re-init; dynamic metrics are collected on every scrape.
Configuration: remove mthreads_gpu from BlackList to enable. Metric groups are controlled by [MetricCollector.Mthreads] toggles (EnableHealth, EnablePCIe, EnableMTLink).
| Metric |
Description |
Unit |
Labels |
Source |
| huatuo_bamai_mthreads_gpu_library_info |
MTML library info. |
- |
version |
mtml.LibraryVersion |
| huatuo_bamai_mthreads_gpu_device_info |
GPU info. |
- |
gpu, name, brand, serial |
mtml.Device.Name/Brand/SerialNumber |
| huatuo_bamai_mthreads_gpu_device_pci_info |
GPU PCI info. |
- |
gpu, sbdf |
mtml.Device.PciSbdf |
| huatuo_bamai_mthreads_gpu_device_spec |
GPU spec. |
- |
gpu, cores |
mtml.Device.GpuCores |
| huatuo_bamai_mthreads_gpu_device_bios_version |
GPU BIOS version. |
- |
gpu, bios |
mtml.Device.BiosVersion |
| huatuo_bamai_mthreads_gpu_device_musa_capability |
GPU MUSA compute capability. |
- |
gpu, musa_capability |
mtml.Device.MusaComputeCapability |
| huatuo_bamai_mthreads_gpu_memory_info |
GPU memory info. |
- |
gpu, type, vendor, bus_width |
mtml.Device.InitMemory |
| huatuo_bamai_mthreads_gpu_pcie_link_max_speed_gt_per_sec |
GPU PCIe max link speed in GT/s (hardware capability). |
GT/s |
gpu |
mtml.Device.PciInfo |
| huatuo_bamai_mthreads_gpu_pcie_link_max_width_lanes |
GPU PCIe max link width in lanes (hardware capability). |
lanes |
gpu |
mtml.Device.PciInfo |
| huatuo_bamai_mthreads_gpu_device_power_watts |
GPU device power in watts. |
W |
gpu |
mtml.Device.PowerUsage |
| huatuo_bamai_mthreads_gpu_gpu_temperature_celsius |
GPU temperature. |
°C |
gpu |
mtml.Gpu.Temperature |
| huatuo_bamai_mthreads_gpu_memory_temperature_celsius |
GPU memory temperature. |
°C |
gpu |
mtml.Memory.Temperature |
| huatuo_bamai_mthreads_gpu_gpu_utilization_percent |
GPU utilization (0-100). |
% |
gpu |
mtml.Gpu.Utilization |
| huatuo_bamai_mthreads_gpu_memory_utilization_percent |
GPU memory utilization (0-100). |
% |
gpu |
mtml.Memory.Utilization |
| huatuo_bamai_mthreads_gpu_memory_total_bytes |
Total GPU memory in bytes. |
bytes |
gpu |
mtml.Memory.Total |
| huatuo_bamai_mthreads_gpu_memory_used_bytes |
Used GPU memory in bytes. |
bytes |
gpu |
mtml.Memory.Used |
| huatuo_bamai_mthreads_gpu_gpu_clock_mhz |
GPU clock in MHz. |
MHz |
gpu |
mtml.Gpu.Clock |
| huatuo_bamai_mthreads_gpu_gpu_max_clock_mhz |
GPU max clock in MHz. |
MHz |
gpu |
mtml.Gpu.MaxClock |
| huatuo_bamai_mthreads_gpu_memory_clock_mhz |
GPU memory clock in MHz. |
MHz |
gpu |
mtml.Memory.Clock |
| huatuo_bamai_mthreads_gpu_memory_max_clock_mhz |
GPU memory max clock in MHz. |
MHz |
gpu |
mtml.Memory.MaxClock |
| huatuo_bamai_mthreads_gpu_gpu_voltage_volts |
GPU voltage in volts. |
V |
gpu |
mtml.Gpu.Voltage |
| huatuo_bamai_mthreads_gpu_gpu_power_limit_watts |
GPU enforced power limit in watts. |
W |
gpu |
mtml.Gpu.EnforcedPowerLimit |
| huatuo_bamai_mthreads_gpu_gpu_power_default_limit_watts |
GPU default power management limit in watts. |
W |
gpu |
mtml.Gpu.PowerManagementDefaultLimit |
| huatuo_bamai_mthreads_gpu_fan_rpm |
GPU fan speed in RPM. |
RPM |
gpu, fan |
mtml.Device.FanRpm |
| huatuo_bamai_mthreads_gpu_fan_speed_percent |
GPU fan speed percent. |
% |
gpu, fan |
mtml.Device.FanSpeed |
| huatuo_bamai_mthreads_gpu_gpu_pstate |
GPU performance state (0=P0). |
- |
gpu |
mtml.Device.PerformanceState |
| huatuo_bamai_mthreads_gpu_vpu_utilization_percent |
GPU VPU utilization (0-100). |
% |
gpu |
mtml.Vpu.Utilization |
| huatuo_bamai_mthreads_gpu_vpu_encoder_utilization_percent |
GPU VPU encoder utilization (0-100). |
% |
gpu |
mtml.Vpu.Utilization |
| huatuo_bamai_mthreads_gpu_vpu_decoder_utilization_percent |
GPU VPU decoder utilization (0-100). |
% |
gpu |
mtml.Vpu.Utilization |
| huatuo_bamai_mthreads_gpu_vpu_clock_mhz |
GPU VPU clock in MHz. |
MHz |
gpu |
mtml.Vpu.Clock |
| huatuo_bamai_mthreads_gpu_pcie_link_speed_gt_per_sec |
GPU PCIe current link speed in GT/s. |
GT/s |
gpu |
mtml.Device.PciInfo |
| huatuo_bamai_mthreads_gpu_pcie_link_width_lanes |
GPU PCIe current link width in lanes. |
lanes |
gpu |
mtml.Device.PciInfo |
| huatuo_bamai_mthreads_gpu_pcie_replay_total |
GPU PCIe replay counter. |
count |
gpu |
mtml.Device.PcieReplayCounter |
| huatuo_bamai_mthreads_gpu_mtlink_state |
GPU MtLink state (0=DOWN,1=UP,2=DOWNGRADE). |
- |
gpu, link |
mtml.Device.MtLinkState |
| huatuo_bamai_mthreads_gpu_mtlink_link_bandwidth_gb_s |
GPU MtLink per-link max bandwidth (device static spec, not live throughput). |
GB/s |
gpu |
mtml.Device.MtLinkSpec |
| huatuo_bamai_mthreads_gpu_mtlink_link_count |
GPU MtLink max number of supported links (device static spec). |
links |
gpu |
mtml.Device.MtLinkSpec |
5.2 - Instant Observability
🎯 About HUATUO
HUATUO is an operating system deep observability project open-sourced by DiDi and incubated under CCF (China Computer Federation). It focuses on providing OS kernel-level deep observability for cloud-native general computing, AI computing, cloud services, and infrastructure services.
📖 Overview
HUATUO uses eBPF technology to observe anomalous events in real time across core Linux kernel subsystems, including CPU scheduling, memory management, the network protocol stack, and hardware error reporting. When the kernel encounters anomalies such as softlockup, OOM, or hardware MCE errors, eBPF programs hook into kernel functions (kprobes) or kernel tracepoints, capturing process information, kernel call stacks, and network context at the moment the event occurs. The data is passed to user-space handlers via the perf event ring buffer and persisted to Elasticsearch or local disk files.
Compared to traditional kernel log (dmesg/syslog) collection, eBPF-based event observation reduces the risk of data loss from log buffer overflow; it can capture transient anomalies that never appear in kernel logs (such as excessive scheduler tick intervals); and it provides container-level event correlation for precise root-cause analysis in cloud-native environments.
Twelve event types are continuously observed, covering CPU scheduling health (sched_tick, softlockup, hungtask), memory pressure (memory_oom_kill, memory_reclaim_events), the network protocol stack (dropwatch, tcp_retransmit, net_rx_latency, netdev_events, netdev_bonding_lacp, netdev_txqueue_timeout), and hardware reliability (ras).
🎯 Use Cases
Kubernetes Container Memory Fault Diagnosis: In scenarios where containers frequently restart due to OOM, the memory_oom_kill event records both the process killed by the OOM Killer (victim) and the process that triggered the OOM (trigger), including their memcg cgroup pointers and container IDs. Combined with time-series data, this enables fast root-cause analysis of containers involved in memory contention, reducing the time spent manually reviewing container logs.
AI Training Cluster Hardware Fault Detection: On GPU training servers, the ras event continuously collects MCE (Machine Check Exception), EDAC memory controller errors, and PCIe AER (Advanced Error Reporting) errors, classifying them by severity (Corrected / UncorrectedRecoverable / UncorrectedFatal). This enables early detection of hardware aging or single-point failures before training jobs are interrupted, reducing training task losses caused by hardware faults.
Network Performance Jitter Analysis: dropwatch observes packet drops in the kernel network stack, tcp_retransmit observes TCP retransmission activity, and net_rx_latency detects end-to-end receive-path latency for individual packets from the network card driver to user space. Separate thresholds are configured per stage (driver to kernel: 5ms, kernel to TCP: 10ms, TCP to user space: 115ms), precisely identifying which network layer causes business timeouts.
Host Scheduling Health Observation: The sched_tick (scheduler tick interval, default threshold 10ms), softlockup (CPU unable to schedule, ~1 second), and hungtask (D-state process hang) events jointly cover anomalies along the CPU scheduling path. When system stalls or response timeouts occur, kernel call stacks and other diagnostic data are automatically preserved, supporting offline analysis after the fault clears.
🚀 Usage
Configuration
All events provide default values and are operational without any configuration. The following parameters can be tuned as needed:
| Parameter |
Default |
Description |
sched_tick.interval_threshold |
10000000 (10ms, nanoseconds) |
Scheduler tick interval threshold |
memory_reclaim.blocked_threshold |
900000000 (900ms, nanoseconds) |
Direct memory reclaim time trigger threshold |
net_rx_latency.driver2net_rx |
5 (ms) |
Latency threshold from NIC driver to __netif_receive_skb |
net_rx_latency.driver2tcp |
10 (ms) |
Latency threshold from NIC driver to tcp_v4_rcv |
net_rx_latency.driver2userspace |
115 (ms) |
Latency threshold from NIC driver to user-space copy (skb_copy_datagram_iovec) |
net_rx_latency.excluded_host_netnamespace |
true |
Whether to exclude the host network namespace (observe containers only by default) |
net_rx_latency.excluded_container_qos |
[] |
List of container QoS levels to exclude |
dropwatch.filter |
tcp |
tcpdump-style packet filter applied before dropwatch events are emitted |
dropwatch.max_events_per_second |
100 |
Maximum dropwatch events emitted per second; 0 disables rate limiting |
dropwatch.exclude_containers |
[] |
Reserved field; the current dropwatch event path does not apply it |
netdev.device_list |
[] |
List of network device names to monitor for link state changes |
ras.mce_thr_backoff |
1800 (seconds) |
MCE threshold interrupt (THR) event reporting cooldown to suppress interrupt storms |
issues_list |
[] |
Known-issue suppression rules; matched against net_rx_latency titles and dropwatch kernel call stacks |
Supported Events
| Event Name (tracer_name) |
Probe Type |
Trigger Condition |
Typical Scenarios |
sched_tick |
kprobe |
Scheduler tick interval >= threshold (default 10ms) |
System stalls, network latency, scheduling delays |
softlockup |
kprobe |
CPU unable to schedule for extended time (~1 second) |
Soft lockup, response anomalies |
hungtask |
kprobe |
D-state process task hang |
Transient mass D-state processes, IO blocking |
memory_oom_kill |
kprobe |
OOM Killer triggered |
Container/host memory exhaustion |
memory_reclaim_events |
kprobe |
Container process direct reclaim time > threshold (default 900ms) |
Business stalls caused by memory pressure |
ras |
tracepoint |
CPU/MEM/PCIe hardware errors |
Hardware fault detection |
dropwatch |
tracepoint |
Kernel network stack packet drop |
Business jitter caused by protocol stack drops |
tcp_retransmit |
tracepoint; optional kprobe for TLP |
TCP retransmission or Tail Loss Probe |
TCP loss, reordering, congestion, and latency diagnosis |
net_rx_latency |
kprobe |
Protocol stack receive latency exceeds per-stage threshold |
Business timeouts caused by receive latency |
netdev_events |
netlink |
NIC link state change |
Physical NIC link failures |
netdev_bonding_lacp |
kprobe |
LACP protocol state change (IEEE 802.3ad mode only) |
Fault boundary between physical machines and switches |
netdev_txqueue_timeout |
kprobe |
NIC transmit queue timeout |
NIC transmit queue hardware failure |
For tcp_retransmit usage, fields, classification, and drop correlation, refer to the tcpshark documentation.
Fields
All event records include the following common fields:
- hostname: Physical machine hostname
- region: Availability zone where the physical machine is located
- uploaded_timestamp: Data upload time
- container_id: Container ID if the event is associated with a container
- container_hostname: Container hostname if the event is associated with a container
- container_host_namespace: Kubernetes namespace of the container if the event is associated with a container
- container_type: Container type, e.g.,
normal for regular containers, sidecar for sidecar containers
- container_qos: Container QoS level
- tracer_name: Event name (e.g.,
sched_tick, memory_oom_kill)
- tracer_id: Tracing ID for this event
- observed_timestamp: Time when the tracing was triggered
- tracer_type: Observation kind; instant event records use
event
- tracer_data: Event-specific private data (see individual event descriptions below)
1. sched_tick
Description Measures the interval between scheduler ticks. When the interval reaches the threshold, it records the current kernel call stack and process information. The event can reveal long IRQ-off sections, CPU stalls, or virtualization scheduling delays, but does not by itself prove that softirqs were disabled. comm and pid identify the task interrupted by the reporting tick; they do not identify the cause of the delay.
Applicable Scenarios
- The kernel or a driver disables local interrupts for too long, or hardirq/NMI processing monopolizes the CPU.
- A VM vCPU is descheduled by the host, including high steal time and scheduling stalls.
- Low-level anomalies such as SMI or firmware stalls, delayed clockevent delivery, or lost timer events.
Usage Boundaries Normal tick suppression after a successful NO_HZ transition is excluded. Ordinary CPU load or a softirq backlog alone does not imply tick delay. Set the threshold above the target system’s normal tick period. The captured stack represents the first tick after the delay and should be correlated with IRQ, steal-time, and hardware metrics.
Data Storage Event data is automatically stored in Elasticsearch or as files on the physical machine disk.
Sample Data
{
    "uploaded_timestamp": "2025-06-11T16:05:16.251152703+08:00",
    "hostname": "***",
    "tracer_data": {
        "tick_interval_ns": 237328905,
        "tick_interval_threshold_ns": 10000000,
        "comm": "***-agent",
        "pid": 688073,
        "cpu": 1,
        "stack": "scheduler_tick/..."
    },
    "observed_timestamp": "2025-06-11T16:05:16.251+08:00",
    "tracer_type": "event",
    "region": "***",
    "tracer_name": "sched_tick"
}
Fields
- comm: Name of the process that triggered the event
- stack: Kernel call stack captured on the first scheduler tick after the delay
- tick_interval_ns: Total interval between adjacent scheduler ticks (nanoseconds)
- cpu: CPU number where the event occurred
- tick_interval_threshold_ns: Inclusive scheduler tick interval threshold (nanoseconds)
- pid: Process ID of the task interrupted by the reporting tick
2. dropwatch
Description Detects packet drop behavior in the kernel network protocol stack. Outputs the kernel call stack, network 5-tuple, and TCP state at the time of the drop. Optional call-stack filters can suppress locally validated noise patterns. The type field is reserved for TCP drop-type compatibility and is currently unset.
Data Storage Automatically stored in Elasticsearch or as files on the physical machine disk.
Sample Data
{
    "observed_timestamp": "2026-07-23T02:14:40.304775546Z",
    "tracer_data": {
        "drop_reason": "SKB_DROP_REASON_NOT_SPECIFIED",
        "source": "events",
        "comm": "kubelet",
        "pid": 1687046,
        "net_namespace_cookie": 123456789,
        "net_namespace_inum": 402653184,
        "netdev_queue_mapping": 3,
        "netdev_linkstatus": ["linkStatusUp"],
        "netdev_name": "eth0",
        "netdev_ifindex": 2,
        "packet_eth_proto": "0x0800",
        "packet_len_bytes": 1460,
        "layers": {
            "label": "IPv4/TCP",
            "ipv4": {
                "saddr": "10.79.68.62",
                "daddr": "10.134.72.4",
                "protocol": "TCP"
            },
            "tcp": {
                "sport": 8080,
                "dport": 49000,
                "seq": 1009085774,
                "ack_seq": 689410995,
                "sk_state": "ESTABLISHED"
            }
        },
        "stack": "kfree_skb/..."
    }
}
Fields
- type: Reserved drop type, currently unset and omitted from JSON; reserved codes are
1 (common drop), 2 (SYN flood), 3 (SYN queue overflow), and 4 (accept queue overflow)
- drop_reason: Kernel packet-drop reason
- source: Event source (
tools for standalone dropwatch or events when launched by huatuo-bamai)
- comm: Name of the process that triggered the packet drop
- pid: Process ID
- net_namespace_cookie / net_namespace_inum: Network namespace values used for container resolution
- netdev_queue_mapping: NIC queue index
- netdev_linkstatus: List of NIC link status flags
- netdev_name: Network device name
- netdev_ifindex: Network interface index
- packet_len_bytes: Packet length (bytes)
- layers.ipv4.saddr / layers.ipv4.daddr: Source and destination IP addresses
- layers.tcp.sport / layers.tcp.dport: Source and destination ports
- layers.tcp.seq / layers.tcp.ack_seq: TCP sequence and acknowledgment sequence numbers
- layers.tcp.sk_state: TCP connection state at the time of the drop
- stack: Kernel call stack at the time of the drop
3. net_rx_latency
Description Detects latency events on the protocol stack receive path (NIC driver → kernel protocol stack → user-space receive). Three observation points are set along the receive path; when the latency of any stage exceeds the corresponding threshold (defaults: driver to kernel 5ms, kernel to TCP 10ms, TCP to user space 115ms), the event is recorded with the network 5-tuple, TCP sequence number, latency stage, and latency duration. All TCP states are observed, not limited to ESTABLISHED—receive latency events in SYN, FIN, TIME_WAIT, and other non-ESTABLISHED states are also captured. The host network namespace is excluded by default, observing only container network traffic.
Data Storage Automatically stored in Elasticsearch or as files on the physical machine disk.
Sample Data
{
    "observed_timestamp": "2025-06-11T00:00:00Z",
    "tracer_data": {
        "comm": "nginx",
        "pid": 2921092,
        "latency_stage": "RX_STAGE_USERCOPY",
        "latency_ms": 95973,
        "latency_threshold_ms": 115,
        "tcp_state": "ESTABLISHED",
        "tcp_saddr": "10.156.248.76",
        "tcp_daddr": "10.134.72.4",
        "tcp_sport": 9213,
        "tcp_dport": 49000,
        "tcp_seq": 1009085774,
        "tcp_ack_seq": 689410995,
        "net_namespace_cookie": 123456789,
        "net_namespace_inum": 402653184,
        "packet_len_bytes": 26064
    }
}
Fields
- comm: Name of the process that triggered the event
- pid: Process ID that triggered the event
- latency_stage: Stage where latency occurred (
RX_STAGE_NETIF driver-to-kernel / RX_STAGE_TCPV4 kernel-to-TCP / RX_STAGE_USERCOPY TCP-to-user-space)
- latency_ms: Actual latency (milliseconds)
- latency_threshold_ms: Latency threshold that triggered the event (milliseconds)
- tcp_state: TCP connection state (all states are supported, e.g.,
ESTABLISHED, SYN_SENT, FIN_WAIT, TIME_WAIT)
- tcp_saddr / tcp_daddr: Source IP / Destination IP address
- tcp_sport / tcp_dport: Source port / Destination port
- tcp_seq / tcp_ack_seq: TCP sequence number / Acknowledgment sequence number
- net_namespace_cookie: Network namespace cookie (available on kernel ≥ 5.14, used for efficient container association)
- net_namespace_inum: Network namespace inum
- packet_len_bytes: Packet length (bytes)
4. memory_oom_kill
The OOM kill tracer is named memory_oom_kill (previously memory_oom, and earlier oom). Update blacklist entries, event filters, and alert queries. Its metric prefix is now huatuo_bamai_memory_oom_kill_, replacing huatuo_bamai_memory_oom_ and the earlier huatuo_bamai_oom_; update metric dashboards and recording rules too. Previously stored events keep their original names. Queries spanning these versions must match all three names; the bundled event dashboard does so.
Description Detects OOM (Out of Memory) events on the host or inside containers. Records information about the process killed by the OOM Killer (victim) and the process that triggered the OOM (trigger), along with the corresponding container and memory cgroup details, providing a complete fault snapshot. Host-level and per-container OOM count metrics are also maintained.
Data Storage Automatically stored in Elasticsearch or as files on the physical machine disk.
Sample Data
{
    "tracer_data": {
        "trigger_memcg_css": "0xff4b8d8be3818000",
        "trigger_container_id": "***",
        "trigger_container_hostname": "***.docker",
        "trigger_pid": 3218804,
        "trigger_process_name": "java",
        "victim_memcg_css": "0xff4b8d8be3818000",
        "victim_container_id": "***",
        "victim_container_hostname": "***.docker",
        "victim_pid": 3218745,
        "victim_process_name": "java",
        "cgroup_memory_limit": 2147483648,
        "cgroup_memory_usage": 2143289344,
        "memory_snapshot": {
            "top_processes": [
                {
                    "pid": 3218745,
                    "process_name": "java",
                    "vm_rss": 1604321280,
                    "rss_anon": 1509949440,
                    "rss_file": 83886080,
                    "rss_shmem": 0,
                    "vm_swap": 0,
                    "total": 1593835520
                }
            ],
            "host_meminfo": {
                "MemAvailable": 3355443200,
                "Cached": 1073741824,
                "Slab": 268435456
            },
            "victim_cgroup": {
                "container_id": "***",
                "cgroup_path": "kubepods.slice/...",
                "current": 2143289344,
                "max": 2147483648,
                "stat": {
                    "anon": 1509949440,
                    "file": 83886080
                },
                "events": {
                    "oom": 1,
                    "oom_kill": 1
                }
            }
        }
    }
}
Fields
- victim_process_name / victim_pid: Name and PID of the process killed by the OOM Killer
- victim_container_hostname / victim_container_id: Hostname and container ID where the killed process resided
- victim_memcg_css: Memory cgroup pointer (hex) of the killed process
- trigger_process_name / trigger_pid: Name and PID of the process that triggered OOM
- trigger_container_hostname / trigger_container_id: Hostname and container ID where the triggering process resided
- trigger_memcg_css: Memory cgroup pointer (hex) of the triggering process
- cgroup_memory_limit / cgroup_memory_usage: Memory limit and usage reported by the kernel event
- memory_snapshot.top_processes: Top processes by RSS/swap at the OOM moment, including
RssAnon, RssFile, RssShmem, VmRSS, and VmSwap
- memory_snapshot.host_meminfo: Key host
/proc/meminfo values, such as MemAvailable, Cached, Slab, swap, and anon/file activity
- memory_snapshot.trigger_cgroup / victim_cgroup: Trigger/victim container cgroup path, current/max memory,
memory.stat, and memory.events
5. softlockup
Description Detects softlockup events (CPU unable to be scheduled for an extended period, approximately 1 second). Provides information about the target process causing the lockup, the CPU where it occurred, and NMI backtrace information for all CPUs. A backoff strategy is applied: the reporting interval increases from 10 minutes up to a maximum of 3 hours during an event storm to prevent duplicate reports. A softlockup occurrence counter metric is also maintained.
Data Storage Automatically stored in Elasticsearch or as files on the physical machine disk.
Sample Data
{
    "tracer_data": {
        "cpu": 15,
        "pid": 12345,
        "comm": "kworker/15:0",
        "cpus_stack": "2025-06-10 14:30:22 sysrq: Show backtrace of all active CPUs\nNMI backtrace for cpu 15\n..."
    }
}
Fields
- cpu: CPU number where the softlockup occurred
- pid: PID of the process that triggered the softlockup
- comm: Name of the process that triggered the softlockup
- cpus_stack: NMI backtrace for all CPUs (multi-line text containing timestamps and call stacks)
6. hungtask
Description Detects hungtask events. Captures the kernel stacks of all processes in D state (uninterruptible sleep) and NMI backtrace for all CPUs to preserve the fault scene. A backoff strategy is applied: the reporting interval increases from 10 minutes up to a maximum of 3 hours during an event storm. A hungtask occurrence counter metric is also maintained. Note: some Linux distributions (e.g., Fedora 42) disable hungtask detection by default, in which case this observer will not start.
Data Storage Automatically stored in Elasticsearch or as files on the physical machine disk.
Sample Data
{
    "tracer_data": {
        "tid": 2567042,
        "comm": "kworker/u48:2",
        "cpus_stack": "2025-06-10 09:57:14 sysrq: Show backtrace of all active CPUs\nNMI backtrace for cpu 33\n...",
        "blocked_processes_stack": "task:java            state:D stack:    0 pid: 12345 ..."
    }
}
Fields
- tid: TID of the task that triggered hungtask detection
- comm: Name of the task that triggered hungtask detection
- cpus_stack: NMI backtrace for all CPUs (multi-line text containing timestamps and call stacks)
- blocked_processes_stack: Kernel stack information of D-state processes
7. memory_reclaim_events
Description Detects direct memory reclaim events for container processes. Triggered when the direct reclaim time of the same process within 1 second exceeds the configured threshold (default 900ms). Records the reclaim duration, process, and container information. Note: this observer only records events for container processes; host process events are filtered out.
Data Storage Automatically stored in Elasticsearch or as files on the physical machine disk.
Sample Data
{
    "tracer_data": {
        "pid": 1896137,
        "tid": 1896138,
        "comm": "java",
        "reclaim_duration_ns": 1412702917
    }
}
Fields
- comm: Name of the process that triggered direct memory reclaim
- pid: PID of the triggering process
- tid: TID of the triggering thread
- reclaim_duration_ns: Direct reclaim duration (nanoseconds)
8. ras
Description Detects hardware errors from CPU, memory, and PCIe subsystems via kernel tracepoints. Supports five hardware error sources: MCE (Machine Check Exception), EDAC (memory controller), ACPI/GHES (non-standard hardware errors), PCIe AER (Advanced Error Reporting), and MCE threshold interrupts (THR). Errors are classified by severity: Corrected, UncorrectedRecoverable, UncorrectedDeferred, and UncorrectedFatal. MCE threshold interrupt events use a cooldown period (default 30 minutes) to suppress interrupt storm-driven duplicate reports.
Data Storage Automatically stored in Elasticsearch or as files on the physical machine disk.
MCE Sample Data
{
    "tracer_data": {
        "dev": "CPU/MEM",
        "event": "MCE",
        "type": "UncorrectedRecoverable",
        "info": "{\"mcg_cpu_cap\":4096,\"banks_msr_status\":9295429630892703744,\"cpu\":2,\"socketid\":0,\"bank\":5}"
    }
}
PCIe AER Sample Data
{
    "observed_timestamp": "2025-06-11T00:00:00Z",
    "tracer_data": {
        "dev": "PCIe 0000:3b:00.0",
        "event": "AER",
        "type": "UncorrectedRecoverable",
        "info": "{\"dev_name\":\"0000:3b:00.0\",\"err_type\":\"UncorrectedRecoverable\",\"err_reason\":\"Completion Timeout\",\"tlp_header\":\"not available\"}"
    }
}
Fields
- dev: Hardware device where the error occurred (e.g.,
CPU/MEM, PCIe 0000:3b:00.0)
- event: Error type (
MCE / EDAC / NON_STANDARD / AER / MCE_THRESHOLD)
- type: Error severity (
Corrected / UncorrectedRecoverable / UncorrectedDeferred / UncorrectedFatal / Info)
- observed_timestamp: Top-level UTC userspace observation time;
kernel_observed_timestamp records UTC kernel observation time
- info: JSON-formatted detailed error information; content varies by event type
9. netdev_events
Description Detects NIC link state change events by subscribing to kernel netlink RTM_NEWLINK messages. Captures events including down/up transitions, MTU changes, AdminDown, and CarrierDown, along with interface name, link status, MAC address, and driver information. At startup, the observer scans the current state of all devices in device_list as a baseline; only state changes are reported thereafter.
Data Storage Automatically stored in Elasticsearch or as files on the physical machine disk.
Sample Data
{
    "tracer_data": {
        "ifname": "eth1",
        "index": 3,
        "linkstatus": "linkStatusAdminDown, linkStatusCarrierDown",
        "mac": "5c:6f:69:34:dc:72",
        "start": false,
        "driver": "ixgbe",
        "driver_version": "5.1.0-k",
        "firmware_version": "3.25 0x80000421 1.2163.0"
    }
}
Fields
- ifname: Network interface name (e.g.,
eth1)
- index: Interface index number
- linkstatus: Link state change description (may contain multiple states)
- mac: NIC MAC address
- start: Whether this is a baseline event scanned at startup (
true: startup scan, false: real-time change event)
- driver: NIC driver name
- driver_version: NIC driver version
- firmware_version: NIC firmware version
10. netdev_bonding_lacp
Description Detects LACP (Link Aggregation Control Protocol, IEEE 802.3ad) protocol state changes in bonding mode. Reads and records the complete status of all bonding interfaces under /proc/net/bonding/, including mode, MII status, Actor/Partner negotiation parameters, and slave link states. This observer is only activated automatically when an IEEE 802.3ad bonding interface is present on the system.
Data Storage Automatically stored in Elasticsearch or as files on the physical machine disk.
Sample Data
{
    "tracer_data": {
        "content": "/proc/net/bonding/bond0\nEthernet Channel Bonding Driver: v4.18.0...\nBonding Mode: IEEE 802.3ad Dynamic link aggregation\nMII Status: down\n..."
    }
}
Fields
- content: Complete bonding interface status information (multi-line text containing LACP negotiation details for all slaves, equivalent to the
/proc/net/bonding/bondX file content)
11. netdev_txqueue_timeout
Description Detects NIC transmit queue timeout (TX queue timeout) events. Records the queue index, device name, and driver name where the timeout occurred, used to identify hardware failures on the NIC transmit path.
Data Storage Automatically stored in Elasticsearch or as files on the physical machine disk.
Sample Data
{
    "tracer_data": {
        "queue_index": 3,
        "device_name": "eth0",
        "driver_name": "ixgbe"
    }
}
Fields
- queue_index: Index of the transmit queue where the timeout occurred
- device_name: Network device name
- driver_name: NIC driver name
⚙️ How It Works
Architecture
HUATUO’s anomalous event observation is built on eBPF technology. Event data is collected in kernel space with minimal performance overhead, and processed by user-space daemons for formatting, filtering, container association, and persistent storage.
graph TB
    subgraph "Linux Kernel"
        direction TB
        K1["kprobe hooks\n(sched_tick / softlockup / hungtask\n memory_oom_kill / memory_reclaim_events\n net_rx_latency / netdev_txqueue_timeout\n tcp_retransmit TLP, optional)"]
        K2["tracepoint hooks\n(ras: MCE / EDAC / AER / ACPI\n dropwatch: skb/kfree_skb\n tcp_retransmit:\n tcp/tcp_retransmit_skb /\n tcp/tcp_retransmit_synack)"]
        K3["netlink subscription\n(netdev_events: RTM_NEWLINK)"]
        K4["kprobe hooks\n(netdev_bonding_lacp: 802.3ad)"]
        PEB["Perf Event Ring Buffer\n(8192 pages)"]
    end

    subgraph "HUATUO User Space"
        direction TB
        EH["Go event handler goroutines\n(one per event type)"]
        CF["Filters\n(threshold / noise reduction / known-issue filtering)"]
        CM["Container association\n(CSS → ContainerID\n NetNS → ContainerID)"]
    end

    subgraph "Storage"
        ES["Elasticsearch"]
        DISK["Local disk files"]
    end

    K1 --> PEB
    K2 --> PEB
    K4 --> PEB
    PEB --> EH
    K3 --> EH
    EH --> CF
    CF --> CM
    CM --> ES
    CM --> DISK
Event Processing Flow
sequenceDiagram
    participant K as Linux Kernel
    participant B as eBPF Program
    participant P as Perf Event Buffer
    participant H as Go Event Handler
    participant F as Filter
    participant S as Storage

    K->>B: kprobe / tracepoint fires
    B->>B: Collect event context<br/>(process info / kernel stack / network context)
    B->>P: Write to perf event ring buffer
    H->>P: Read event data (blocking)
    H->>F: Format and apply filters<br/>(threshold / noise / known issues)
    F->>H: Events that passed filtering
    H->>H: Associate container information<br/>(CSS / NetNS mapping)
    H->>S: Persist to storage<br/>(Elasticsearch / local files)
5.3 - AutoTracing
🎯 About HUATUO
HUATUO is a deep OS observability project open-sourced by Didi and incubated under CCF (China Computer Federation). It provides OS kernel-level deep observability for cloud-native general-purpose computing, AI computing, cloud services, and foundational infrastructure.
📖 Overview
AutoTracing is an event-driven automatic diagnosis mechanism. When a host or container shows performance anomalies — such as CPU spikes, accumulation of D-state processes, saturated disk IO, or sudden memory allocation — the system triggers on-site data collection automatically based on preset thresholds, with no manual intervention required.
Collected artifacts include eBPF flame graphs (system-wide or container-scoped CPU call stack samples via perf), D-state process kernel call stacks, disk IO call stacks, and process memory usage rankings. Each event type has a built-in cooldown period (30 minutes by default) to prevent redundant data from continuous triggers.
Five event types are supported: cpusys (host CPU sys spike), cpuidle (container CPU usage spike), dload (container D-state load spike), iotracing (disk IO anomaly), and memburst (memory burst allocation).
🎯 Use Cases
CPU Hotspot Analysis for AI Training Jobs: In GPU training clusters, intermittent training stalls are often caused by sudden increases in kernel-mode CPU usage (cpusys). When sys utilization exceeds the threshold, AutoTracing immediately triggers a system-wide perf flame graph collection, persisting kernel call stack hotspots as structured flame graph data (flamedata) for offline analysis after the anomaly has passed.
Container CPU Jitter Analysis in Kubernetes: In microservice architectures, brief container CPU spikes (cpuidle) may cause response timeouts, but the issue often recovers before alert responders can act. When container CPU exceeds the threshold, AutoTracing triggers container-scoped perf sampling and generates a flame graph scoped to the container’s cgroup, identifying hotspot functions and reducing time spent on log-based investigation.
D-State Process Accumulation in Cloud-Native Environments: Under high IO load or storage jitter, containers may accumulate large numbers of D-state (uninterruptible sleep) processes, causing system stalls. The dload event applies an exponential weighted moving average (EMA) to the container’s uninterruptible process load. When the EMA exceeds the threshold, kernel call stacks are collected for all D-state processes inside the container and on the host, pinpointing the blocking root cause.
Disk IO Bottleneck Root Cause Analysis: In data-intensive or log-heavy workloads, saturated disk IO utilization or write bandwidth causes application request backlog. iotracing continuously polls /proc/diskstats and triggers when any IO metric exceeds its threshold for two consecutive samples. It then collects a list of high-IO processes (with per-process read/write byte counts and open file details) and kernel call stacks of processes waiting in IO scheduling, narrowing down the processes responsible for high disk IO consumption.
🚀 Usage
Configuration
All events provide default values and work without configuration:
| Parameter |
Default |
Description |
cpuidle.user_threshold |
75 (%) |
Container CPU user utilization trigger threshold |
cpuidle.sys_threshold |
45 (%) |
Container CPU sys utilization trigger threshold |
cpuidle.usage_threshold |
90 (%) |
Container total CPU utilization trigger threshold |
cpuidle.delta_user_threshold |
45 (%) |
Container CPU user utilization delta trigger threshold |
cpuidle.delta_sys_threshold |
20 (%) |
Container CPU sys utilization delta trigger threshold |
cpuidle.delta_usage_threshold |
55 (%) |
Container total CPU utilization delta trigger threshold |
cpuidle.interval |
10 (s) |
Detection interval |
cpuidle.interval_tracing |
1800 (s) |
Per-container cooldown period between triggers |
cpuidle.run_tracing_tool_timeout |
10 (s) |
perf flame graph collection timeout |
cpusys.sys_threshold |
45 (%) |
Host CPU sys utilization trigger threshold |
cpusys.delta_sys_threshold |
20 (%) |
Host CPU sys utilization delta trigger threshold |
cpusys.interval |
10 (s) |
Detection interval |
cpusys.interval_tracing |
1800 (s) |
Global cooldown period between triggers |
cpusys.run_tracing_tool_timeout |
10 (s) |
perf flame graph collection timeout |
dload.threshold_load |
5 |
Container D-state process load EMA trigger threshold |
dload.interval |
10 (s) |
Detection interval |
dload.interval_tracing |
1800 (s) |
Per-container cooldown period between triggers |
iotracing.rbps_threshold |
2000 (MB/s) |
Disk read throughput trigger threshold |
iotracing.wbps_threshold |
1500 (MB/s) |
Disk write throughput trigger threshold |
iotracing.util_threshold |
90 (%) |
Disk IO utilization trigger threshold |
iotracing.await_threshold |
100 (ms) |
Disk IO average wait time trigger threshold |
iotracing.run_tracing_tool_timeout |
10 (s) |
IO call stack collection timeout |
iotracing.max_proc_dump |
10 |
Maximum number of high-IO processes to collect |
iotracing.max_files_per_proc_dump |
5 |
Maximum open files to collect per process |
memburst.delta_memory_burst |
100 (%) |
Anonymous memory growth rate threshold relative to the oldest sample in the sliding window (100% means ≥ 2× triggers) |
memburst.delta_anon_threshold |
70 (%) |
Anonymous memory as a percentage of total host memory threshold |
memburst.interval |
10 (s) |
Detection interval |
memburst.interval_tracing |
1800 (s) |
Cooldown period between triggers |
memburst.sliding_window_length |
60 |
Sliding window sample count (corresponding to 600 seconds of history) |
memburst.dump_process_max_num |
10 |
Maximum number of top memory-consuming processes to collect |
Event List
| Event Name (tracer_name) |
Target |
Trigger Condition |
Typical Scenario |
cpusys |
Host |
sys > 45% and delta_sys > 20% |
Kernel-mode CPU spike, syscall hotspot |
cpuidle |
Container |
(user>75% and delta_user>45%) or (sys>45% and delta_sys>20%) or (total>90% and delta_total>55%) |
Container CPU spike, hotspot function analysis |
dload |
Container |
D-state process load EMA > 5 |
D-state process accumulation, IO blocking |
iotracing |
Host |
Any IO metric exceeds threshold for two consecutive samples |
Saturated disk IO, high IO wait latency |
memburst |
Host |
Anonymous memory ≥ 2× oldest window sample and ≥ 70% of total memory |
Memory burst allocation, OOM precursor |
Fields
All event records include the following common fields:
- hostname: Physical host hostname
- region: Availability zone of the physical host
- uploaded_timestamp: Data upload timestamp
- container_id: Container ID if the event is associated with a container
- container_hostname: Container hostname if the event is associated with a container
- container_host_namespace: Kubernetes namespace of the container
- container_type: Container type (e.g.,
normal, sidecar)
- container_qos: Container QoS level
- tracer_name: Event name (e.g.,
cpusys, memburst)
- tracer_id: Tracing session ID
- started_timestamp: Time when the tracing was triggered
- tracer_type: Observation kind; automatic tracing records use
autotracing
- tracer_data: Event-specific private data (see individual event descriptions below)
1. cpusys
Description Periodically reads /proc/stat to calculate host CPU sys utilization and the delta between consecutive samples. When sys utilization exceeds the threshold (default 45%) and the delta exceeds its threshold (default 20%), a system-wide perf sampling run is triggered to generate a full-host CPU flame graph. A 30-minute global cooldown prevents repeated triggers.
Storage Event data is automatically stored in Elasticsearch or a local disk file.
Sample Data
{
    "tracer_name": "cpusys",
    "tracer_data": {
        "system_percent": 52,
        "system_percent_threshold": 45,
        "system_percent_delta": 25,
        "system_percent_delta_threshold": 20,
        "flamedata": [
            {"level": 0, "value": 1000, "self": 0, "label": "all"},
            {"level": 1, "value": 350, "self": 350, "label": "do_syscall_64"}
        ]
    }
}
Field Descriptions
- system_percent: Host CPU sys utilization at trigger time (%)
- system_percent_threshold: sys utilization trigger threshold (%)
- system_percent_delta: sys utilization delta between consecutive samples (%)
- system_percent_delta_threshold: sys delta trigger threshold (%)
- flamedata: Flame graph frame data from perf sampling. Each frame contains:
- level: Call stack depth level
- value: Sample count for this frame including descendant frames
- self: Sample count for this frame excluding descendant frames
- label: Function or process name label
2. cpuidle
Description Periodically reads container cgroup CPU statistics to calculate container CPU user, sys, and total utilization along with their inter-sample deltas. A trigger fires if any of the following conditions holds: (user>75% and delta_user>45%), or (sys>45% and delta_sys>20%), or (total>90% and delta_total>55%). Container-scoped perf sampling is then run to generate a flame graph. A 30-minute per-container cooldown prevents repeated triggers. Specific containers can be excluded via the filter configuration.
Storage Event data is automatically stored in Elasticsearch or a local disk file.
Sample Data
{
    "tracer_name": "cpuidle",
    "tracer_data": {
        "user_percent": 80,
        "user_percent_threshold": 75,
        "user_percent_delta": 48,
        "user_percent_delta_threshold": 45,
        "system_percent": 12,
        "system_percent_threshold": 45,
        "system_percent_delta": 5,
        "system_percent_delta_threshold": 20,
        "total_percent": 92,
        "total_percent_threshold": 90,
        "total_percent_delta": 53,
        "total_percent_delta_threshold": 55,
        "flamedata": [
            {"level": 0, "value": 1000, "self": 0, "label": "all"},
            {"level": 1, "value": 800, "self": 800, "label": "java/com.example.App.main"}
        ]
    }
}
Field Descriptions
- user_percent / user_percent_threshold: Container CPU user utilization at trigger time (%) and its threshold
- user_percent_delta / user_percent_delta_threshold: User utilization inter-sample delta (%) and its threshold
- system_percent / system_percent_threshold: Container CPU system utilization at trigger time (%) and its threshold
- system_percent_delta / system_percent_delta_threshold: System utilization inter-sample delta (%) and its threshold
- total_percent / total_percent_threshold: Container total CPU utilization at trigger time (%) and its threshold
- total_percent_delta / total_percent_delta_threshold: Total utilization inter-sample delta (%) and its threshold
- flamedata: Container-scoped perf flame graph frame data; field meanings same as
cpusys
3. dload
Description Reads container process states via netlink and cgroup, then computes an exponential weighted moving average (EMA) of the load contribution from uninterruptible (D-state) processes per container. When the EMA exceeds the threshold (default 5), kernel call stacks are collected for all D-state processes inside the container and on the host. Known-issue filtering (issues_list) reduces false positives. A 30-minute per-container cooldown applies.
Storage Event data is automatically stored in Elasticsearch or a local disk file.
Sample Data
{
    "tracer_name": "dload",
    "tracer_data": {
        "threshold": 5,
        "nr_sleeping": 120,
        "nr_running": 4,
        "nr_stopped": 0,
        "nr_uninterruptible": 8,
        "nr_iowait": 3,
        "load_avg": 7.23,
        "dload_avg": 6.81,
        "known_issue": "",
        "stack": "task:java            state:D stack:    0 pid: 12345 tgid: 12345 ...\n  io_schedule+0x18/0x40\n  ext4_file_write_iter+0x..."
    }
}
Field Descriptions
- threshold: D-state load EMA trigger threshold
- nr_sleeping: Number of sleeping processes in the container
- nr_running: Number of running processes in the container
- nr_stopped: Number of stopped processes in the container
- nr_uninterruptible: Number of uninterruptible (D-state) processes in the container
- nr_iowait: Number of IO-waiting processes in the container
- load_avg: Container load average at trigger time
- dload_avg: Container D-state load EMA value at trigger time
- known_issue: Matched known issue description (empty if none matched)
- stack: Kernel call stacks of D-state processes (multi-process, multi-line text)
4. iotracing
Description Polls /proc/diskstats at 5-second intervals to calculate per-disk read/write throughput, IO utilization, and IO wait time. md devices are excluded automatically. A trigger fires when any metric exceeds its threshold for two consecutive samples. On trigger, the system collects a list of high-IO processes (with per-process read/write byte counts and open file details) and kernel call stacks of processes waiting in IO scheduling.
Storage Event data is automatically stored in Elasticsearch or a local disk file.
Sample Data
{
    "tracer_name": "iotracing",
    "tracer_data": {
        "reason_snapshot": {
            "type": "ioutil",
            "device": "sda",
            "iostatus": {
                "read_bps": 120,
                "read_iops": 450,
                "read_await": 12,
                "write_bps": 2100,
                "write_iops": 890,
                "write_await": 145,
                "io_util": 95,
                "queue_size": 32
            }
        },
        "process_io_data": [
            {
                "pid": 12345,
                "comm": "java",
                "container_hostname": "app-pod-xxx",
                "fs_read": 0,
                "fs_write": 52428800,
                "disk_read": 0,
                "disk_write": 49152000,
                "file_stat": ["/data/logs/app.log"],
                "file_count": 1
            }
        ],
        "timeout_io_stack": [
            {
                "pid": 12345,
                "comm": "java",
                "container_hostname": "app-pod-xxx",
                "latency_us": 250000,
                "stack": {
                    "back_trace": [
                        "io_schedule+0x18/0x40",
                        "ext4_file_write_iter+0x2a0/0x4c0"
                    ]
                }
            }
        ]
    }
}
Field Descriptions
- reason_snapshot: Snapshot of the condition that triggered IO collection
- type: Trigger type (
ioutil IO utilization / read_bps read throughput / write_bps write throughput / read_await read wait time / write_await write wait time)
- device: Name of the disk device that exceeded the threshold
- iostatus: Disk IO metric snapshot at trigger time (
read_bps/write_bps in MB/s, read_await/write_await in ms, io_util in %, queue_size is queue depth)
- process_io_data: List of high-IO processes. Each record contains:
- pid / comm: Process PID and name
- container_hostname: Container hostname of the process (empty for host processes)
- fs_read / fs_write: Bytes read/written at the filesystem layer
- disk_read / disk_write: Bytes actually read/written at the disk layer
- file_stat: List of file paths currently open by the process
- file_count: Total number of files open by the process
- timeout_io_stack: Call stacks of processes waiting in IO scheduling. Each record contains:
- pid / comm: Process PID and name
- container_hostname: Container hostname of the process
- latency_us: IO wait duration (microseconds)
- stack.back_trace: List of kernel call stack frames
5. memburst
Description Periodically samples host anonymous memory usage and maintains a sliding window of 60 samples (corresponding to 600 seconds). A trigger fires when current anonymous memory is ≥ 2× the oldest sample in the window and anonymous memory accounts for ≥ 70% of total host memory. On trigger, the top N processes by memory consumption (default 10) are collected, recording their PID, process name, and RSS memory size. A 30-minute cooldown applies.
Storage Event data is automatically stored in Elasticsearch or a local disk file.
Sample Data
{
    "tracer_name": "memburst",
    "tracer_data": {
        "top_memory_usage": [
            {
                "pid": 3456,
                "process_name": "java",
                "memory_size": 8589934592
            },
            {
                "pid": 3789,
                "process_name": "python3",
                "memory_size": 2147483648
            }
        ]
    }
}
Field Descriptions
- top_memory_usage: List of top memory-consuming processes sorted by RSS in descending order. Each record contains:
- pid: Process PID
- process_name: Process name
- memory_size: Process RSS memory usage (bytes)
⚙️ Principle
Architecture
AutoTracing is built on periodic polling, combined with eBPF call stack collection and perf flame graph generation, to collect anomaly diagnostic data at the kernel level with low overhead.
graph TB
    subgraph "Data Sources"
        P1["/proc/stat\n(Host CPU utilization)"]
        P2["cgroup CPU stats\n(Container CPU utilization)"]
        P3["netlink / cgroup\n(Container process states / load average)"]
        P4["/proc/diskstats\n(Disk IO metrics)"]
        P5["/proc/meminfo\n+ cgroup memory stats"]
    end

    subgraph "HUATUO AutoTracing"
        DT["Threshold Detection\n(sliding window / EMA / two consecutive breaches)"]
        BO["Cooldown\n(30-minute backoff)"]
        PERF["perf Flame Graph\n(system-wide / container-scoped)"]
        BPF["eBPF kprobe\n(IO scheduling latency tracing)"]
        CM["Container Correlation\n(cgroup → ContainerID)"]
    end

    subgraph "Storage"
        ES["Elasticsearch"]
        DISK["Local Disk File"]
    end

    P1 --> DT
    P2 --> DT
    P3 --> DT
    P4 --> DT
    P5 --> DT
    DT --> BO
    BO --> PERF
    BO --> BPF
    PERF --> CM
    BPF --> CM
    CM --> ES
    CM --> DISK
Event Processing Flow
sequenceDiagram
    participant M as Periodic Metric Collection
    participant D as Threshold Detector
    participant B as Cooldown (backoff)
    participant C as On-site Data Collector
    participant S as Storage

    M->>D: Push metrics (every 10s)
    D->>D: Evaluate threshold (sliding window / EMA / consecutive)
    alt Threshold exceeded
        D->>B: Check cooldown state
        alt Trigger allowed
            B->>C: Trigger collection<br/>(perf flame graph / D-state stacks / IO process list)
            C->>C: Correlate container info (cgroup → ContainerID)
            C->>S: Persist data (Elasticsearch / local file)
        else In cooldown
            B-->>D: Skip this trigger
        end
    end
5.4 - Continuous Profiling
🎯 About HUATUO
HUATUO is an operating-system observability project open sourced by DiDi and incubated by the China Computer Federation (CCF). It is used in AI computing, AI sandboxes, cloud-native general-purpose computing, cloud services, and infrastructure services.
🚀 Quick Start
This guide uses build/docker/docker-compose.yml to start all services, create a host CPU profiling job, and view the flame graph in Grafana.
1. Start Services
First, configure Elasticsearch credentials so that huatuo-bamai and huatuo-apiserver can persist profile data. The config files are volume-mounted into the containers, so edit them directly in the project root.
In huatuo-bamai.conf:
[HTTPServer.Auth]
    BearerToken = "REPLACE_WITH_NODE_TOKEN"

[Storage]
    [Storage.Elasticsearch]
        Address = "http://127.0.0.1:9200"
        Index = "huatuo_bamai"
        Username = "elastic"
        Password = "huatuo-bamai"
In huatuo-apiserver.conf:
[Agent.Auth]
    BearerToken = "REPLACE_WITH_NODE_TOKEN"

[Elasticsearch]
    Address = "http://127.0.0.1:9200"
    Username = "elastic"
    Password = "huatuo-bamai"
    Index = "huatuo_bamai"

[Auth]
    [[Auth.Users]]
        ID = "administrator"
        BearerToken = "REPLACE_WITH_RANDOM_HEX"
        Admin = true
Then start all services from the project root:
docker compose --project-directory ./build/docker up
Run without -d to observe startup logs. Add -d for background mode.
| Service |
Role |
Default Port |
huatuo-bamai |
Agent, runs profiler sampling |
19704 |
huatuo-apiserver |
API entry point, creates and dispatches jobs |
12740 |
elasticsearch |
Stores profile data (index: huatuo_bamai) |
9200 |
grafana |
Flame graph visualization |
3000 |
2. Verify Services
In a new terminal, confirm all services are ready:
# Agent health check
$ curl -s http://localhost:19704/version | jq .data.name

"huatuo-bamai"

# API Server health check
$ curl -s http://localhost:12740/version | jq .data.name

"huatuo-apiserver"

# ES index status
$ curl -s -u elastic:huatuo-bamai "http://localhost:9200/_cat/indices/huatuo_bamai?v"

health status index        uuid                   pri rep docs.count docs.deleted store.size pri.store.size dataset.size
yellow open   huatuo_bamai 147fzHJhQ820GjCKFLh5ZQ   1   1         42            0    297.8kb        297.8kb      297.8kb
Set environment variables for subsequent API calls:
API_BASE="http://127.0.0.1:12740"
API_TOKEN="REPLACE_WITH_RANDOM_HEX"
3. Create a Host CPU Profiling Job
Use c language (native, covers C/C++/Go) to sample the entire host for 30 seconds:
# Use the actual hostname of the node
HOSTNAME=$(hostname)

JOB_ID=$(curl -s -X POST \
  -H "Authorization: Bearer ${API_TOKEN}" \
  -H "Content-Type: application/json" \
  -d "{
    \"type\": \"cpu\",
    \"language\": \"c\",
    \"mode\": \"oncpu\",
    \"scope\": \"host\",
    \"duration_seconds\": 30,
    \"hostname\": \"${HOSTNAME}\"
  }" \
  "${API_BASE}/v1/profiling" | jq -r .data.request_id)

echo "Job ID: $JOB_ID"
4. Verify Data in Elasticsearch
Each aggregation window is 10 seconds. A 30-second job produces approximately 3 profile documents. Wait for completion, then verify:
$ curl -s -u elastic:huatuo-bamai "http://localhost:9200/huatuo_bamai/_count" \
  -H "Content-Type: application/json" \
  -d '{"query":{"exists":{"field":"profile_data.profile"}}}' | jq .count

3
5. View the Flame Graph in Grafana
Open the Continuous Profiling (host) dashboard:
Steps:
- Select a time range covering the profiling period
- Choose your
hostname and set type to process_cpu:cpu:nanoseconds:cpu:nanoseconds
- The flame graph loads aggregated call stacks for the selected time range and updates dynamically
- Click a frame to zoom in; use the top table for symbol sorting, filtering, and statistics
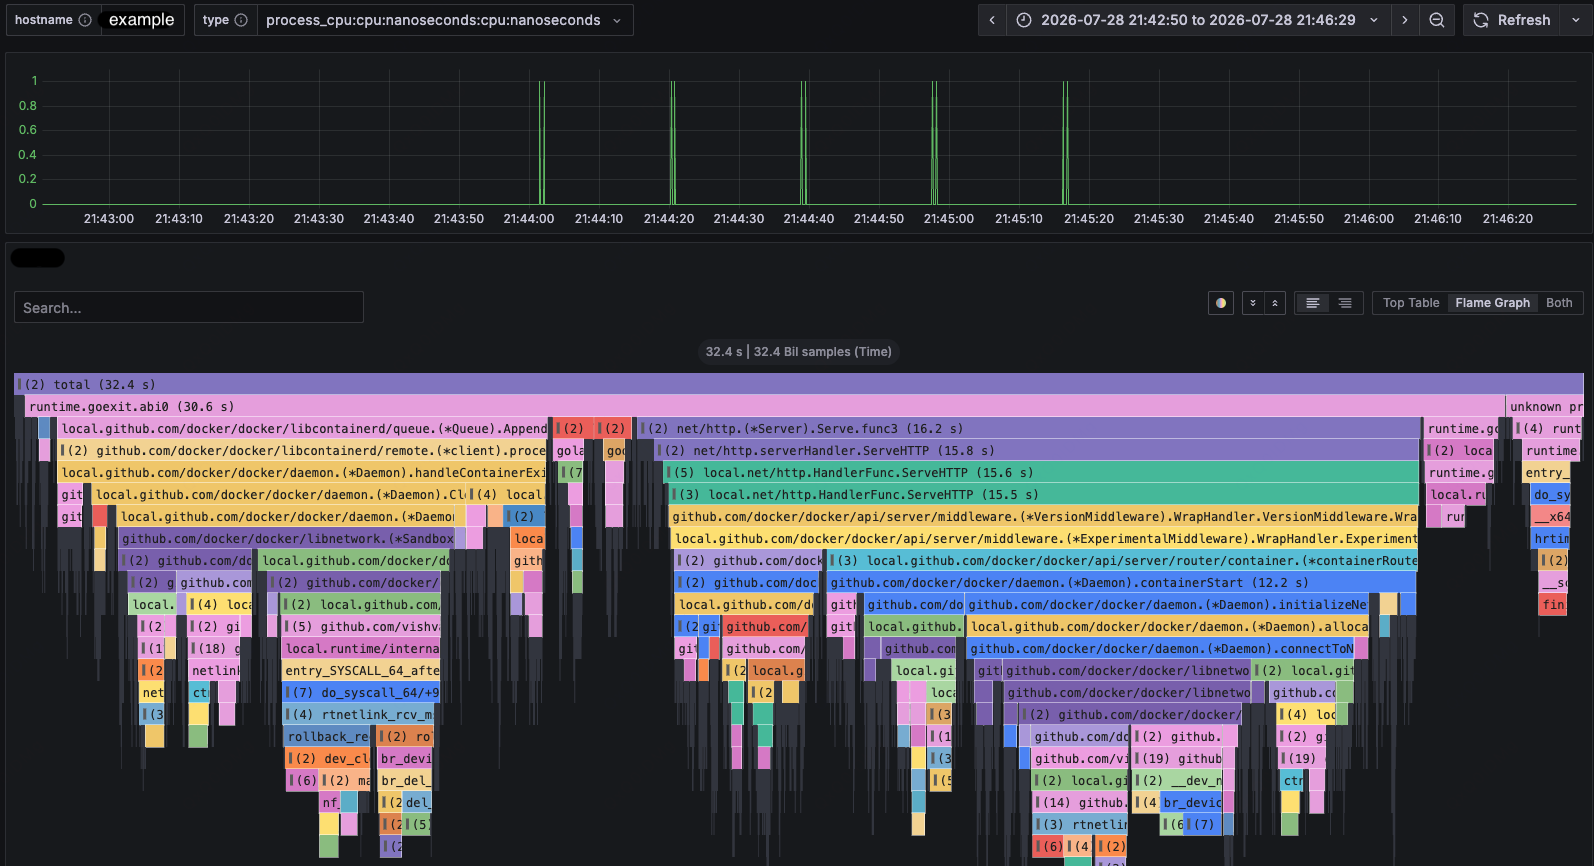
For more profiling dimensions, see the Profiling API section below.
🌐 Profiling API
huatuo-apiserver exposes /v1/profiling for creating, observing, and stopping
Profiling Jobs. Each create request is an independent execution. The Job is
durable in huatuo-apiserver while the Node owns only the in-memory Operation
and profiler process.
Elasticsearch is optional for Job control but required for raw results and
Dashboard links. Node and Apiserver must use the same Elasticsearch index.
1. Request Conventions
By default, huatuo-apiserver listens on :12740. The following examples use environment variables for the server address and bearer token:
API_BASE="http://127.0.0.1:12740"
API_TOKEN="REPLACE_WITH_RANDOM_HEX"
Every request must pass the configured bearer token:
Authorization: Bearer REPLACE_WITH_RANDOM_HEX
A non-administrator user requires both /v1/profiling and
/v1/profiling/** permissions. Permissions may include an HTTP method, such as
GET /v1/profiling/**. Successful responses contain only data:
Error responses contain a stable code and a human-readable message:
{
  "error": {
    "code": "result_unavailable",
    "message": "Job state does not provide a complete Profiling result"
  }
}
Clients must branch on error.code and must not parse error.message.
2. Query Profiling Capabilities
Before creating a job, query the profiling types, languages, CPU modes, memory modes, and runtime settings supported by the server:
curl -sS \
  -H "Authorization: Bearer ${API_TOKEN}" \
  "${API_BASE}/v1/profiling/capabilities"
data.items is a static versioned capability table. Each item contains:
| Field |
Description |
type |
Profiling type: cpu or memory |
language |
Target language |
modes |
Valid mode values for this type/language pair |
supports_binary_match |
Whether binary_match_path is accepted |
supported_scopes |
Valid values for scope |
CPU profiling supports oncpu and offcpu for c, c++, and go;
java and python support only oncpu. Memory profiling supports these combinations:
| Language |
mode |
Description |
c, c++, go |
virtual_alloc |
Virtual address-space allocation |
c, c++, go |
physical_alloc |
Physical page allocation |
c, c++, go |
physical_usage |
Current physical page residency |
java |
object_alloc |
JVM object allocation |
java |
object_usage |
JVM live objects |
3. Create a Profiling Job
POST /v1/profiling accepts the following JSON fields:
| Field |
Required |
Description |
type |
Yes |
Profiling type: cpu or memory |
language |
Yes |
Target process language; it must support the selected profiling type |
mode |
Yes |
One mode advertised for the selected type/language pair |
duration_seconds |
Yes |
Profiling duration in seconds |
hostname |
Yes |
Hostname of the node running the target process; used for job scheduling |
scope |
Yes |
host or container, as advertised by capabilities |
container_id |
For container scope |
Target container ID |
binary_match_path |
No |
Executable path matcher when the capability permits it |
Each request creates a new Job, even when its content matches an earlier request.
Per-host and process-wide quotas reject excess active Jobs with HTTP 429.
Create a Go CPU profiling job on a host:
curl -sS -i \
  -X POST \
  -H "Authorization: Bearer ${API_TOKEN}" \
  -H "Content-Type: application/json" \
  -d '{
    "type": "cpu",
    "language": "go",
    "mode": "oncpu",
    "scope": "host",
    "duration_seconds": 60,
    "hostname": "node-01"
  }' \
  "${API_BASE}/v1/profiling"
Create a Java live-object profiling job in a container:
curl -sS -i \
  -X POST \
  -H "Authorization: Bearer ${API_TOKEN}" \
  -H "Content-Type: application/json" \
  -d '{
    "type": "memory",
    "language": "java",
    "mode": "object_usage",
    "scope": "container",
    "duration_seconds": 60,
    "container_id": "9f4c2f1a8b7d",
    "hostname": "node-01"
  }' \
  "${API_BASE}/v1/profiling"
A successful request returns 201 Created. The Location response header identifies the new job, and the response body contains the job ID used by subsequent requests:
{
  "data": {
    "request_id": "<profile-job-id>",
    "hostname": "node-01",
    "duration_seconds": 60,
    "scope": "host",
    "type": "cpu",
    "language": "go",
    "mode": "oncpu",
    "status": "pending",
    "created_at": "2026-08-24T10:00:00Z",
    "updated_at": "2026-08-24T10:00:00Z"
  }
}
JOB_ID="<profile-job-id>"
4. List Profiling Jobs
GET /v1/profiling supports these query parameters:
| Parameter |
Default |
Description |
limit |
100 |
Page size; must be between 1 and 1000 |
offset |
0 |
Starting offset; must be greater than or equal to 0 |
List the 20 most recent Profiling Jobs:
curl -sS -G \
  -H "Authorization: Bearer ${API_TOKEN}" \
  --data-urlencode "limit=20" \
  --data-urlencode "offset=0" \
  "${API_BASE}/v1/profiling"
The server always limits the result to Profiling Jobs and orders them by
created_at descending. data.items contains the job array. data.limit and
data.offset are the effective pagination parameters, and data.has_more
indicates whether another page is available. Non-administrator users can list
only jobs they created.
5. Get a Profiling Job
curl -sS \
  -H "Authorization: Bearer ${API_TOKEN}" \
  "${API_BASE}/v1/profiling/${JOB_ID}"
The data object contains the job details:
| Field |
Description |
request_id |
Profiling Job ID used by all follow-up requests |
container_id |
Target container ID; omitted for host jobs |
hostname |
Target node hostname |
duration_seconds |
Requested profiling duration in seconds |
scope |
host or container |
type |
cpu or memory |
language |
Target process language |
mode |
Profiling mode selected from the capability table |
binary_match_path |
Executable path matcher; omitted when unused |
status |
Current job status |
terminal |
Terminal details {outcome, reason, message}; omitted while active |
created_at |
Job creation time |
updated_at |
Last Job state update time |
started_at |
Time execution started; omitted until observed running |
ended_at |
Terminal status time; omitted while the job is active |
result_url |
Dashboard URL returned by the detail endpoint when a complete result is available |
Profiling jobs use these statuses:
| Status |
Description |
pending |
The job has been created and is waiting for the Agent |
running |
The Agent is collecting profiling data |
stopping |
A stop request has been persisted and is being applied asynchronously |
terminal |
The job has ended; inspect terminal.outcome for the result |
terminal.outcome is completed, failed, stopped, or unknown. For
failed, inspect terminal.reason and terminal.message. stopped means the
job was actively stopped and its result may be incomplete. unknown means the
Apiserver cannot verify the final Operation status, but a durably published
result may still be available.
operation_lost and execution_timed_out are terminal reason codes, not Job
statuses. Other failure codes include pending or stop deadline expiry, Node
unavailability, execution-capacity exhaustion, start or execution failure,
invalid_node_request for a Node request constructed incorrectly by the
Apiserver, and protocol errors.
6. Get Raw Profiling Data
GET /v1/profiling/:request_id/raw returns raw profiling windows only for a
Job whose terminal.outcome is completed or unknown and whose durable
publication marker exists. A missing or expired marker returns
result_not_found. Active Jobs return result_not_ready; failed and
stopped Jobs return
result_unavailable.
The response can be large, so it can be written directly to a file:
curl -sS \
  -H "Authorization: Bearer ${API_TOKEN}" \
  -o profile-raw.json \
  "${API_BASE}/v1/profiling/${JOB_ID}/raw?limit=100&offset=0"
The profiling windows are in data.items; data.limit, data.offset, and
data.has_more describe the page. Each item contains uploaded_timestamp,
started_timestamp, profile_type, and the pprof-compatible profile payload.
An empty, durably published result is a successful response with an empty
items array. limit defaults to 20 and accepts 1–100. Explicit limit=0
returns a parameter error; omitted limits use the default. If the encoded
profile data exceeds 64 MiB, the server returns 413 result_too_large; retry
with a smaller limit.
Flamegraph queries consume matching windows in batches of 100 and merge them
incrementally, up to 100000 windows per request. A one-hour profile with one
window per second therefore includes all 3600 windows. More than 100000 windows
returns an error asking for a narrower range or filters. Query or merge errors
never return a partial flamegraph. Raw Profile pages remain scoped to a Job;
their page limit does not cap the full flamegraph query.
7. Stop a Profiling Job
Stop is an asynchronous intent. It is accepted for pending, running, or
already stopping Jobs:
curl -sS \
  -X POST \
  -H "Authorization: Bearer ${API_TOKEN}" \
  "${API_BASE}/v1/profiling/${JOB_ID}/stop"
A successful request returns 200 OK with the current Job snapshot. A terminal
Job returns 409 Conflict. Stopped Jobs do not expose results because their
final data may be incomplete.
📖 profiler CLI Overview
profiler is HUATUO’s standalone performance profiling CLI. It samples host processes or processes inside containers without requiring huatuo-apiserver, Elasticsearch, or Grafana. The tool supports C, C++, Go, Java, and Python processes and writes call stacks as folded stacks or SVG flame graphs.
C, C++, and Go use the eBPF-based native collector to observe on-CPU usage, off-CPU blocking and scheduling delay, virtual memory allocation, physical memory allocation, and physical memory residency. Java uses async-profiler to observe CPU usage, object allocation, and live objects. Python uses py-spy to observe CPU usage. The results can be used to locate hot functions, attribute memory growth, analyze processes inside containers, and preserve performance data for later diagnosis.
The remainder of this section covers standalone use of _output/bin/profiler. For service-based continuous profiling, see the Profiling API section above.
🎯 Use Cases
1. Locate CPU Hotspots and Call Paths
Sample the call stacks of C, C++, Go, Java, or Python processes at a fixed frequency and use stack width to identify the primary consumers of CPU time. The native collector can also limit sampling to selected CPUs with --cpuid, which is useful for analyzing CPU-pinned workloads or per-CPU hotspots.
2. Attribute Native Process Memory
Observe virtual address-space allocation, physical page allocation, and current physical page residency for C, C++, and Go processes. These modes distinguish between how much address space was requested, how much physical memory was allocated, and how much physical memory remains resident. They help locate call paths responsible for mmap activity, page-fault allocation, and resident memory growth.
3. Analyze JVM Object Allocation and Live Objects
Use async-profiler to collect Java object allocation or live-object call stacks. Object allocation profiles help locate high allocation rates and sources of GC pressure. Live-object profiles help identify objects that remain referenced during the collection window and the paths where they were allocated.
4. Analyze Containers and Multi-process Workloads
Use a container ID to resolve and profile target processes inside Docker or containerd workloads. Java and Python also accept comma-separated PID lists and can limit the number of concurrently running collector subprocesses, which is useful for service replicas and parent-child process groups.
🚀 Usage
1. Build and Runtime Requirements
Build all artifacts from the repository root:
The resulting executable is _output/bin/profiler. Native profiling depends on Linux eBPF, perf events, and the BPF objects built from this repository. It generally requires root privileges and a kernel.perf_event_paranoid setting that permits sampling. Java profiling requires async-profiler; --tool-path points to the shared tool root containing bin/asprof and lib/libasyncProfiler.so. Python profiling requires py-spy under the same root.
Display the complete help for the current version:
_output/bin/profiler --help
The basic command structure is:
sudo _output/bin/profiler \
  --type <cpu|memory> \
  --language <c|c++|go|java|python> \
  --pid <pid> \
  --duration 30 \
  --aggr-interval 10 \
  --output-format flamegraph \
  --output-path ./profiles
--type and --language are required. Java, Python, and native memory profiling require exactly one target specified with either --pid or --container-id. Native CPU profiling can sample the entire host when neither target is specified.
2. General CLI Options
| Option |
Default |
Scope |
Description |
--type, -t |
None |
All |
Profile type: cpu or memory; required |
--language, -l |
None |
All |
Target language: c, c++, go, java, or python; required |
--pid, -p |
None |
All |
Target PID; Java and Python accept comma-separated PIDs, while native profiling accepts at most one PID |
--container-id |
None |
All |
Target container ID; mutually exclusive with --pid |
--duration, -d |
10 |
All |
Total profiling duration in seconds; minimum 1 |
--aggr-interval |
10 |
All |
Aggregation interval in seconds; must not exceed the duration |
--freq, -F |
99 |
CPU |
Samples collected per second; maximum 1000 for Java |
--output-path |
. |
Local output |
Output directory, not an output file name |
--output-format |
collapsed |
All |
collapsed, flamegraph, svg, or remote |
--output-storage |
/var/run/huatuo-toolstream.sock |
remote |
Unix socket used for remote upload |
--max-concurrent-procs |
0 |
Java, Python |
Maximum concurrent collector subprocesses; 0 means unlimited |
--tool-path |
None |
Java, Python |
Shared external tool root; required |
--binary-match-path |
None |
Java, Python |
Executable path used to match target processes |
--huatuo-api-address |
127.0.0.1:19704 |
Container targets |
HUATUO API address used to resolve container metadata |
--tracer-id |
Empty; generated internally for local output |
All; required for remote |
Stable profiling task ID used by toolstream and remote storage |
--enable-pprof |
false |
Profiler itself |
Expose Go pprof endpoints for the profiler process on :6000 |
--version-format |
text |
Version query |
Output format for --version: text, json, or short |
--help, -h |
- |
All |
Display command help |
--version, -v |
- |
All |
Display version and build information |
Native profiling options:
| Option |
Default |
Scope |
Description |
--memory-mode |
None |
Native memory, Java memory |
Memory profiling mode; required with --type memory |
--cpuid |
All CPUs |
Native CPU |
Comma-separated CPU list or ranges; off-CPU samples use the task’s switch-out CPU |
--cpu-mode |
oncpu |
Native CPU |
oncpu for frequency sampling or offcpu for blocked/runqueue time attribution |
--require-hardware-pmu |
false |
Native on-CPU |
Require hardware PMU sampling; fail instead of falling back to the software CPU clock |
--offcpu-phase |
all |
Native off-CPU |
Accumulate all, blocked, or runqueue time |
--offcpu-min-duration-us |
1000 |
Native off-CPU |
Discard phases shorter than this duration in microseconds |
--offcpu-stats |
false |
Native off-CPU |
Collect BPF diagnostic statistics; adds overhead to error and cleanup paths |
--thread-group |
false |
Native |
Also profile other threads in the target PID’s thread group |
--physical-memory-probability |
100 |
Native physical memory |
Physical memory event sampling probability from 1 to 100 |
--log-bpf-debug |
false |
Native |
Emit BPF debug events; not recommended for normal profiling |
Logging options:
| Option |
Default |
Description |
--log-level |
error |
trace, debug, info, warn, or error |
--log-file |
stdout |
Log file path, or stdout |
--log-size |
100 |
Log rotation size in MB; 0 disables rotation; applies only to file output |
--verbose |
false |
Equivalent to --log-level debug --log-file stdout and overrides both explicit logging options |
3. Observing C, C++, and Go
C, C++, and Go use the same native eBPF collector; only the --language value changes. CPU mode counts call-stack samples and includes user-space and kernel-space stacks when symbols can be resolved.
sudo _output/bin/profiler \
  --type cpu \
  --language go \
  --pid 12345 \
  --duration 30 \
  --aggr-interval 10 \
  --freq 99 \
  --output-format flamegraph \
  --output-path ./profiles/go-cpu
Add --thread-group to include worker threads in the same process. Add --cpuid 2,4-7 to limit collection to selected CPUs. Native CPU profiling also supports container-level and host-level collection:
Native on-CPU profiling first uses hardware CPU-cycle events and falls back to
the software CPU clock when the hardware PMU is unavailable. --freq remains
samples per second for either source. Use --require-hardware-pmu when software
clock fallback would hide IRQ-disabled CPU time.
# Profile a specific container
sudo _output/bin/profiler \
  --type cpu --language c --container-id <container-id> \
  --duration 30 --aggr-interval 10 \
  --output-format collapsed --output-path ./profiles/container

# Profile the host without specifying a PID or container
sudo _output/bin/profiler \
  --type cpu --language c \
  --duration 30 --aggr-interval 10 \
  --output-format flamegraph --output-path ./profiles/host
To attribute time spent outside the CPU to the call path that descheduled, select off-CPU mode:
sudo _output/bin/profiler \
  --type cpu --language go --pid 12345 --thread-group \
  --cpu-mode offcpu --offcpu-phase all \
  --cpuid 2,4-7 \
  --offcpu-min-duration-us 1000 \
  --duration 30 --aggr-interval 10 \
  --output-format flamegraph --output-path ./profiles/go-offcpu
Off-CPU output is event-driven, so --freq does not apply. With --cpuid, an interval is collected only when the task switches out from a selected CPU; later wakeup or switch-in on another CPU does not change that attribution. Flame graphs use nanoseconds directly and add roots such as off-CPU blocked, scheduling delay (preempted), and scheduling delay (yielded). The all phase includes blocked and runqueue time but keeps them separated by these roots. A single stable BPF stack map is used so a long sleep cannot be resolved against a later rotating stack-map generation.
Native memory profiling supports these dimensions:
--memory-mode |
Measurement |
Suitable for |
virtual_alloc |
Virtual address-space allocation and its call stacks |
Excessive mmap activity and address-space growth |
physical_alloc |
Physical memory newly allocated during the collection window |
Physical page allocation triggered by page faults and allocation-rate analysis |
physical_usage |
Physical memory still resident at collection time |
Sources of resident memory and paths retaining physical pages |
sudo _output/bin/profiler \
  --type memory \
  --language c++ \
  --memory-mode physical_usage \
  --pid 12345 \
  --thread-group \
  --physical-memory-probability 100 \
  --duration 30 \
  --aggr-interval 10 \
  --output-format flamegraph \
  --output-path ./profiles/native-memory
--physical-memory-probability applies only to physical_alloc and physical_usage. Lowering it reduces processing for high-frequency memory events, but flame-graph values are then estimates based on sampled events rather than counts of every event.
4. Observing Java
Java CPU profiling depends on async-profiler. It supports a single PID, a container, or multiple PIDs:
_output/bin/profiler \
  --type cpu \
  --language java \
  --pid 12345,12346 \
  --tool-path /opt/huatuo/tools \
  --max-concurrent-procs 2 \
  --duration 30 \
  --aggr-interval 10 \
  --freq 99 \
  --output-format flamegraph \
  --output-path ./profiles/java-cpu
Java memory profiling supports two dimensions:
--memory-mode |
Measurement |
Suitable for |
object_alloc |
Objects allocated during the collection window and their allocation call stacks |
High allocation rates, short-lived objects, and sources of GC pressure |
object_usage |
Live objects and their allocation call stacks |
Long-lived objects, sources of heap usage, and suspected memory leaks |
_output/bin/profiler \
  --type memory \
  --language java \
  --memory-mode object_usage \
  --pid 12345 \
  --tool-path /opt/huatuo/tools \
  --duration 30 \
  --aggr-interval 10 \
  --output-format flamegraph \
  --output-path ./profiles/java-memory
To target a container, replace --pid with --container-id <container-id>. If a container has multiple candidate processes, use --binary-match-path to select the target executable path.
5. Observing Python
Python currently supports CPU profiling only. --aggr-interval must equal --duration, so one collection produces one aggregation window. --tool-path points to the shared tool root containing py-spy.
_output/bin/profiler \
  --type cpu \
  --language python \
  --pid 12345,12346 \
  --tool-path /opt/huatuo/tools \
  --max-concurrent-procs 2 \
  --duration 30 \
  --aggr-interval 30 \
  --freq 99 \
  --output-format flamegraph \
  --output-path ./profiles/python-cpu
Python does not support --type memory. Use a separate memory analysis tool for Python memory profiling; the current profiler command does not invoke memray to generate Python memory profiles.
| Format |
Output |
When to use it |
collapsed |
perf_<Unix timestamp>.folded; each line contains a semicolon-separated call stack followed by a count |
Scripted searches, result comparison, or rendering later with another flame-graph tool |
flamegraph |
flamegraph_<Unix timestamp>.svg; an SVG with embedded interaction scripts |
Default format for manual analysis; supports searching, zooming, and inspecting frame values in a browser |
svg |
The same interactive SVG as flamegraph |
Compatibility with callers that explicitly request SVG; currently equivalent to flamegraph |
remote |
No local flame graph; uploads pprof-compatible data through a Unix socket |
Integration with the HUATUO storage pipeline; not suitable for offline viewing |
A flame graph shows the call direction from bottom to top. Rectangle width represents the cumulative value for that call stack in the selected profiling mode. For CPU profiles, width represents the proportion of CPU time derived from sample counts. For memory profiles, it represents virtual allocation, physical allocation, physical residency, Java object allocation, or live-object volume, depending on the selected mode. Horizontal position does not represent chronological order.
Example folded stacks:
main;handleRequest;parsePayload 428
main;handleRequest;writeResponse 172
Choose collapsed when you need to retain raw data and later render it with different colors or filters. Choose flamegraph when you want to inspect hotspots directly. remote depends on the HUATUO toolstream Unix socket, requires a non-empty --tracer-id, and should not be selected for standalone offline use.
7. Reproducing Integration Test Examples
The repository’s integration tests provide executable end-to-end examples. Each test creates a target process, runs profiler, and verifies the expected call stack in the output:
# Native CPU
sudo ./integration/run.sh test_profiler_native_cpu.sh

# Native off-CPU blocking and scheduling delay
sudo ./integration/run.sh test_profiler_native_cpu_offcpu.sh

# Native virtual and physical memory
sudo ./integration/run.sh test_profiler_native_memory_virtual_alloc.sh
sudo ./integration/run.sh test_profiler_native_memory_physical_usage.sh

# Java CPU and memory
sudo ./integration/run.sh test_profiler_java_cpu_multi_pid.sh
sudo ./integration/run.sh test_profiler_java_memory_usage_alloc.sh

# Python multi-process CPU
sudo ./integration/run.sh test_profiler_python_cpu_multi_pid.sh
Container, thread-group, and CPU-selection examples are available in test_profiler_native_cpu_container.sh, test_profiler_native_cpu_thread_group.sh, and test_profiler_native_cpu_cpuid.sh, respectively. Run make build first and configure the Java or Python profiler path in integration/env.sh as needed.
⚙️ How It Works
profiler first selects a collector based on the language and profile type. The native on-CPU collector attaches eBPF programs to perf events; off-CPU mode attaches scheduler switch, wakeup, exit, and task-free tracepoints. Native memory collectors record allocation and release paths through kernel events. The Java and Python collectors start async-profiler and py-spy subprocesses, respectively. Collected records enter a common aggregation pipeline, which merges counts by call stack and then writes a local file or uploads the result to remote storage.
flowchart LR
    CLI[profiler CLI options] --> Select{Language and profile type}
    Select -->|C/C++/Go| Native[Native eBPF collector]
    Select -->|Java| Java[async-profiler]
    Select -->|Python| Python[py-spy]
    Native --> Queue[Sample record queue]
    Java --> Queue
    Python --> Queue
    Queue --> Aggregate[Aggregate by call stack]
    Aggregate --> Folded[Collapsed stacks]
    Aggregate --> SVG[Interactive SVG flame graph]
    Aggregate --> Remote[Remote upload through Unix socket]
--duration controls the collection lifetime, while --aggr-interval controls the snapshot interval for remote uploads. Local collapsed, flamegraph, and svg modes write the final aggregate when collection ends. remote creates and uploads snapshots at the aggregation interval. The queue decouples collection from symbolization, aggregation, and output so file rendering does not block the sampling path.
🌟 Conclusion
5.5 - Hardware Events
Overview
HUATUO monitors Linux kernel hardware error events with zero instrumentation overhead and minimal runtime cost. Structured fault records are persisted to storage and exposed as Prometheus counters for use by alerting and visualization systems.
Use Cases
-
General-Purpose Computing
In large-scale server clusters, memory ECC correctable errors (CE) are common low-severity fault signals. A single CE is automatically corrected by hardware. If the CE rate on a given DIMM rises persistently, however, it indicates impending memory failure. HUATUO detects such events in real time via EDAC/MCE tracepoints, enabling operations teams to perform preventive replacements before complete memory failure and unplanned downtime occur.
-
AI Computing
AI training workloads require high hardware reliability. A single faulty PCIe device can cause an entire training job to fail. HUATUO supports PCIe AER event monitoring and reports link-layer errors on GPUs, NVLink bridges, and RDMA NICs (such as InfiniBand HCAs) — including Data Link Protocol Errors and ECRC Errors — in real time. This data provides hardware health status to AI cluster schedulers, supporting rapid fault node isolation and workload migration.
-
Storage Services
Storage servers typically host large numbers of PCIe NVMe SSDs and HBA cards. PCIe AER errors such as Completion Timeout and Malformed TLP are early indicators of storage device performance degradation or drive dropout. HUATUO monitoring data can be correlated with storage I/O latency metrics to support root cause analysis.
-
Security and Compliance
Industries with strict compliance requirements — such as finance and government — must maintain a complete history of all hardware faults. Structured event records (including timestamps, device identifiers, error types, and raw register values) can serve directly as compliance evidence for hardware health logs.
How It Works
HUATUO observes the kernel’s MCE, EDAC, ACPI GHES, and PCIe AER subsystems via eBPF. When an eBPF tracepoint fires, the raw event is written to a BPF Perf Event Buffer. A user-space process reads the event, parses the struct fields, generates a structured record, and persists it locally or to a remote store. The overall architecture is shown below:
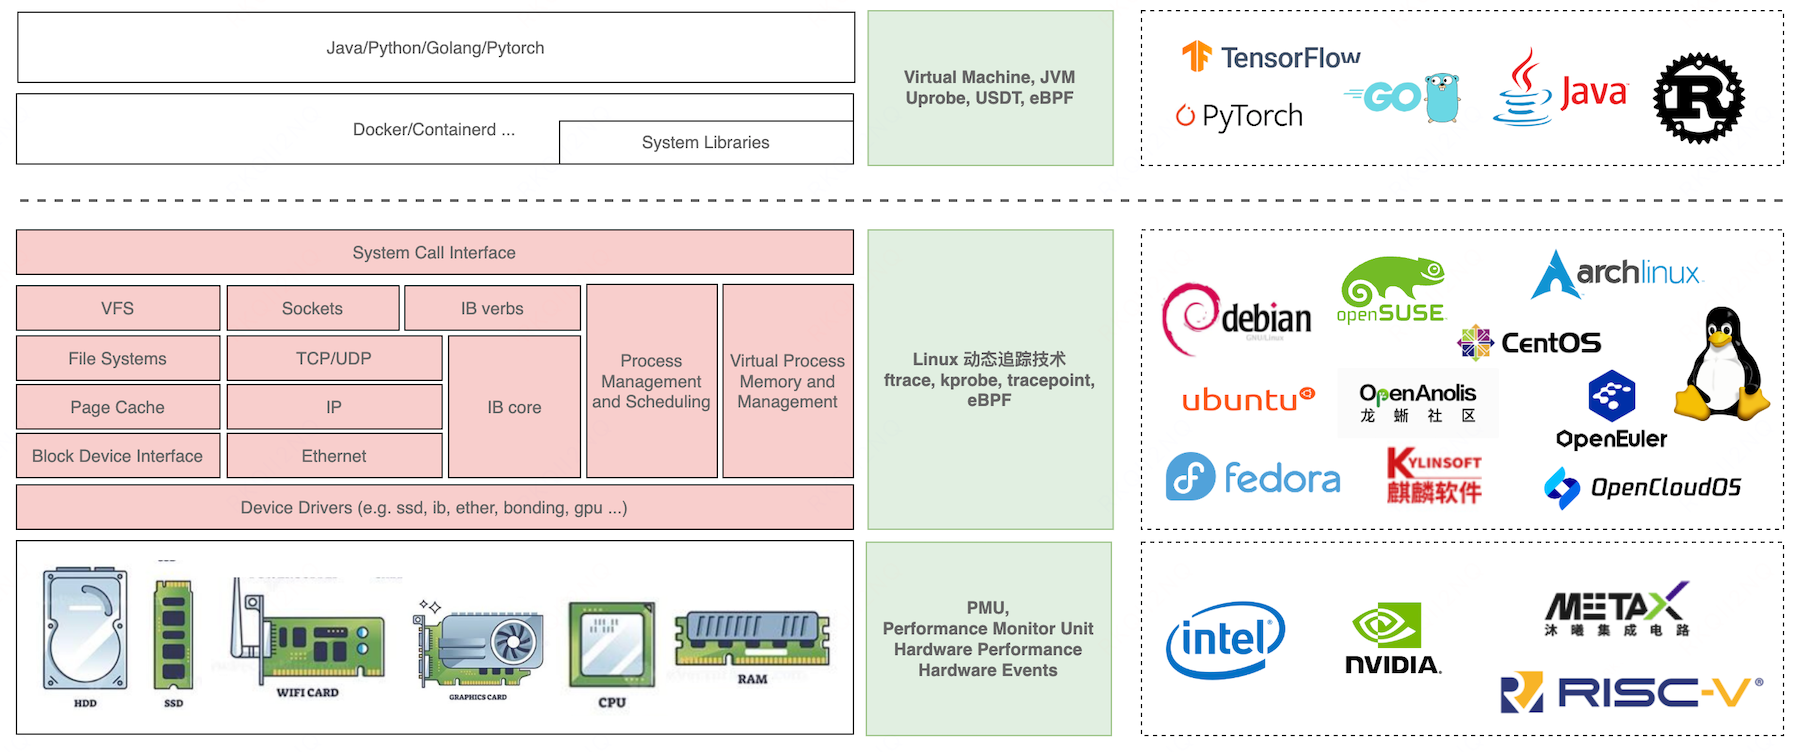
RAS Architecture
The Linux kernel’s RAS framework consists of several loosely coupled subsystems. Together, they cover the full hardware fault spectrum — from CPU internal errors to PCIe link errors.
graph TB
    subgraph HW["Hardware Layer"]
        CPU["CPU\nx86 / x86-64"]
        MEM["Memory\nDDR4/DDR5 DIMM ECC"]
        Platform["Platform Hardware\nSoC / PCH"]
        PCIeDev["PCIe Devices\nGPU / NVMe / HCA / FPGA"]
    end

    subgraph FW["Firmware Layer"]
        BIOS["BIOS / UEFI\nCPER Buffer (APEI)"]
    end

    subgraph Kernel["Linux Kernel RAS Subsystems"]
        MCE["MCE Subsystem\narch/x86/kernel/cpu/mce"]
        EDAC["EDAC Subsystem\ndrivers/edac"]
        GHES["ACPI GHES Subsystem\ndrivers/acpi/apei"]
        AER["PCIe AER Subsystem\ndrivers/pci/pcie/aer"]
    end

    subgraph TP["Kernel Tracepoints"]
        TP1["tracepoint/mce/mce_record"]
        TP2["tracepoint/ras/mc_event"]
        TP3["tracepoint/ras/non_standard_event"]
        TP4["tracepoint/ras/aer_event"]
    end

    CPU -->|"MCE Exception (#MC) + THR Interrupt"| MCE
    MEM -->|ECC Error| EDAC
    Platform -->|APEI Error Record| BIOS
    BIOS -->|CPER Buffer| GHES
    PCIeDev -->|AER Interrupt| AER

    MCE --> TP1
    EDAC --> TP2
    GHES --> TP3
    AER --> TP4
-
MCE
MCE (Machine Check Architecture) is a hardware fault-tolerance mechanism built into the processor, defined by Intel and AMD in their respective architecture specifications. The processor contains a set of Machine Check Banks, each corresponding to a class of hardware resource (e.g., L1 cache, L2 cache, memory controller, TLB). When a hardware error is detected, the MSRs of the corresponding bank (MCi_STATUS, MCi_ADDR, MCi_MISC) are populated with error information, and an MCE exception is raised.
-
MCE THR
MCE supports a threshold interrupt mechanism. When the count of a given class of correctable errors exceeds a configured threshold, a dedicated APIC interrupt (THR) is triggered instead of escalating to a full MCE exception. This allows the operating system to issue an early alert when the error rate rises abnormally, rather than waiting until the error becomes uncorrectable.
-
EDAC
EDAC (Error Detection And Correction) is the Linux kernel subsystem dedicated to handling memory and hardware ECC errors. Its stated goal is “to detect and report errors occurring in the computer hardware running under Linux.” EDAC drivers communicate directly with the memory controller and parse the physical location of ECC errors — including memory controller index, channel, slot, and row/column address.
-
ACPI GHES
ACPI GHES (Generic Hardware Error Source) is a platform-agnostic hardware error reporting mechanism defined by the BIOS/UEFI through the APEI (ACPI Platform Error Interface) specification. The BIOS firmware writes hardware errors that cannot be handled by a specific driver — such as SoC-internal errors or platform-specific memory errors — into CPER (Common Platform Error Record) buffers described in the GHES descriptor. The Linux kernel reads these CPER records and reports the “non-standard” error sections that cannot be parsed by a standard subsystem.
-
PCIe AER
PCIe AER (Advanced Error Reporting) is an error reporting mechanism defined in the PCIe specification. It enables PCIe devices to report link-layer and transaction-layer errors to the operating system with precision.
Metrics Reference
-
RAS Metrics
# HELP huatuo_bamai_ras_hw_total total RAS hardware error events by source type
# TYPE huatuo_bamai_ras_hw_total counter
huatuo_bamai_ras_hw_total{host="hostname",region="dev",type="acpi"} 0
huatuo_bamai_ras_hw_total{host="hostname",region="dev",type="aer"} 0
huatuo_bamai_ras_hw_total{host="hostname",region="dev",type="edac"} 0
huatuo_bamai_ras_hw_total{host="hostname",region="dev",type="mce"} 0
huatuo_bamai_ras_hw_total{host="hostname",region="dev",type="thr"} 0
-
NIC Packet Drop
huatuo_bamai_netdev_hw_rx_dropped_total{host="hostname",region="dev",device="eth0",driver="ixgbe"} 0
-
RDMA PFC
# HELP huatuo_bamai_netdev_dcb_pfc_received_total count of the received pfc frames
# TYPE huatuo_bamai_netdev_dcb_pfc_received_total counter
huatuo_bamai_netdev_dcb_pfc_received_total{device="enp6s0f0np0",host="hostname",prio="0",region="dev"} 0
huatuo_bamai_netdev_dcb_pfc_received_total{device="enp6s0f0np0",host="hostname",prio="1",region="dev"} 0
huatuo_bamai_netdev_dcb_pfc_received_total{device="enp6s0f0np0",host="hostname",prio="2",region="dev"} 0
huatuo_bamai_netdev_dcb_pfc_received_total{device="enp6s0f0np0",host="hostname",prio="3",region="dev"} 0
huatuo_bamai_netdev_dcb_pfc_received_total{device="enp6s0f0np0",host="hostname",prio="4",region="dev"} 0
huatuo_bamai_netdev_dcb_pfc_received_total{device="enp6s0f0np0",host="hostname",prio="5",region="dev"} 0
huatuo_bamai_netdev_dcb_pfc_received_total{device="enp6s0f0np0",host="hostname",prio="6",region="dev"} 0
huatuo_bamai_netdev_dcb_pfc_received_total{device="enp6s0f0np0",host="hostname",prio="7",region="dev"} 0
# HELP huatuo_bamai_netdev_dcb_pfc_send_total count of the sent pfc frames
# TYPE huatuo_bamai_netdev_dcb_pfc_send_total counter
huatuo_bamai_netdev_dcb_pfc_send_total{device="enp6s0f0np0",host="hostname",prio="0",region="dev"} 0
huatuo_bamai_netdev_dcb_pfc_send_total{device="enp6s0f0np0",host="hostname",prio="1",region="dev"} 0
huatuo_bamai_netdev_dcb_pfc_send_total{device="enp6s0f0np0",host="hostname",prio="2",region="dev"} 0
huatuo_bamai_netdev_dcb_pfc_send_total{device="enp6s0f0np0",host="hostname",prio="3",region="dev"} 0
huatuo_bamai_netdev_dcb_pfc_send_total{device="enp6s0f0np0",host="hostname",prio="4",region="dev"} 0
huatuo_bamai_netdev_dcb_pfc_send_total{device="enp6s0f0np0",host="hostname",prio="5",region="dev"} 0
huatuo_bamai_netdev_dcb_pfc_send_total{device="enp6s0f0np0",host="hostname",prio="6",region="dev"} 0
huatuo_bamai_netdev_dcb_pfc_send_total{device="enp6s0f0np0",host="hostname",prio="7",region="dev"} 0
-
Storage
Every hardware error event is persisted in structured form — either to the local huatuo-local directory or to a remote store such as Elasticsearch or OpenSearch. All records share the following common fields:
{
    "hostname": "hostname",
    "region": "dev",
    "uploaded_timestamp": "2026-03-05T18:28:39.153438921+08:00",
    "tracer_name": "netdev_event",
    "observed_timestamp": "2026-03-05T18:28:39.153+08:00",
    "tracer_type": "event",
    "tracer_data": {
        "ifname": "eth0",
        "index": 2,
        "linkstatus": "linkstatus_admindown",
        "mac": "5c:6f:11:11:11:11",
        "start": false
    }
}
The linkstatus field takes the following values:
linkstatus_adminup — brought up by an administrator, e.g., ip link set dev eth0 uplinkstatus_admindown — brought down by an administrator, e.g., ip link set dev eth0 downlinkstatus_carrierup — physical link restoredlinkstatus_carrierdown — physical link failure
{
    "hostname": "localhost",
    "region": "xxx",
    "uploaded_timestamp": "2026-05-11T16:58:47.328548319+08:00",
    "tracer_name": "ras",
    "observed_timestamp": "2026-05-11T08:58:47.329Z",
    "kernel_observed_timestamp": "2026-05-11T08:58:47.328548319Z",
    "tracer_type": "event",
    "tracer_data": {
        "dev": "MEM",
        "event": "EDAC",
        "type": "Corrected",
        "info": "{\"err_count\":0,\"err_type\":\"Corrected\",\"err_msg\":\"memory read error\",\"label\":\"CPU_SrcID#0_Ha#0_Chan#0_DIMM#0\",\"mc_index\":0,\"top_layer\":0,\"mid_layer\":0,\"low_layer\":-1,\"addr\":7860269056,\"grain\":128,\"syndrome\":0,\"driver\":\" area:DRAM err_code:0000:009f socket:0 ha:0 channel_mask:1 rank:0\"}"
    }
}
| Field |
Description |
Device |
Identifier of the hardware component where the error occurred (e.g., CPU/MEM, MEM, ACPI, PCIe 0000:01:00.0) |
Event |
Event subtype (MCE, EDAC, APIC, AER) |
ErrType |
Error severity level (see table below) |
ObservedTimestamp |
UTC userspace observation time |
KernelObservedTimestamp |
UTC kernel observation time (top-level Document field) |
Info |
Detailed fields for the specific event |
| Error Type |
Description |
Typical Sources |
Corrected |
Automatically corrected by hardware; transparent to the OS |
MCE CE, EDAC CE, ACPI Sev=1, AER Severity=2 |
UncorrectedRecoverable |
Not corrected by hardware, but recoverable by system software |
MCE UE, EDAC UE, ACPI Sev=2, AER Severity=0 |
UncorrectedDeferred |
Not corrected by hardware; requires deferred handling |
MCE MCI_STATUS_DEFERRED, EDAC HW_EVENT_ERR_DEFERRED |
UncorrectedFatal |
Fatal hardware error; requires immediate reboot |
EDAC FATAL, ACPI Sev=3, AER Severity=0 |
Info |
Error type for which the system is expected to log informational records |
EDAC HW_EVENT_ERR_INFO, ACPI Sev=0 |
Field Reference
-
MCE
Monitored components: CPU cores, L1/L2/L3 cache, TLB, memory controller (IMC), and interconnect buses (QPI/UPI/Infinity Fabric).
| Field |
MSR Source |
Description |
mcg_cpu_cap |
MCG_CAP |
Machine Check Global Capability Register. The lower 8 bits (Count) indicate the number of MC Banks in the system. |
mcg_msr_status |
MCG_STATUS |
Machine Check Global Status Register. |
banks_msr_status |
MCi_STATUS |
Bank Status Register (primary field). The lower 16 bits contain the MCA error code, classifying the error type (e.g., memory hierarchy error, bus error). The upper bits include control flags: UC (uncorrectable), EN (enabled), MISCV (MISC valid), ADDRV (ADDR valid), and PCC (processor context corrupt). |
banks_msr_addr |
MCi_ADDR |
Physical memory address where the error occurred (valid only when MCi_STATUS.ADDRV=1). Used to identify the faulty DIMM or cache line. |
banks_msr_misc |
MCi_MISC |
Supplementary information register (valid only when MCi_STATUS.MISCV=1). |
mca_synd_msr |
MCA_SYND |
Syndrome register (AMD-specific). |
mca_ipid_msr |
MCA_IPID |
Instance ID register (AMD-specific). |
instr_pointer |
RIP register |
Instruction pointer at the time of the MCE (reliable only when MCG_STATUS.EIPV=1). |
tsc_timestamp |
TSC |
CPU timestamp counter value at the time of the error (can be converted to absolute time using the kernel clock). |
walltime |
Kernel time |
Unix timestamp (in seconds) at the time of the error. |
cpu |
— |
Logical CPU number where the MCE occurred. |
cpuid |
CPUID |
CPUID value of the CPU where the MCE occurred (includes Family, Model, and Stepping). |
apicid |
APIC ID |
APIC ID of the CPU where the MCE occurred (can be mapped to a physical core or hyperthread). |
socketid |
— |
CPU socket number (Socket ID). Used to identify physical CPUs in multi-socket servers. |
code_seg |
CS register |
Code segment register value at the time of the MCE (used to determine privilege level). |
bank |
— |
Bank number (typically: Bank 0 = L1I, Bank 1 = L1D, Bank 2 = L2, Bank 4+ = memory controller; numbering varies by platform). |
cpuvendor |
— |
CPU vendor identifier: 0 = Intel, 1 = Unknown, 2 = AMD. |
-
EDAC
Monitored components: memory ECC errors.
| Field |
Description |
err_count |
Cumulative error count for this event. |
err_type |
Error severity level. |
err_msg |
Human-readable error description string (e.g., "CE memory read error on CPU#0Channel#0_DIMM#0 (channel:0 slot:0 page:0x12345 offset:0x0 grain:8 syndrome:0x0)"). |
label |
Physical DIMM location label (e.g., "CPU_SrcID#0_Ha#0_Chan#0_DIMM#0"). Generated by the EDAC driver based on DIMM topology; maps directly to a physical memory slot in the system. |
mc_index |
Memory controller index (0-based). Distinguishes between IMCs on servers with multiple memory controllers. |
top_layer |
Top-layer index in the memory hierarchy (typically the channel number; -1 indicates invalid). |
mid_layer |
Middle-layer index in the memory hierarchy (typically the slot or rank number; -1 indicates invalid). |
low_layer |
Bottom-layer index in the memory hierarchy (typically the bank or row number; -1 indicates invalid). |
addr |
Physical memory address where the error occurred (64-bit unsigned integer; 0 indicates an invalid address). |
grain |
Error granularity (grain size, in bytes). Represents the smallest memory unit that may be affected. Computed as 1 << GrainBits. For example, grain=8 means the error is localized to an 8-byte unit (a cache line sub-block). |
syndrome |
ECC syndrome value. |
driver |
EDAC driver name (e.g., "amd64_edac", "sb_edac"). |
-
ACPI GHES
Monitored components: platform-specific hardware errors.
| Field |
Description |
severity |
Raw ACPI/CPER error severity value. |
sec_type |
Error section type GUID (16 bytes, hexadecimal string). Defined by the UEFI specification and hardware vendors. Identifies the hardware category of the error record (e.g., memory error section, PCIe error section, ARM processor error section). |
fru_id |
FRU (Field Replaceable Unit) identifier GUID (16 bytes, hexadecimal string). Uniquely identifies the replaceable hardware component where the error occurred (e.g., a specific DIMM or PCIe card). |
fru_text |
Human-readable FRU description string (e.g., "CPU0_DIMM_A1"). |
data_len |
Raw error data payload length (in bytes). |
raw_data |
Hexadecimal dump of raw error data (space-separated bytes). Used for in-depth diagnostics; must be interpreted with the relevant hardware vendor documentation. |
-
PCIe AER
Monitored devices include GPUs, NVMe SSDs, RDMA NICs/HCAs, FPGA accelerator cards, and PCIe switches.
| Field |
Description |
dev_name |
PCIe device name (BDF format), e.g., "0000:03:00.0" (Domain:Bus:Device.Function). |
err_type |
Error severity level (Corrected / Uncorrected / Fatal). |
err_reason |
Error reason description string. Decoded from the bits of the AER status register (see the tables below). |
tlp_header |
TLP (Transaction Layer Packet) header quad-word that triggered the error (format: {dword0, dword1, dword2, dword3}, hexadecimal). The TLP header contains the transaction type, address, and requester ID — key data for root cause analysis. Displays "not available" when TlpHeaderValid=0. |
-
PCIe Correctable Error Types
| Bitmask |
Description |
0x00000001 |
Receiver Error. The physical layer received a data symbol that does not conform to the specification. Typically caused by signal integrity issues such as excessive cable length or impedance mismatch. |
0x00000040 |
Bad TLP. The LCRC (link-layer CRC) check on a TLP failed, indicating bit flips during transmission. The PCIe link layer automatically retransmits the TLP. |
0x00000080 |
Bad DLLP. A link-layer control packet (such as ACK/NAK or flow control update) failed its CRC check. |
0x00000100 |
Replay Number Rollover. The REPLAY_NUM field tracks retransmit count. This error indicates too many retransmissions since the last ACK, typically signaling sustained poor link quality. |
0x00001000 |
Replay Timer Timeout. The sender did not receive an ACK within the allowed time, triggering TLP retransmission. Persistent occurrence indicates abnormal link latency or insufficient receiver processing capacity. |
0x00002000 |
Advisory Non-Fatal Error. An uncorrectable error that software has downgraded to correctable (requires the ANFE feature in the AER capability). Commonly seen when an Unsupported Request Completion is received. |
0x00004000 |
Corrected Internal Error. An internal ECC or parity error that the device corrected autonomously. |
0x00008000 |
Header Log Overflow. The AER header log register is full. TLP headers for subsequent errors cannot be recorded, though errors are still counted. |
-
PCIe Uncorrectable Error Types
| Bitmask |
Description |
0x00000001 |
Undefined. A reserved bit was set, typically indicating non-compliant firmware or hardware behavior. |
0x00000010 |
Data Link Protocol Error. A packet that violates the DLLP protocol specification was received. This is a severe link-layer fault. |
0x00000020 |
Surprise Down Error. The physical link disconnected without a Hot-Plug notification (e.g., due to unexpected power loss or poor contact). This is a high-severity error in hot-plug environments. |
0x00001000 |
Poisoned TLP. A TLP was received with the Error Poisoning (EP) bit set to 1, indicating that the upstream sender was aware of data corruption. This mechanism propagates and isolates errors to prevent silent data corruption. |
0x00002000 |
Flow Control Protocol Error. A packet that violates PCIe flow control credit rules was received. This is a severe protocol violation. |
0x00004000 |
Completion Timeout. The requester sent a non-posted transaction (e.g., Memory Read) but did not receive a Completion within the required timeout. Commonly caused by NVMe firmware issues, RDMA NIC driver bugs, or PCIe link interruptions. |
0x00008000 |
Completer Abort. The completer returned an explicit CA (Completer Abort) status, indicating that the request was rejected. |
0x00010000 |
Unexpected Completion. A Completion was received that could not be matched to any outstanding request (tag mismatch). Typically caused by device firmware bugs or data path errors. |
0x00020000 |
Receiver Overflow. The receiver’s flow control credits indicated available buffer space, but an overflow occurred. This is a severe flow control violation. |
0x00040000 |
Malformed TLP. The packet header contains fields that violate the specification (e.g., illegal length, reserved bits set, invalid address range). Typically indicates a severe firmware defect. |
0x00080000 |
ECRC Error. The ECRC check on the TLP trailer failed (requires ECRC support on both endpoints). Indicates data corruption across the entire transmission path, including internal PCIe switch fabric. A key metric in high-reliability environments. |
0x00100000 |
Unsupported Request. The completer returned a UR (Unsupported Request) status, indicating that the transaction type or address range is not supported by the device. |
0x00200000 |
ACS Violation. PCIe ACS (Access Control Services) prevents peer-to-peer DMA between PCIe devices from bypassing the IOMMU. This error indicates a data access that violates the ACS policy. Requires attention in virtualization security environments. |
0x00400000 |
Uncorrectable Internal Error. An internal ECC or parity error occurred that the device could not self-correct (e.g., SRAM double-bit error). Typically indicates hardware damage. |
0x00800000 |
MC Blocked TLP. A PCIe Multicast TLP was blocked by ACS or the Multicast control mechanism. |
0x01000000 |
AtomicOp Egress Blocked. An AtomicOp request (FetchAdd, Swap, or CAS) was blocked from egressing by ACS. Commonly seen in RDMA or GPU direct-connect configurations. |
0x02000000 |
TLP Prefix Blocked. A packet with an End-End TLP Prefix was blocked from forwarding by ACS or another mechanism. |
Summary
Deploy HUATUO in production to enable hardware error monitoring and proactive operations.
6 - Best Practice
6.1 - Storage Service
🎯 About HUATUO
HUATUO is an open-source OS-level deep observability project initiated by DiDi and incubated by the CCF (China Computer Federation). It provides kernel-level observability for cloud-native computing, AI computing, cloud services, and foundational infrastructure.
📖 Overview
HUATUO supports persisting Linux kernel events collected by the Tracer and AutoTracing data to external storage backends. Both Elasticsearch and OpenSearch are supported.
After serialization to JSON, collected events are written concurrently to the local node directory (huatuo-local/) and the configured remote storage backend. The local directory retains a local copy of events; the remote backend provides durable storage and structured query capabilities.
This document covers configuration and verification for both Elasticsearch and OpenSearch. Examples use Docker deployments. In production, replace the addresses with your actual service endpoints — the configuration format is the same.
🎯 Use Cases
Kubernetes Cloud-Native Fault Tracing
In containerized environments, kernel events such as Pod OOM and node Hung Task are transient — logs are often purged shortly after the event occurs. By writing events to Elasticsearch or OpenSearch, operations teams can query the historical timeline of anomalies by time range and precisely identify the root cause of intermittent failures during post-incident reviews.
AI Compute Cluster Stability Auditing
During long-running GPU training workloads, the historical distribution of events such as ras hardware errors and iotracing I/O latency is critical for capacity planning and hardware health assessment. Persisting collected data enables aggregate queries to establish node stability baselines and supports proactive maintenance decisions.
Compliance and Event Retention
Security compliance standards require that system anomaly events be traceable. Writing HUATUO-captured kernel events to OpenSearch and configuring an index lifecycle policy satisfies compliance requirements for event retention periods and query capabilities.
Both Elasticsearch and OpenSearch provide native data source integrations with Grafana. Once HUATUO events are written to storage, you can build kernel event trend dashboards in Grafana, overlaid with application-layer metrics for historical analysis and alert review.
💎 Value
| Dimension |
Local Storage Only |
With External Storage Backend |
| Data Durability |
Limited by node disk capacity; may be lost on restart |
Persisted to distributed storage; supports long-term retention |
| Query Capability |
No structured queries; relies on file search |
Full-text search, field filtering, time-range aggregation |
| Visualization |
Not supported |
Direct integration with Grafana, Kibana, and similar platforms |
| Multi-node Aggregation |
Data scattered across individual nodes |
Centralized storage; supports cross-node queries |
| Compliance Retention |
Difficult to meet retention requirements |
Configurable index lifecycle policies; meets compliance retention requirements |
🚀 Usage
OpenSearch V2
1. Deploy OpenSearch
docker pull opensearchproject/opensearch:2.6.0
docker run -d --name opensearch --network host \
  -e "discovery.type=single-node" \
  opensearchproject/opensearch:2.6.0
2. Verify Service Status
curl -k -u admin:admin https://localhost:9200
Example response:
{
  "name" : "22ca72df78c0",
  "cluster_name" : "docker-cluster",
  "cluster_uuid" : "yxb3foceQVKzXXO6bHpPHQ",
  "version" : {
    "distribution" : "opensearch",
    "number" : "2.6.0",
    "build_type" : "tar",
    "build_hash" : "7203a5af21a8a009aece1474446b437a3c674db6",
    "build_date" : "2023-02-24T18:57:04.388618985Z",
    "build_snapshot" : false,
    "lucene_version" : "9.5.0",
    "minimum_wire_compatibility_version" : "7.10.0",
    "minimum_index_compatibility_version" : "7.0.0"
  },
  "tagline" : "The OpenSearch Project: https://opensearch.org/"
}
If verification fails, check the container logs:
Add the following configuration to huatuo-bamai.conf. The default username and password for the OpenSearch container image are both admin. For a full description of storage configuration options, see the Configuration Guide.
[Storage.Elasticsearch]
    Address = "https://127.0.0.1:9200"
    Index = "huatuo_bamai"
    Username = "admin"
    Password = "admin"
4. Start huatuo-bamai
Use --config-dir to specify the directory containing the configuration file:
./_output/bin/huatuo-bamai --region dev --config-dir .
When files (e.g., net_rx_latency) appear in the local storage directory huatuo-local/, kernel events have been successfully captured. Query data from OpenSearch with:
curl -k -u admin:admin \
  -X GET "https://localhost:9200/huatuo_bamai/_search?pretty" \
  -H "Content-Type: application/json" \
  -d '{"query": {"match_all": {}}}'
Example response:
{
    "_index" : "huatuo_bamai",
    "_id" : "yjPG_50Bu_OF-hukxKR7",
    "_score" : 1.0,
    "_source" : {
      "hostname" : "hostname",
      "region" : "dev",
      "uploaded_timestamp" : "2026-05-07T00:11:49.753166222Z",
      "tracer_name" : "net_rx_latency",
      "observed_timestamp" : "2026-05-07T00:11:49.753166222Z",
      "tracer_type" : "event",
      "tracer_data" : {
        "comm" : "<nil>",
        "pid" : 0,
        "latency_stage" : "RX_STAGE_NETIF",
        "latency_ms" : 1776078133565,
        "tcp_saddr" : "127.0.0.1",
        "tcp_daddr" : "127.0.0.1",
        "tcp_sport" : 37736,
        "tcp_dport" : 9200,
        "tcp_seq" : 1080592402,
        "tcp_ack_seq" : 2465063876,
        "packet_len_bytes" : 781
      }
    }
}
To get the total document count without listing individual records:
curl -k -u admin:admin -X GET "https://localhost:9200/huatuo_bamai/_count?pretty"
Example response: the count value equals the total number of written records.
{
  "count" : 2680,
  "_shards" : {
    "total" : 1,
    "successful" : 1,
    "skipped" : 0,
    "failed" : 0
  }
}
Elasticsearch V8
1. Deploy Elasticsearch
docker pull docker.elastic.co/elasticsearch/elasticsearch:8.15.5
docker run -d --name elasticsearch --network host \
  -e "discovery.type=single-node" \
  -e "ES_JAVA_OPTS=-Xms1g -Xmx1g" \
  -e "ELASTIC_PASSWORD=123456" \
  docker.elastic.co/elasticsearch/elasticsearch:8.15.5
2. Verify Service Status
curl -k -u elastic:123456 https://localhost:9200
Example response:
{
  "name" : "ab0b562f8dbd",
  "cluster_name" : "docker-cluster",
  "cluster_uuid" : "aVfOVgJTQXuhZ3HGotK3ww",
  "version" : {
    "number" : "8.15.5",
    "build_flavor" : "default",
    "build_type" : "docker",
    "build_hash" : "b10896bcfe167cce44a84ba2771d101fb596d40d",
    "build_date" : "2024-11-21T22:06:13.985834967Z",
    "build_snapshot" : false,
    "lucene_version" : "9.11.1",
    "minimum_wire_compatibility_version" : "7.17.0",
    "minimum_index_compatibility_version" : "7.0.0"
  },
  "tagline" : "You Know, for Search"
}
Add the following configuration to huatuo-bamai.conf. The default username for the Elasticsearch container image is elastic; the password is set via the ELASTIC_PASSWORD environment variable. For a full description of storage configuration options, see the Configuration Guide.
[Storage.Elasticsearch]
    Address = "https://127.0.0.1:9200"
    Index = "huatuo_bamai"
    Username = "elastic"
    Password = "123456"
4. Start huatuo-bamai
Use --config-dir to specify the directory containing the configuration file:
./_output/bin/huatuo-bamai --region dev --config-dir .
When files (e.g., net_rx_latency) appear in the local storage directory huatuo-local/, kernel events have been successfully captured. Query data from Elasticsearch with:
curl -k -u elastic:123456 \
  -X GET "https://localhost:9200/huatuo_bamai/_search?pretty" \
  -H "Content-Type: application/json" \
  -d '{"query": {"match_all": {}}}'
Example response:
{
    "_index" : "huatuo_bamai",
    "_id" : "WtNZAJ4BQ8x-thPHEY1i",
    "_score" : 1.0,
    "_source" : {
      "hostname" : "hostname",
      "region" : "dev",
      "uploaded_timestamp" : "2026-05-07T02:51:37.696263325Z",
      "tracer_name" : "net_rx_latency",
      "observed_timestamp" : "2026-05-07T02:51:37.696263325Z",
      "tracer_type" : "event",
      "tracer_data" : {
        "comm" : "<nil>",
        "pid" : 0,
        "latency_stage" : "RX_STAGE_NETIF",
        "latency_ms" : 1776078133565,
        "tcp_saddr" : "127.0.0.1",
        "tcp_daddr" : "127.0.0.1",
        "tcp_sport" : 2379,
        "tcp_dport" : 36706,
        "tcp_seq" : 950542706,
        "tcp_ack_seq" : 1960972383,
        "packet_len_bytes" : 91
      }
    }
}
To get the total document count without listing individual records:
curl -k -u elastic:123456 -X GET "https://localhost:9200/huatuo_bamai/_count?pretty"
Example response: the count value equals the total number of written records.
{
  "count" : 2680,
  "_shards" : {
    "total" : 1,
    "successful" : 1,
    "skipped" : 0,
    "failed" : 0
  }
}
Elasticsearch V7
Elasticsearch V7 uses HTTP by default. Replace https with http in all commands.
1. Deploy Elasticsearch
docker pull docker.elastic.co/elasticsearch/elasticsearch:7.10.1
docker run -d --name elasticsearch --network host \
  -e "discovery.type=single-node" \
  -e "ES_JAVA_OPTS=-Xms1g -Xmx1g" \
  -e "ELASTIC_PASSWORD=123456" \
  docker.elastic.co/elasticsearch/elasticsearch:7.10.1
2. Verify Service Status
curl -k -u elastic:123456 http://localhost:9200
Example response:
{
  "name" : "d88c9e8df48b",
  "cluster_name" : "docker-cluster",
  "cluster_uuid" : "_ZZefWx4SniAc255t_lIVg",
  "version" : {
    "number" : "7.10.1",
    "build_flavor" : "default",
    "build_type" : "docker",
    "build_hash" : "1c34507e66d7db1211f66f3513706fdf548736aa",
    "build_date" : "2020-12-05T01:00:33.671820Z",
    "build_snapshot" : false,
    "lucene_version" : "8.7.0",
    "minimum_wire_compatibility_version" : "6.8.0",
    "minimum_index_compatibility_version" : "6.0.0-beta1"
  },
  "tagline" : "You Know, for Search"
}
[Storage.Elasticsearch]
    Address = "http://127.0.0.1:9200"
    Index = "huatuo_bamai"
    Username = "elastic"
    Password = "123456"
4. Start huatuo-bamai
Use --config-dir to specify the directory containing the configuration file:
./_output/bin/huatuo-bamai --region dev --config-dir .
When files (e.g., net_rx_latency) appear in the local storage directory huatuo-local/, kernel events have been successfully captured. Query data from Elasticsearch with:
curl -k -u elastic:123456 \
  -X GET "http://localhost:9200/huatuo_bamai/_search?pretty" \
  -H "Content-Type: application/json" \
  -d '{"query": {"match_all": {}}}'
To get the total document count:
curl -k -u elastic:123456 -X GET "http://localhost:9200/huatuo_bamai/_count?pretty"
⚙️ How It Works
System Architecture
The HUATUO Storage module runs on each node. It writes kernel events captured by the Tracer to the local directory and to Elasticsearch or OpenSearch. Both backends share the same [Storage.Elasticsearch] configuration interface and are differentiated by address.
The remote write path uses the ES/OpenSearch Bulk API (_bulk): events are queued in an in-memory buffer and submitted in batches by background workers based on size and time thresholds, with transport-layer retries on transient failures.
graph TB
    subgraph kernel["Linux Kernel"]
        K1[Kernel Events]
        K2[AutoTracing]
    end

    subgraph huatuo["HUATUO Agent (node-level)"]
        T["Tracer Layer"]
        L["Local Directory\nhuatuo-local/"]
        S["Storage Module\nBulkIndexer Buffer"]
    end

    subgraph backends["Storage Backends"]
        ES[Elasticsearch]
        OS[OpenSearch]
    end

    kernel --> T
    T --> L
    T --> S
    S -->|Bulk API + auto retry| ES
    S -->|Bulk API + auto retry| OS
Filter semantics
The internal storage query API combines filters with AND. SQLite and
Elasticsearch share the following contract for non-null scalar values:
| Operator |
Meaning |
OpEq, OpNe |
Equal / not equal; missing and null values do not match |
OpGt, OpGte, OpLt, OpLte |
Strict / inclusive range bounds |
OpIn |
Membership in a non-empty slice or array of scalar values |
OpExists, OpNotExists |
Has / lacks a non-null queryable value; omit Value |
Empty strings are literal values: OpEq("") matches an empty string, while
OpNe("") requires an existing, non-null, non-empty string. To query missing
fields, use OpNotExists; OpEq("") no longer means field absence. Host profiling
queries use OpNotExists on container_hostname to preserve their selection.
Operands accept built-in string, boolean, integer, and finite floating-point
types. Range comparisons exclude booleans. time.Time and timeutil.Timestamp
are normalized to UTC strings with nine fractional digits, including in OpIn.
Nil, pointers, objects, nested collections, and non-finite numbers return
driver.ErrInvalidQuery. Integer range bounds retain their original JSON
precision; each backend’s supported numeric domain and field mapping still apply.
For Elasticsearch, callers must supply the exact indexed field: use the original
field for a keyword mapping, or an explicitly configured keyword subfield such
as hostname.keyword for a text mapping. The backend neither guesses subfields
nor combines text and keyword queries. OpNe applies exists and must_not term
to the same field. Full-text matching and array equality are outside this scalar
comparison contract.
Elasticsearch existence refers to indexed values, not _source key presence.
Mapping options such as ignore_above, null_value, and normalizers can change
existence or equality behavior. Use mappings that preserve the intended scalar
values when requiring equivalence with SQLite. A date field cannot be compared
to an empty string; use an existence operator when the intent is a populated date.
Write Flow
Save returns immediately after the event is buffered. Background workers flush the buffer to the remote backend when any of the following triggers fire: byte threshold, time threshold, or process shutdown. The local directory write is synchronous and independent of the remote Bulk path.
sequenceDiagram
    participant T as Tracer Layer
    participant L as Local Directory (huatuo-local/)
    participant S as Storage Module (BulkIndexer)
    participant B as ES / OpenSearch

    T->>S: Kernel event captured, serialized to JSON
    par Local path (sync)
        S->>L: Write to local file
    and Remote path (async batch)
        S->>S: Enqueue into bulk buffer, return immediately
        Note over S: Flush on 5 MB / 1 s / shutdown
        S->>B: POST /_bulk (multiple records)
        B-->>S: 200 OK + per-item results
        Note over S: Failed items reported via OnFailure callback
    end
Bulk Write Mechanism
Buffering and Flush Triggers
| Parameter |
Value |
Meaning |
FlushBytes |
5 MB |
Flush when accumulated bytes reach the threshold |
FlushInterval |
1 s |
Force-flush 1 second after the previous flush |
NumWorkers |
4 |
Concurrent workers submitting Bulk requests |
| Process shutdown |
Close(ctx) |
SIGTERM/SIGINT triggers a 10 s bounded drain |
Two-Tier Retry Policy
Bulk failures are split into two layers with different retry semantics:
| Layer |
Trigger |
Behavior |
Retried? |
| Whole-batch retry |
Transport error (connect / timeout / TLS)
HTTP status: 429 / 502 / 503 / 504 |
Client retries with exponential backoff: 100 ms → 200 ms → 400 ms → 800 ms, up to 3 attempts |
✅ auto |
| Whole-batch reject |
HTTP status: 400 / 401 / 403 / 404 / 413, etc. |
Not retried; all records in the batch are dropped, an error is logged via OnError |
❌ drop |
| Per-item failure |
200 OK with per-item error: version conflict, mapping error, document too large |
Not retried; only the failed item is dropped, OnFailure logs index/id/status/type/reason |
❌ drop |
| Per-item success |
200 OK with per-item success |
Primary write succeeded; replica failures produce a warning with index, document ID, and failed shard count |
— |
Why this design: 429/5xx and transport errors signal transient remote unavailability where retries are effective; 4xx (except 429) and per-item errors are client-side semantic issues (data shape, permissions) where retries would only amplify the failure — they should be surfaced via logs for human investigation.
Batched Reads
Query(ctx, query, consume) calls the consumer synchronously for each nonempty
batch. Limit caps the total records delivered after Offset matching records
are skipped. storage.Store.Query requires a positive Limit and non-negative
Offset and BatchSize before calling a backend; backends consume validated input.
BatchSize controls each batch, defaults to 100 when zero, and is capped by the
remaining total. Callers must supply a positive total limit when they need data.
Count and Values use only Filters from the query and ignore Sorts, Limit,
Offset, and BatchSize, including zero and negative pagination values. Count
counts all matching records. Values uses its separate size argument, whose
non-negative constraint is checked by storage.Store.Values before dispatch;
backends do not repeat pagination or size validation for these operations.
Local file storage remains write-only.
SQLite streams one SELECT ... LIMIT ... OFFSET ... through rows. A consumer
must not query the same SQLite backend synchronously while rows hold its single
connection. Job recovery reads 1000 Jobs at a time using ascending IDs, then
starts their supervisors after the read closes; status changes cannot shift the
next page. Elasticsearch 7/8 and OpenSearch use Scroll snapshots, including for
offsets beyond the result window. Deep offsets still require reading and
skipping earlier records. Separate API calls do not share a snapshot.
Each batch has independent ownership. Callback errors, decoding errors, backend
errors, and cancellation stop the query immediately; earlier callback effects
are not rolled back. Scroll cleanup uses a separate bounded context even after
cancellation. Query requests are not retried because a lost Scroll response may
already have advanced the cursor. Write retry behavior is unchanged.
API defaults apply only when limit is omitted: Job lists default to 100 with a
maximum of 1000; raw Profile pages default to 20 with a maximum of 100 and retain
the 64 MiB response budget. Explicit zero, negative, or oversized limits are rejected. One additional
record is fetched to determine has_more.
Profile flamegraphs merge batches as they arrive, with a total budget of 100000
windows. One extra record detects overflow and rejects the query with an
instruction to narrow its time range or filters. Read or merge failure never
returns a partial flamegraph. Input batches can be released as processing
advances; the merged profile still grows with distinct stacks.
Response Errors
HTTP success does not guarantee a complete result. Query and Values return
an error when a search times out or a shard fails. Query stops before
delivering the failing page; already consumed batches remain consumed. Values
does not return partial results.
Count returns zero and an error on shard failure. A search timeout takes
precedence over shard failures. Shard errors include the failed shard count and
the first failure’s available type, reason, and nested causes.
After an HTTP success response, DeleteByQuery checks for timeouts and failures
in that order and returns the first error with the reported deleted count. HTTP errors
return zero and an error, except that a missing index returns zero without an error.
Any completed deletions are not rolled back.
Direct writes and deletes retain primary-operation success when replicas fail;
they log a warning with the available failure details. Bulk writes also report
replica failures through warnings, without retrying the successful primary write.
HTTP errors include the response status and available Elasticsearch error details.
Unrecognized or oversized error bodies are reported as text, limited to 4 KiB
plus a truncation marker.
Data-Loss Scenarios
In all three scenarios below, Save returns nil but the event never reaches the index:
- Abnormal process exit:
SIGKILL or host power loss drops whatever is still buffered in the BulkIndexer (the local directory still keeps a copy).
- Mitigation: SIGTERM/SIGINT trigger graceful shutdown;
Close force-flushes the buffer with a 10 s deadline.
- Whole-batch permanent rejection: 4xx (non-429) errors discard every record in the batch. Common causes: disabled index, expired credentials, document exceeding the cluster’s
http.max_content_length.
- Diagnosis:
OnError log includes ES’s type and reason.
- Permanent per-item failure: mapping conflict, version conflict, malformed document.
- Diagnosis:
OnFailure log identifies the record by index/id.
The local directory is always a fallback: even if remote writes are lost, events remain available in huatuo-local/ as the eventual-consistency safety net.
Problems This Solves
Replacing per-event Index API calls with a buffered BulkIndexer + auto-retry addresses four classes of problems:
| Problem |
Old approach bottleneck |
Bulk approach improvement |
| TLS handshake CPU cost |
One HTTPS handshake per event saturated CPU under FIPS/RSA-PSS |
Many events share one connection and one handshake; TLS PSK tickets cached |
| Remote RTT throughput ceiling |
One round-trip per event capped node-level write rate |
One Bulk request carries up to 5 MB; throughput scales with batch size |
| Transient remote jitter / 429 throttle |
A single failure dropped the event with no retry |
Client-level retry absorbs short-lived faults |
| Decoupling tracer layer from backend |
Slow remote backed pressure into capture, delaying tracing |
Async buffer decouples capture from network — capture is no longer blocked on remote latency |
🌟 Stay Connected
Kernel observation time
Event documents can include a top-level kernel_observed_timestamp containing
a UTC date-time. observed_timestamp is userspace observation time, and
uploaded_timestamp is storage write time. These fields do not fill one
another. Older documents and events without kernel timestamps omit the new
field; historical data is not migrated automatically. The raw
kernel_observed_ns stays in process for correlation and is not
written to new documents.
6.2 - Data Source
HUATUO integrates with Prometheus for metrics collection and Elasticsearch for log storage. This document covers data source configuration and dashboard provisioning in Grafana.
Two deployment paths are supported:
- Docker Compose — recommended for development and testing; all components are pre-configured.
- Kubernetes — for production clusters; requires manual data source configuration.
Quick Start (Docker Compose)
The build/docker/ directory contains a complete stack. All default credentials and ports listed below match this setup.
cd build/docker
docker compose up -d
This starts four services on the host network:
| Service |
Port |
Purpose |
| Elasticsearch |
9200 |
Log storage |
| Prometheus |
9090 |
Metrics collection |
| Grafana |
3000 |
Visualization |
| huatuo-bamai |
19704 |
Agent (metrics + tracing) |
Default credentials:
| Service |
Username |
Password |
| Elasticsearch |
elastic |
huatuo-bamai |
| Grafana |
admin |
admin |
Data sources and dashboards are auto-provisioned. Access Grafana at http://<host>:3000.
Verify the Stack
# Elasticsearch
curl -s -u elastic:huatuo-bamai http://localhost:9200/_cluster/health?pretty

# Prometheus — should show huatuo target as "up"
curl -s http://localhost:9090/api/v1/targets | jq '.data.activeTargets[] | {job: .labels.job, health: .health}'

# Grafana
curl -s http://localhost:3000/api/health | jq .version

# HuaTuo metrics
curl -s http://localhost:19704/metrics | head -5
Provisioned Data Sources
The following data sources are created automatically via build/docker/grafana/datasources/:
| Name |
Type |
UID |
| huatuo-bamai-prom |
Prometheus |
huatuo-bamai-prom |
| huatuo-bamai-es |
Elasticsearch |
huatuo-bamai-es |
| huatuo-bamai-infinity |
Infinity |
huatuo-bamai-infinity-auto-flamegraph |
Provisioned Dashboards
Six dashboards are loaded from build/docker/grafana/dashboards/:
- Metric Dashboard — Host View
- Metric Dashboard — Container View
- HuaTuo Root Cause Analysis AutoTracing
- Continuous Profiling (Host)
- Continuous Profiling (Container)
- AutoTracing Flame Redirect
No manual import is needed when using Docker Compose.
Metrics Collection (Kubernetes)
1. Verify Metrics Endpoint
After deploying huatuo-bamai to Kubernetes, expose the metrics endpoint:
kubectl port-forward -n default --address=0.0.0.0 pod/huatuo-XXXX 19704:19704
Verify:
curl http://localhost:19704/metrics
Metrics output confirms the agent is running correctly.
Option A: Pod Annotations
Add annotations to the Pod template metadata. This requires a Prometheus setup with Kubernetes pod service discovery enabled (e.g., kubernetes_sd_configs with role: pod).
template:
    metadata:
      annotations:
        prometheus.io/scrape: "true"
        prometheus.io/port: "19704"
        prometheus.io/path: "/metrics"
Option B: ServiceMonitor
Requires Prometheus Operator. Create two resources:
huatuo-service.yaml:
apiVersion: v1
kind: Service
metadata:
  name: huatuo
  labels:
    app: huatuo
spec:
  clusterIP: None
  ports:
    - name: metrics
      port: 19704
      targetPort: 19704
      protocol: TCP
  selector:
    app: huatuo
huatuo-servicemonitor.yaml:
apiVersion: monitoring.coreos.com/v1
kind: ServiceMonitor
metadata:
  name: huatuo
  namespace: default
  labels:
    release: prometheus
spec:
  namespaceSelector:
    matchNames:
      - default
  selector:
    matchLabels:
      app: huatuo
  endpoints:
    - port: metrics
      path: /metrics
      interval: 30s
      scrapeTimeout: 10s
3. Query Metrics in Prometheus
If results are returned, metrics collection is working properly.
Log Collection (Kubernetes)
Query logs from Elasticsearch:
curl -u elastic:<password> "http://<es-host>:9200/huatuo_bamai/_search?pretty"
Replace <password> and <es-host> with your Elasticsearch credentials and address.
Manual Grafana Data Source Configuration
When not using Docker Compose (e.g., external Grafana), configure data sources manually.
Prometheus Data Source
Refer to build/docker/grafana/datasources/prometheus.yaml for the provisioning file, or configure via Grafana UI:
- URL:
http://<prometheus-host>:9090
- Access: Server (proxy)
Elasticsearch Data Source
Configure via Grafana UI or provisioning:
- URL:
http://<es-host>:9200
- Authentication: Basic Authentication
- Username:
elastic
- Password:
<your-elasticsearch-password>
- Index name:
huatuo_bamai
- Time field name:
uploaded_timestamp
Dashboard Import
When using Docker Compose, dashboards are provisioned automatically. To import additional dashboards from the HUAUO console:
- Access
http://console.huatuo.tech/dashboards (Username: huatuo, Password: huatuo1024)
- Select the desired dashboard
- Click Export -> Export as JSON
- Check “Export the dashboard to use in another instance”
- Click Copy to clipboard
Then in your Grafana instance:
- Navigate to Dashboards -> Import
- Paste the JSON content
- Click Load
- Select the correct data sources and click Import
Troubleshooting
“datasource not found” when importing dashboard
This occurs when the dashboard JSON references a datasource UID that does not exist in your Grafana instance.
Solution:
- Find your Elasticsearch datasource UID from the Grafana UI URL:
http://<grafana-host>:3000/connections/datasources/edit/<uid>
- In the dashboard JSON, replace all occurrences of
"uid": "${DS_HUATUO-BAMAI-ES}" with your actual UID
- Re-import the dashboard
Prometheus target shows “down”
- Verify huatuo-bamai is running:
curl http://<host>:19704/metrics
- Check Prometheus configuration matches the agent’s address and port
- For Kubernetes: ensure pod annotations are correct or ServiceMonitor selector matches
Elasticsearch index is empty
- Verify Elasticsearch is reachable:
curl -u elastic:<password> http://<host>:9200/_cat/indices
- Check huatuo-bamai config
[Storage.ES] section has correct Address, Username, Password
- Default index name is
huatuo_bamai
“socket path already exists” on startup
This occurs when a previous huatuo-bamai process was not cleanly stopped.
Solution:
rm -f /var/run/huatuo-toolstream.sock
6.3 - Events Watch
🎯 About HUATUO
HUATUO is an operating system observability project open-sourced by DiDi and incubated under CCF (China Computer Federation). It provides kernel-level deep observability for cloud-native general computing, AI computing, cloud services, and foundational services.
📖 Overview
/v1/events/watch is HUATUO’s real-time kernel event subscription endpoint. A single HTTP POST long-lived connection streams kernel anomaly events from the node continuously. Events are wrapped in the CloudEvents 1.0 specification and delivered via the Server-Sent Events (SSE) protocol.
🎯 Use Cases
Kernel event subscription surfaces OS-level anomaly signals directly to higher-level systems, eliminating the latency and overhead of traditional polling. The following are typical integration scenarios.
Fault Self-Healing
Kernel events are the primary signal source for self-healing decisions. After subscribing to events/watch, a healing controller can trigger remediation the moment an event occurs, without waiting for an alert to propagate through a monitoring pipeline:
- OOM self-healing: On receiving a
memory_oom_kill event, immediately scale, restart, or drain traffic from the triggering container. Reduces service interruption from minutes to seconds.
- Hung task self-healing: On receiving a
hungtask event, automatically cordon the node and evict Pods to prevent cascading blockage from spreading across the cluster.
- Network fault self-healing: On receiving a
netdev_txqueue_timeout or netdev_bonding_lacp event, trigger a NIC reset or traffic failover to restore the network link within minutes.
- I/O storm self-healing: On receiving an
iotracing event, dynamically throttle the affected container’s disk I/O quota via cgroup blkio to protect co-located services on the same node.
Integrating HUATUO kernel events into an observability platform adds a kernel-level perspective beyond application metrics and logs:
- Event timeline correlation: Overlay
softlockup, memory_oom_kill, and other kernel events onto Grafana timelines, aligning them precisely with application error rates and latency curves for root-cause analysis.
- Anomaly-driven alerting: Replace fixed-threshold alerts with kernel events to reduce false positives. For example, a
ras hardware error event triggers a high-priority alert directly, without relying on a CPU error rate crossing a threshold.
- Capacity and stability analysis: Subscribe to
memburst, dload, and other AutoTracing events over time to establish a node stability baseline and provide kernel-level data for capacity planning.
- Multi-dimensional drill-down: Events carry container ID, namespace, region, and other context fields. Alert links can drill down directly to the corresponding Pod, Node, or Region view.
Security Auditing and Compliance
- Anomalous behavior detection: A cluster of
memory_oom_kill, hungtask, or softlockup events outside business peak hours may indicate resource abuse or a malicious workload, triggering a security review workflow.
- Event retention and traceability: Write the CloudEvents stream to a message queue (Kafka, Pulsar) or object storage to satisfy the event retention requirements of security compliance frameworks.
Chaos Engineering and Load Testing
- Fault injection verification: After injecting network latency or memory pressure via a chaos engineering platform, subscribe to
net_rx_latency and memburst events in real time to verify the fault is active, replacing manual observation.
- Load test baseline: Subscribe to all events during a load test. The timestamp of the first kernel anomaly event precisely marks the system’s stress threshold.
AIOps
- Event-driven root-cause analysis: Feed kernel events as features into AI/ML models alongside application metrics for multi-dimensional root-cause inference, reducing manual investigation time.
- Predictive maintenance: Model
ras hardware errors and netdev_bonding_lacp hardware-layer events to detect anomalies before a device fails completely, triggering proactive migration.
- Intelligent suppression and aggregation: Automatically aggregate similar events within the same time window to avoid alert storms. Deliver a concise root-cause summary to on-call engineers.
💎 Value
| Dimension |
Traditional Approach |
With HUATUO events/watch |
| Timeliness |
Alert trigger latency: 1–5 minutes |
Real-time kernel event push; latency < 1 s |
| Signal accuracy |
Metric threshold-based; high false-positive rate |
Events originate from kernel decisions; false-positive rate near zero |
| Context richness |
Limited metric dimensions |
Full context: container, node, region, and more |
| Integration cost |
Requires custom eBPF collection or a third-party agent |
Single HTTP POST to subscribe; standard CloudEvents format |
| Protocol compatibility |
Vendor-specific formats |
Follows CloudEvents 1.0; compatible with any conformant platform |
🚀 Usage
1. CloudEvents Specification
1.1 CloudEvents 1.0 Envelope Fields
Each pushed event is a JSON object conforming to the CloudEvents 1.0 specification:
| Field |
Type |
Description |
specversion |
string |
Fixed value "1.0" |
id |
string |
Unique event identifier (UUID v4), generated independently per event |
source |
string |
Event source path, format: /huatuo/{hostname}/{tracer_name} |
type |
string |
Fixed value "tech.huatuo.kernel.event" |
datacontenttype |
string |
Fixed value "application/json" |
time |
string |
Event collection timestamp (RFC 3339, nanosecond precision, UTC) |
data |
object |
Event payload — the WatchEventData struct |
1.2 HUATUO Event Payload (WatchEventData)
The data field contains the standard HUATUO event record:
{
  "specversion": "1.0",
  "id": "f47ac10b-58cc-4372-a567-0e02b2c3d479",
  "source": "/huatuo/node-1/memory_oom_kill",
  "type": "tech.huatuo.kernel.event",
  "datacontenttype": "application/json",
  "time": "2026-05-18T10:23:45.123456789Z",
  "data": {
    "hostname": "node-1",
    "region": "cn-beijing",
    "observed_timestamp": "2026-05-18T10:23:45Z",
    "tracer_name": "memory_oom_kill",
    "tracer_id": "abc123",
    "tracer_run_type": "auto",
    "container_id": "d3f1a2b4c5e6",
    "container_hostname": "app-pod",
    "container_host_namespace": "prod",
    "container_type": "docker",
    "container_qos": "guaranteed"
  }
}
WatchEventData field reference:
| Field |
Type |
Description |
hostname |
string |
Node hostname |
region |
string |
Region where the node is located |
observed_timestamp |
string |
UTC time when the event producer observed the event in userspace |
kernel_observed_timestamp |
string |
Optional UTC time when the kernel observed the event |
tracer_name |
string |
Name of the tracer that triggered the event (see the event list below) |
tracer_id |
string |
Unique ID of this event instance |
tracer_run_type |
string |
Collection mode: auto (triggered automatically) or manual |
container_id |
string |
Container ID (present for container-level events) |
container_hostname |
string |
Container hostname |
container_host_namespace |
string |
Namespace of the container |
container_type |
string |
Container runtime type (docker, containerd, etc.) |
container_qos |
string |
Container QoS class (unknown, guaranteed, burstable, or besteffort) |
2. Supported Kernel Events
tracer_name |
Description |
memory_oom_kill |
Out-of-memory (OOM Killer) triggered event |
hungtask |
Kernel task stuck in D state (Hung Task) detection |
softlockup |
CPU soft lockup detection |
ras |
Hardware reliability (RAS) errors, such as ECC memory errors |
dropwatch |
Kernel network packet drop (Drop Watch) events |
netdev_events |
Network device state change events (Link Up/Down, etc.) |
netdev_txqueue_timeout |
Network device transmit queue timeout events |
netdev_bonding_lacp |
Bond device LACP protocol anomaly events |
net_rx_latency |
Network receive latency anomaly events |
sched_tick |
Scheduler tick interval tracing events |
memory_reclaim_events |
Memory reclaim anomaly events |
cpuidle |
CPU idle rate anomaly (AutoTracing, auto-triggered) |
cpusys |
CPU system-mode usage anomaly (AutoTracing, auto-triggered) |
dload |
System load anomaly (AutoTracing, auto-triggered) |
iotracing |
I/O latency anomaly (AutoTracing, auto-triggered) |
memburst |
Memory usage spike anomaly (AutoTracing, auto-triggered) |
3. POST Request Reference
3.1 Endpoint
Authorization: Bearer <node-token>
Content-Type: application/json
3.3 Request Body
{
  "filters": {
    "tracer_name": "<regex>",
    "hostname": "<regex>",
    "container_hostname": "<regex>",
    "container_host_namespace": "<regex>",
    "container_qos": "<regex>",
    "region": "<regex>"
  }
}
filters field reference:
| Field |
Type |
Required |
Description |
tracer_name |
string |
No |
Filter by tracer name; supports regular expressions |
hostname |
string |
No |
Filter by node hostname; supports regular expressions |
container_hostname |
string |
No |
Filter by container hostname; supports regular expressions |
container_host_namespace |
string |
No |
Filter by container namespace; supports regular expressions |
container_qos |
string |
No |
Filter by container QoS; supports regular expressions |
region |
string |
No |
Filter by region; supports regular expressions |
- All filter fields are optional. Omitting or leaving a field empty matches all values.
- When multiple fields are specified, all conditions must be satisfied simultaneously (AND semantics).
- Filters are evaluated server-side; only matching events are pushed to the client.
After the connection is established, the server continuously pushes events in SSE format:
data: {"specversion":"1.0","id":"...","source":"/huatuo/node-1/memory_oom_kill",...}\n\n
The server also sends periodic heartbeat comment lines to keep the connection alive:
4. HTTP Server Event Stream Configuration
Configure the event stream controls under [HTTPServer]:
[HTTPServer]
    # Maximum number of concurrent client connections. New connections receive HTTP 429 when the limit is reached.
    # Default: 100
    MaxEventStreamClients = 100

    # SSE heartbeat interval in seconds. Prevents proxies and load balancers from closing idle connections.
    # The connection is closed after three consecutive heartbeat write failures.
    # Default: 30
    EventStreamKeepAliveIntervalSeconds = 30
| Field |
Default |
Description |
MaxEventStreamClients |
100 |
Maximum concurrent /v1/events/watch connections. Excess connections receive HTTP 429. |
EventStreamKeepAliveIntervalSeconds |
30 |
Heartbeat interval. Keep it below the upstream proxy’s idle timeout. |
5. curl Examples
5.1 Subscribe to All Kernel Events
curl -s -N -X POST http://<node-ip>:19704/v1/events/watch \
  -H "Authorization: Bearer <node-token>" \
  -H "Content-Type: application/json" \
  -H "Accept: text/event-stream" \
  -H "Cache-Control: no-cache" \
  -H "Connection: keep-alive" \
  -d '{}'
5.2 Subscribe to OOM Events Only
curl -s -N -X POST http://<node-ip>:19704/v1/events/watch \
  -H "Authorization: Bearer <node-token>" \
  -H "Content-Type: application/json" \
  -H "Accept: text/event-stream" \
  -H "Cache-Control: no-cache" \
  -H "Connection: keep-alive" \
  -d '{"filters": {"tracer_name": "^memory_oom_kill$"}}'
5.3 Subscribe to Network Events on a Specific Node
curl -s -N -X POST http://<node-ip>:19704/v1/events/watch \
  -H "Authorization: Bearer <node-token>" \
  -H "Content-Type: application/json" \
  -H "Accept: text/event-stream" \
  -H "Cache-Control: no-cache" \
  -H "Connection: keep-alive" \
  -d '{
    "filters": {
      "hostname": "^node-1$",
      "tracer_name": "netdev|dropwatch|net_rx_latency"
    }
  }'
5.4 Subscribe to Container Events in the prod Namespace
curl -s -N -X POST http://<node-ip>:19704/v1/events/watch \
  -H "Authorization: Bearer <node-token>" \
  -H "Content-Type: application/json" \
  -H "Accept: text/event-stream" \
  -H "Cache-Control: no-cache" \
  -H "Connection: keep-alive" \
  -d '{
    "filters": {
      "container_host_namespace": "^prod$"
    }
  }'
Note: The -N flag disables curl buffering, causing SSE events to be printed to the terminal immediately.
6. Generated Go Client Example
POST /v1/events/watch is part of the Node OpenAPI contract. The generated
client supplies the request and event types used below.
package main

import (
	"bufio"
	"context"
	"encoding/json"
	"fmt"
	"log/slog"
	"net/http"
	"os"
	"strings"
	"time"

	nodeapi "github.com/ccfos/huatuo/apis/v1/node"
)

func watchEvents(
	ctx context.Context,
	baseURL string,
	token string,
	filters nodeapi.WatchEventFilters,
) error {
	client, err := nodeapi.NewClient(
		baseURL,
		nodeapi.WithHTTPClient(&http.Client{}),
		nodeapi.WithRequestEditorFn(func(_ context.Context, request *http.Request) error {
			request.Header.Set("Authorization", "Bearer "+token)
			request.Header.Set("Accept", "text/event-stream")
			return nil
		}),
	)
	if err != nil {
		return fmt.Errorf("create Node API client: %w", err)
	}
	resp, err := client.WatchEvents(ctx, nodeapi.WatchEventsJSONRequestBody{
		Filters: &filters,
	})
	if err != nil {
		return fmt.Errorf("connect: %w", err)
	}
	defer resp.Body.Close()

	if resp.StatusCode != http.StatusOK {
		return fmt.Errorf("unexpected status: %d", resp.StatusCode)
	}

	scanner := bufio.NewScanner(resp.Body)
	for scanner.Scan() {
		line := scanner.Text()

		// skip heartbeat comment lines and blank lines
		if line == "" || strings.HasPrefix(line, ":") {
			continue
		}

		// SSE data line format: `data: <json>`
		data, ok := strings.CutPrefix(line, "data: ")
		if !ok {
			continue
		}

		var event nodeapi.WatchEvent
		if err := json.Unmarshal([]byte(data), &event); err != nil {
			slog.Warn("parse event", "err", err)
			continue
		}

		fmt.Printf(
			"[%s] source=%s id=%s\n",
			event.Time.Format(time.RFC3339Nano),
			event.Source,
			event.ID.String(),
		)
		fmt.Printf("  data: %+v\n", event.Data)
	}

	return scanner.Err()
}

func main() {
	ctx, cancel := context.WithTimeout(context.Background(), 5*time.Minute)
	defer cancel()

	tracerName := "memory_oom_kill|hungtask|softlockup"
	err := watchEvents(ctx, "http://192.168.1.10:19704", "node-token", nodeapi.WatchEventFilters{
		TracerName: &tracerName,
	})
	if err != nil {
		slog.Error("watch events", "err", err)
		os.Exit(1)
	}
}
6.1 Streaming Client Selection
Use the generated Client.WatchEvents method, which returns the raw
http.Response. Do not use ClientWithResponses.WatchEventsWithResponse for
this endpoint: that helper reads the body to EOF, while an SSE stream normally
remains open until its context is canceled.
6.2 Reconnection
In production, network interruptions or service restarts will drop the connection. Use exponential backoff to reconnect:
func watchWithRetry(
	ctx context.Context,
	baseURL string,
	token string,
	filters nodeapi.WatchEventFilters,
) {
	backoff := time.Second
	for {
		if err := watchEvents(ctx, baseURL, token, filters); err != nil {
			if ctx.Err() != nil {
				return
			}
			slog.Warn("disconnected, retrying", "err", err, "backoff", backoff)
			// time.NewTimer + Stop releases the timer immediately when the context is cancelled
			timer := time.NewTimer(backoff)
			select {
			case <-ctx.Done():
				timer.Stop()
				return
			case <-timer.C:
			}
			if backoff < 30*time.Second {
				backoff *= 2
			}
		}
	}
}
⚙️ How It Works
Architecture
HUATUO Agent runs on each node. It hooks into critical kernel paths via eBPF, Kprobe, and Tracepoint, collects kernel anomaly events, applies filters, wraps them as CloudEvents, and pushes them to multiple concurrent SSE subscribers.
graph TB
    subgraph kernel["Linux Kernel"]
        K1[OOM Killer]
        K2[Hung Task Detection]
        K3[Soft Lockup Detection]
        K4[RAS Hardware Errors]
        K5[Network Subsystem]
        K6[AutoTracing]
    end

    subgraph huatuo["HUATUO Agent (per node)"]
        T["Tracer Collection Layer\neBPF / Kprobe / Tracepoint"]
        F["Filter\nhostname / tracer / namespace / region"]
        CE["CloudEvents 1.0 Wrapper\nid / source / time / data"]
        EW["EventsWatch Dispatcher\nSSE connection management"]
    end

    subgraph clients["Subscribers"]
        C1[Fault Self-Healing System]
        C2[Observability Platform]
        C3[AIOps System]
        C4[Security Audit System]
    end

    kernel --> T
    T --> F
    F --> CE
    CE --> EW
    EW -->|SSE push| C1
    EW -->|SSE push| C2
    EW -->|SSE push| C3
    EW -->|SSE push| C4
Event Collection and Push
After the client issues a POST request, the connection stays open. Each time the kernel triggers an anomaly event, HUATUO Agent filters and wraps it, then writes it immediately to all matching SSE streams. No client polling is required.
sequenceDiagram
    participant C as Client
    participant EW as EventsWatch
    participant T as Tracer Layer
    participant K as Linux Kernel

    C->>EW: POST /v1/events/watch {"filters": {...}}
    EW-->>C: 200 OK (Content-Type: text/event-stream)

    loop SSE long-lived connection
        K->>T: Kernel event triggered (memory_oom_kill / hungtask / softlockup ...)
        T->>EW: Report raw event
        EW->>EW: Apply filter
        alt Filter matched
            EW-->>C: data: {CloudEvents JSON}\n\n
        else No match
            note over EW: Discard, do not push
        end
        EW-->>C: : ping (keepalive, configured interval)
    end
Event Processing Pipeline
From kernel event generation to client delivery, three stages are involved: collection, filtering, and wrapping. End-to-end latency is under 1 second.
flowchart LR
    A([Kernel anomaly triggered]) --> B["Tracer collection\neBPF / Kprobe"]
    B --> C{Filter matched?}
    C -- No --> D([Discard])
    C -- Yes --> E["Wrap as CloudEvents 1.0\nid / source / time / data"]
    E --> F[Write to SSE stream]
    F --> G([Push to subscribers])
🌟 Stay Connected
6.4 - Profiling
In profiling, collapsed and flamegraph are the two most common formats, corresponding to the “raw data” and “visual view” layers respectively.
The collapsed format (also called folded stacks) was defined by Brendan Gregg and serves as the raw text input format for flame graphs. Each line represents a unique call stack and its sample count.
Basic rule:
frame1;frame2;frame3;...;frameN COUNT
| Component |
Description |
frame1 |
Stack bottom (entry/root frame), e.g. main, start_thread |
; |
Frame separator (semicolon) |
frameN |
Stack top (currently executing frame, i.e. the sampled point) |
COUNT |
Sample count (integer), separated from the stack frames by a space |
Format details:
- One unique call stack per line; samples with the same stack path have their counts merged
- Frame order: left to right is root → leaf (call chain direction)
- Blank lines and lines starting with
# are treated as comments and ignored during parsing
- The semantics of COUNT depend on the analysis mode: for CPU sampling it is the number of samples, for memory allocation it is the number of bytes allocated, for lock analysis it is the contention time in milliseconds
Frame Name Normalization
Collapsed/folded uses ; as the frame separator and has no standard escape
syntax. To prevent symbol names from being split into extra frames, HUATUO:
- Replaces
; in frame names with :
- Replaces carriage returns and line feeds with spaces so each stack occupies one line
- Applies these changes only to collapsed/folded output; internal symbols and structured formats retain the original names
For example, generic::<[u8; 7]> is written as generic::<[u8: 7]>.
This conversion is lossy: symbols that differ only by ; and : are merged. Use
pprof or another structured format when exact symbol names must be preserved.
Extended specification:
Some profiling tools (e.g. async-profiler) add frame type annotations on top of the standard format to identify the runtime category of a frame:
| Annotation |
Meaning |
Description |
_[j] |
JIT compiled Java |
Java method after JIT compilation |
_[i] |
Interpreted Java |
Java method executed by the interpreter |
_[k] |
Kernel |
Kernel-mode frame |
_[n] |
Native C/C++ |
Native C/C++ frame |
_[t] |
Thread |
Thread frame |
Additionally, some tools support a weighted collapsed format for differential flame graphs:
frame1;frame2;frameN WEIGHT
Where WEIGHT is a floating-point number representing the weight of the stack rather than a simple count.
Sample Examples
CPU profiling example (data from the async-profiler official documentation):
FileConverter.main;FileConverter.convertFile;FileConverter.saveResult 21
FileConverter.main;FileConverter.convertFile;FileConverter.saveResult;java/io/DataOutputStream.writeInt 1
FileConverter.main;FileConverter.convertFile;FileConverter.saveResult;java/io/DataOutputStream.writeInt;java/io/ByteArrayOutputStream.write 5
FileConverter.main;FileConverter.convertFile;FileConverter.saveResult;java/io/DataOutputStream.writeUTF;java/io/DataOutputStream.writeUTF 12
FileConverter.main;FileConverter.convertFile;FileConverter.saveResult;java/io/DataOutputStream.writeUTF;java/io/DataOutputStream.writeUTF;java/lang/String.length 3
FileConverter.main;FileConverter.convertFile;FileConverter.saveResult;java/io/DataOutputStream.writeUTF;java/io/DataOutputStream.writeUTF;java/io/DataOutputStream.write 6
start_thread;thread_native_entry;Thread::call_run;VMThread::run;VMThread::inner_execute;VMThread::evaluate_operation;VM_Operation::evaluate;VM_GenCollectForAllocation::doit;GenCollectedHeap::satisfy_failed_allocation;GenCollectedHeap::do_collection;GenCollectedHeap::collect_generation;DefNewGeneration::collect;DefNewGeneration::FastEvacuateFollowersClosure::do_void 12
Example with frame type annotations (async-profiler extension):
Main.run_[j];Service.process_[j];DAO.query_[j];mysql_real_query_[n] 45
Main.run_[j];Service.process_[j];DAO.query_[j];recv_[k] 18
Core Use Cases
| Use Case |
Description |
| Flame graph generation |
Standard input format for visualization tools like flamegraph.pl and inferno |
| Differential analysis |
Compare two collapsed files to produce a red-blue differential flame graph for detecting performance regressions |
| Programmatic processing |
Plain text format suitable for custom aggregation and filtering with awk, sed, Python, etc. |
| Cross-tool interoperability |
Universal standard defined by Brendan Gregg; supported by virtually all flame graph toolchains |
| Long-term storage |
Compact text format suitable for archiving and version comparison |
| CI/CD integration |
Enables automated collection, diffing, and threshold-based regression detection in pipelines |
Generation command example:
# Using async-profiler as an example
asprof -d 30 -f profile.collapsed -o collapsed <PID>
The flamegraph format is a self-contained HTML file with embedded SVG visualization and JavaScript interaction logic, which can be opened directly in a browser.
Structural composition:
flamegraph.html
├── HTML skeleton + CSS styles
├── SVG flame graph body
│   ├── <g> rectangle block for each frame
│   │   ├── <title> frame name + sample count/percentage
│   │   └── <rect> position, width, height, color
│   └── ...
├── JavaScript interaction logic
│   ├── Click to zoom (zoom into subtree)
│   ├── Search & highlight
│   ├── Tooltip on hover
│   └── Reset zoom
└── Metadata (title, total samples, etc.)
Visual encoding rules:
| Dimension |
Encoding Meaning |
| X axis |
Call stack frames sorted alphabetically (not a timeline); width proportional to sample count |
| Y axis |
Call stack depth; bottom is the root frame, top is the leaf frame |
| Frame width |
Proportion of samples where this frame appears in the stack; wider frames consume more resources |
| Frame color |
Identifies the frame type (see table below) |
Frame color specification (based on async-profiler):
Note: Flame graph color schemes are not a cross-tool standard. The original flamegraph.pl by Brendan Gregg uses random warm tones with no semantic meaning; perf/bpftrace typically colors by DSO or uses random colors; async-profiler colors by frame type semantics. The following is the async-profiler color specification:
| Color |
Frame Type |
Description |
| 🟢 Green |
Java (interpreted) |
Java method executed by the interpreter |
| 🟡 Yellow/Orange |
Java (JIT compiled) |
Java method after JIT compilation |
| 🔴 Red |
C/C++ (native) |
Native C/C++ code |
| 🔵 Blue |
Kernel |
Kernel-mode code |
| ⬜ Gray |
Other/Unknown |
Other types or unknown frames |
Extended features (based on async-profiler):
- Icicle Graph: Displays the call chain top-down (root at the top), which better suits top-down reading habits. Toggle via the
--reverse option or the Reverse button in the browser
- Multi-thread view: Call stacks from different threads are displayed side by side at the root level
- Search highlighting: Matching frames are highlighted in purple; non-matching frames are dimmed
- Sample info tooltip: Hover to display frame name, sample count, and percentage of total samples
- Cutoff frames: Frames marked as
[...] indicate stack truncation (e.g. due to stack depth limits)
Sample Examples
Generation command example:
# Using async-profiler as an example
asprof -d 30 -f flamegraph.html <PID>
Interactive operations:
- Click a frame: Zoom to make the frame full-width, showing only its subtree
- Search box: Enter a keyword; matching frames are highlighted
- Hover: Display frame name, sample count, and percentage
- Reset Zoom: Restore the global view
Core Use Cases
| Use Case |
Description |
| Hotspot identification |
Visually identify the widest frame blocks to quickly find the code paths consuming the most CPU/memory |
| Root cause analysis |
Trace upward from leaf frames to understand the call chain context of resource consumption |
| Team collaboration |
HTML files can be shared directly; viewable in a browser with no additional tools required |
| Optimization verification |
Generate flame graphs before and after optimization; compare frame width changes to verify effectiveness |
| Non-specialist friendly |
Visual form is easier to understand for non-performance engineers, facilitating cross-team communication |
| Dimension |
Collapsed |
Flamegraph |
| Format type |
Plain text |
HTML + SVG |
| Human readability |
Medium (requires understanding stack frame syntax) |
High (visual, intuitive) |
| Machine readability |
High (easy to parse, easy to diff) |
Low (requires parsing HTML/SVG) |
| Interactivity |
None |
Supports zoom, search, tooltip |
| File size |
Very small (KB scale) |
Larger (hundreds of KB to MB scale) |
| Toolchain dependency |
None (plain text) |
Browser |
| Differential analysis |
Natively supported (diff two files) |
Requires conversion to collapsed first |
| Typical use case |
Programmatic processing, CI comparison, archiving |
Manual analysis, team sharing, presentation |
Typical workflow:
Collect ──► collapsed ──► flamegraph.html (manual analysis)
                   │
                   ├──► Differential flame graph (regression detection)
                   ├──► Custom aggregation scripts
                   └──► Archive storage
6.5 - Network Drop Monitoring
About HUATUO
HUATUO is an OS-level deep observability project open-sourced by DiDi and incubated under CCF (China Computer Federation). It provides kernel-level deep observability for cloud-native general computing, AI computing, cloud services, and infrastructure services.
Overview
dropwatch observes software drops through tracepoint/skb/kfree_skb and hardware drops reported by capable drivers through raw_tracepoint/devlink_trap_report. It outputs protocol fields, the IP tuple, network device, drop reason, and kernel stack.
dropwatch supports kernel-side filtering based on tcpdump-style filter expressions. The filter logic is compiled into eBPF bytecode at load time by the built-in pure-Go pcap compiler internal/pcapfilter. Filtering is performed entirely in kernel mode — only matching packets are reported to user space, reducing performance impact on the host.
In addition, dropwatch supports device whitelist/blacklist filtering, global per-second rate limiting, and integration with huatuo-bamai to store drop events in Elasticsearch for long-term analysis.
Scenarios
1. Kubernetes Cloud-Native Network Drop Diagnosis
In scenarios such as container migration, frequent Pod restarts, and Service port conflicts, dropwatch captures kfree_skb events in real time and correlates them with specific containers to quickly identify the root cause of packet drops. Combined with --filter "tcp and port <service-port>" to filter specific business traffic, the mean time to root cause is reduced from hours to minutes.
For intermittent spikes in network latency or drops in throughput, dropwatch collects drop events and, together with the kernel call stack, identifies the specific kernel function where the drop occurred (e.g. tcp_v4_rcv, ip_output). This helps distinguish whether the cause is a firewall drop, routing failure, buffer overflow, or other reasons.
3. Multi-Tenant Network Isolation Troubleshooting
In container environments that share network namespaces or veth devices, use --device to filter by network device and --filter to filter by protocol. This precisely captures drop events for the target container, preventing other tenants’ traffic from interfering with the diagnosis.
Use --output-storage to send drop events to huatuo-bamai, which stores them in Elasticsearch for multi-dimensional correlation with metrics and logs. Overlay drop events on a Grafana timeline, aligned with application error rates and latency curves, to correlate kernel drops with application anomalies precisely.
Usage
1. Filter Expressions
Filter expressions use tcpdump syntax. The built-in pure-Go pcap compiler internal/pcapfilter compiles them into eBPF bytecode at load time. Filtering is performed entirely in kernel mode, reducing host impact — only matching packets are reported to user space.
1.1 Supported Expressions
internal/pcapfilter supports a subset of the standard tcpdump syntax. The following primitives are reliable:
Protocols
ip   ip6   tcp   udp   icmp   icmp6   igmp   pim   esp   ah   vrrp   arp   rarp
ip proto tcp      ip6 proto udp        (protocol names only; numeric protocol numbers not supported)
Host addresses
host 10.0.0.1
src host 10.0.0.1
dst host 10.0.0.1
Ports
port 80
src port 443
dst port 8080
Networks (CIDR)
net 10.0.0.0/8
src net 192.168.1.0/24
dst net 172.16.0.0/12
Multicast and Ethernet addresses
ip multicast    ip6 multicast    multicast    ether multicast
ether host 00:11:22:33:44:55
Boolean operators and grouping
tcp and port 80
tcp or udp
not arp
tcp and (port 80 or port 443)
ip and src net 192.168.1.0/24 and tcp dst port 3306
1.2 Unsupported Expressions
The following expressions are not supported. Using them causes compilation failures or incorrect match results:
| Expression |
Reason |
tcp[tcpflags] & tcp-syn != 0, ip[8], tcp[0:4] |
Byte-offset expressions (proto[offset:size]) not implemented |
ip proto 6, ip6 proto 17 |
Numeric protocol numbers not supported; use names (e.g. ip proto tcp) |
ether proto 0x0800 |
Hex EtherType not supported; use names (e.g. ether proto ip) |
sctp |
Keyword not recognized |
portrange 80-90, tcp portrange 1-100 |
Port ranges not supported |
less N, greater N |
Packet-length filtering not supported |
ip broadcast, ether broadcast |
Broadcast matching not supported |
vlan, mpls, pppoes |
Tunnel/encapsulation keywords not supported |
gateway |
Not supported |
1.3 Examples
# Monitor all TCP drops (default — reliable in both L2 and L3 contexts)
--filter "tcp"

# TCP and UDP
--filter "tcp or udp"

# Specific destination host (applies to both TCP and UDP)
--filter "dst host 10.0.0.1"

# Specific port
--filter "tcp and port 443"

# Exclude a noisy host
--filter "tcp and not host 169.254.169.254"

# Specific subnet + specific port
--filter "src net 192.168.1.0/24 and tcp dst port 3306"

# Monitor non-TCP drops (UDP and ICMP only — avoid "not tcp", which captures unknown L3 events)
--filter "udp or icmp"

# Monitor ARP drops only (effective only in L2 context; never matches at L3)
--filter "arp"
--filter "ip" / --filter "ip6" now correctly match the corresponding IP protocol family (L2 by EtherType, L3 by version nibble). If you only care about a specific transport layer or host, prefer the more precise tcp, udp, host, or ip proto <name>.
2. Running dropwatch
| Flag |
Default |
Description |
--bpf-path <path> |
required |
Path to the dropwatch eBPF object file |
--filter <expr> |
(none) |
tcpdump-style filter expression |
--device <names> |
(none) |
Device whitelist: only collect drops from these devices; comma-separated (e.g. eth0,eth1) |
--device-excluded <names> |
(none) |
Device blacklist: exclude drops from these devices; mutually exclusive with --device |
--duration <n> |
0 |
Stop after N seconds (0 = run until Ctrl-C) |
--output <json|text> |
text |
Output format; ignored when --output-storage is set |
--output-storage <path> |
(none) |
Send events to huatuo-bamai via Unix socket |
--task-id <id> |
(none) |
Task ID for this session; typically used with --output-storage |
--max-events-per-second <n> |
0 |
Global rate limit in events/sec (0 = unlimited); applied after --device / --filter |
--filter and device filtering are orthogonal; when both are specified, both apply (AND semantics). If neither --device nor --device-excluded is specified, all devices are collected. --device and --device-excluded are mutually exclusive; whitelist mode drops SKBs without a net_device, while blacklist mode passes them.
At startup, dropwatch detects devlink:devlink_trap_report. When supported, it loads both software and hardware drop probes. Otherwise, it logs a warning and loads only the software drop probe. Hardware collection also requires a driver that registers devlink drop traps and a target trap whose action is trap. With action drop, hardware sends no packet copy to the CPU, so dropwatch cannot inspect it.
devlink Hardware Drop Detection
dropwatch requires no additional startup flags. Before using hardware drop detection, verify that the kernel, driver, and target trap meet the requirements:
# 1. Verify that the kernel provides the devlink trap tracepoint
test -e /sys/kernel/tracing/events/devlink/devlink_trap_report/id || \
  test -e /sys/kernel/debug/tracing/events/devlink/devlink_trap_report/id

# 2. List devlink devices and traps registered by the driver
sudo devlink dev show
sudo devlink trap show <bus/device>

# 3. Enable packet reporting for the target DROP trap
sudo devlink trap set <bus/device> trap <trap-name> action trap

# 4. Start dropwatch and display only hardware drops
sudo dropwatch --bpf-path bpf/net_dropwatch.o --output json 2>/dev/null | \
  jq -c 'select(.drop_source == "hardware")'
<bus/device> is the device identifier returned by devlink dev show, such as pci/0000:03:00.0. After diagnosis, restore the trap to its previous action.
This capability collects only packets that the driver reports through DEVLINK_TRAP_TYPE_DROP. It does not capture all hardware packets and does not replace NIC hardware-drop counters. Drops such as hardware queue overflows are visible only when the driver implements and reports them as devlink drop traps. Traps of type exception or control are not reported as drop events.
--filter, --device, --device-excluded, and --max-events-per-second apply to both software and hardware events. Text output formats a hardware reason as reason=<group>/<trap> drop_source=hardware. JSON output uses the separate drop_reason_group, drop_reason, and drop_source fields.
tcpshark --with-dropwatch shares source classification and reason resolution and automatically enables available hardware capture. A successful correlation preserves the same drop_source, drop_reason, and drop_reason_group semantics. See retransmission correlation.
Examples
# Text output, monitor TCP drops on all devices
sudo dropwatch --bpf-path bpf/net_dropwatch.o --filter "tcp"

# Monitor drops on eth0 only
sudo dropwatch --bpf-path bpf/net_dropwatch.o --device eth0 --output json

# Exclude loopback
sudo dropwatch --bpf-path bpf/net_dropwatch.o --device-excluded lo --output json

# Combine device and protocol filters
sudo dropwatch --bpf-path bpf/net_dropwatch.o --device eth0 --filter "tcp and port 443" --output json

# Capture for 60 seconds and exit
sudo dropwatch --bpf-path bpf/net_dropwatch.o --filter "tcp and port 443" --duration 60 --output json

# Forward events to a running huatuo-bamai instance
sudo dropwatch --bpf-path bpf/net_dropwatch.o --filter "tcp" --output-storage /var/run/huatuo-toolstream.sock

# Capture 10 seconds of JSON output, excluding events whose stack contains ip_finish_output
sudo dropwatch --output json --duration 10 --bpf-path bpf/net_dropwatch.o | jq -c 'select(.stack | test("ip_finish_output") | not)'

# Capture 10 seconds of JSON output, printing all fields except stack
sudo dropwatch --output json --duration 10 --bpf-path bpf/net_dropwatch.o | jq -c 'del(.stack)'
jq -c compresses each matching event into a single-line JSON, convenient for saving as NDJSON or further pipe processing. test("ip_finish_output") checks whether stack matches the regex; not negates the result, so the command above excludes stacks containing ip_finish_output. Remove | not to keep only those containing ip_finish_output. del(.stack) removes the stack field from the jq output, useful for viewing just the timestamp, device, process, packet_* metadata, and layers protocol fields. For userspace call-stack filtering before storage, configure EventTracing.IssuesList in huatuo-bamai (see Section 4).
3. Event Data Structure
Each drop event is represented as an NDJSON object (types.DropWatchTracing).
| Field |
Type |
Description |
observed_timestamp |
string |
UTC userspace receive/format time (RFC3339Nano), not the kernel hook timestamp |
kernel_observed_timestamp |
string |
UTC kernel observation time (RFC3339Nano), converted from the raw monotonic clock. |
type |
string |
Reserved TCP type; currently unset (1 common, 2 SYN flood, 3/4 listen overflow) |
drop_source |
string |
Drop source: software for the kernel network stack or hardware for a devlink DROP trap |
drop_reason |
string |
SKB_DROP_REASON_* for software drops; if kernel BTF resolution fails, dropwatch logs a warning and falls back to the numeric value. For hardware drops, this is the devlink trap name |
drop_reason_group |
string |
Devlink trap group used to classify hardware drops; omitted for software drops |
drop_location |
string |
Hexadecimal kfree_skb call address for software drops; omitted for hardware drops |
source |
string |
Event source; tools for standalone dropwatch and events when launched by huatuo-bamai |
comm |
string |
Process name at the time of the drop |
pid |
uint64 |
Process TGID |
container_id |
string |
Container ID (populated by huatuo-bamai resolution, omitempty) |
memory_cgroup_css_addr |
string |
Memory cgroup CSS address, used for container resolution |
net_namespace_cookie |
uint64 |
Network namespace cookie, used for container resolution |
net_namespace_inum |
uint32 |
Network namespace inum, used for container resolution |
netdev_name |
string |
Network device name (e.g. eth0) |
netdev_ifindex |
uint32 |
Network interface index |
netdev_queue_mapping |
uint32 |
TX queue mapping |
netdev_linkstatus |
[]string |
Network device link status flags |
packet_skb_addr |
string |
SKB address (hexadecimal, omitempty) |
packet_eth_proto |
string |
Raw EtherType (hexadecimal, e.g. 0x0800) |
packet_len_bytes |
uint32 |
Kernel skb->len snapshot; it is an SKB logical length and may differ from the on-wire frame length |
layers |
object |
Layered protocol parse result; missing layers are omitted |
stack |
string |
Kernel call stack (newline-separated) |
For hardware events, stack is the kernel call stack at which the driver reports the devlink trap. It does not identify the actual drop location inside the ASIC. Use drop_reason_group, drop_reason, device information, and driver documentation to diagnose hardware drops.
layers uses fixed fields to express the protocol stack, without relying on a separate protocol enumeration:
| Field |
Description |
layers.label |
Protocol combination label, e.g. IPv4/TCP, IPv6/UDP, ARP, unknown |
layers.ether |
L2 fields when a real Ethernet header is present: saddr, daddr, type, len; len is non-zero only for IEEE 802.3 framing |
layers.ipv4 |
IPv4 fields: version, ihl, tos, len, id, flags, frag_offset, ttl, protocol, checksum, saddr, daddr |
layers.ipv6 |
IPv6 fields: version, traffic_class, flow_label, len, next_header, hop_limit, saddr, daddr |
layers.tcp |
TCP fields: sport, dport, seq, ack_seq, data_offset, window, checksum, urgent, sk_state |
layers.udp |
UDP fields: sport, dport, len, checksum |
layers.icmp |
ICMP/ICMPv6 fields: type, code, checksum, id, seq; ICMPv6 echo requests/replies include their identifier and sequence number, while other ICMPv6 messages omit them |
layers.arp |
ARP fields: addr_type, protocol, hw_address_size, prot_address_size, operation, sender_mac, sender_ip, target_mac, target_ip |
For ICMPv6 Echo Request/Reply (types 128/129), id and seq are decoded only
when all four Echo bytes were captured. A truncated Echo header retains the
common ICMPv6 fields with zero ID/Seq. If the common header is also truncated,
the decoded IPv6 layer is retained and layers.icmp is absent. Other ICMPv6
message types do not populate the Echo fields.
JSON omits each zero-valued id or seq independently. Text omits both only
when both are zero. A missing output field therefore cannot distinguish an
absent or truncated Echo header from a valid zero value.
4. Integration with huatuo-bamai
huatuo-bamai launches dropwatch as a subprocess and uses --output-storage to send events to the built-in processing pipeline, which ultimately stores them in Elasticsearch. Typical parameters:
dropwatch \
  --bpf-path <CoreBpfDir>/net_dropwatch.o \
  --output-storage /var/run/huatuo-toolstream.sock \
  --filter "tcp"
4.1 Configuration Reference (huatuo-bamai.conf)
[EventTracing]
    # Optional call-stack filters. dropwatch discards events whose stack matches a configured regex.
    # Default: []
    IssuesList = []

[EventTracing.Dropwatch]
    # Tcpdump filter for standalone dropwatch.
    # Default: "tcp"
    Filter = "tcp"

    # Forwarded to dropwatch --max-events-per-second.
    # Default: 100
    MaxEventsPerSecond = 100

[EventTracing.TCPRetransmit]
    # Run tcpshark with a private embedded dropwatch source.
    EnableDropwatch = false
Standalone dropwatch always emits raw DropWatchTracing events. Local TCP retransmission correlation loads a separate net_dropwatch.o, uses EventTracing.TCPRetransmit.Filter for both inputs, and emits only finalized TCPRetransmitTracing results. The two modes may run together; embedded drops are never stored as duplicate raw events.
4.2 Noise Filtering
No call-stack noise rule is enabled by default. When EventTracing.IssuesList is configured, huatuo-bamai discards matching events. The following patterns are possible operator-configured filters; validate them against the local kernel and workload before enabling them:
| Pattern |
Stack Frame Prefix |
Reason |
| ARP/neighbor table expiry |
neigh_invalidate/ |
Neighbor table entry expiration cleanup; does not affect any active data flow. Remove the rule from EventTracing.IssuesList to disable this filter. |
| bnxt NIC TX completion |
bnxt_tx_int/ or __bnxt_tx_int/ |
The Broadcom bnxt NIC driver calls kfree_skb to release SKBs after DMA transmit completion; this is normal behavior, not a drop. |
Closing
6.6 - TCP Retransmission Tracing
About HUATUO
HUATUO is an OS-level deep observability project open-sourced by DiDi and incubated under CCF (China Computer Federation). It provides kernel-level deep observability for cloud-native general computing, AI computing, cloud services, and infrastructure services.
Overview
tcpshark --mode retransmit observes TCP retransmission-related kernel activity through the tcp/tcp_retransmit_skb and tcp/tcp_retransmit_synack tracepoints. It can also observe the tcp_send_loss_probe kprobe when TLP collection is explicitly enabled. Depending on the event type, an event can include the IP 4-tuple, TCP state, congestion-control state, retransmission counters, sequence information, and socket metadata used for container resolution.
The userspace classifier derives a connection phase and a reason label from the event type, sk_state, ca_state, and reorder counters. These labels are operational heuristics, not packet-loss root-cause proof.
Filter expressions are compiled at load time by internal/pcapfilter and run in the kernel. The SKB, SYN-ACK, and TLP hooks always evaluate the expression against the same synthetic L3 TCP packet, with or without local correlation. Protocol, address, network, and port conditions are supported. Ethernet addresses, payload, real packet lengths, IP/TCP options, and raw byte-offset expressions are not available. Safe ethertype checks such as ether proto ip are rewritten for L3. A pair of IPv4-mapped IPv6 socket addresses is filtered as IPv4; the raw perf record remains AF_INET6 and userspace normalizes the addresses before matching. In local correlation mode, tcpshark also applies the exact same expression to embedded dropwatch. Use a direction-symmetric expression when reverse ACK or SYN-ACK evidence must remain in scope.
Scenarios
1. TCP Network Quality and Retransmission Diagnosis
Continuously observe RTO, fast retransmission, reorder-prone retransmission, and TLP events to identify abnormal retransmissions during connection establishment, data transfer, and connection teardown. These signals help investigate packet loss, congestion, reordering, and peer reachability problems.
2. Kubernetes Container Network Troubleshooting
Use the container ID, network namespace, and socket cgroup metadata to identify the workload experiencing retransmissions. Apply --filter "tcp and port <service-port>" to focus on a specific service and reduce interference from other host connections.
3. Application Latency and Throughput Anomaly Analysis
Align TCP retransmission events with application latency, error-rate, and throughput timelines. This helps determine whether RTOs or repeated retransmissions coincide with service degradation and distinguish slow application processing from underlying network problems.
4. Locating Packet Loss with dropwatch Correlation
Run tcpshark in local correlation mode to correlate retransmissions with packet drops in the same process. Matching checks the network namespace, tuple direction, TCP sequence or ACK evidence, and kernel monotonic ordering. A strict match identifies an observed drop, with its software or hardware source taken from the record. A no-match remains unknown because source readiness does not establish that the retransmission’s earlier causal history was observed.
Usage
1. Running tcpshark
tcpshark --mode retransmit [flags]
| Flag |
Default |
Description |
--mode retransmit |
required |
Select TCP retransmission tracing mode. |
--enable-tlp, --tlp |
disabled |
Also attach tcp_send_loss_probe and emit TLP events. |
--bpf-path <path> |
required without correlation |
Path to one tcp_retransmit.o file. |
--bpf-path-dir <dir> |
required with correlation |
Directory containing tcp_retransmit.o and net_dropwatch.o. |
--with-dropwatch |
disabled |
Load embedded dropwatch and correlate it with retransmissions. |
--filter <expr> |
(none) |
L3-compatible tcpdump-style filter for all retransmit hooks; also shared with embedded dropwatch in local mode; see §2. |
--device <names> |
(none) |
Comma-separated interface allowlist, as in dropwatch; filters only embedded dropwatch and requires --with-dropwatch. |
--device-excluded <names> |
(none) |
Interface denylist, mutually exclusive with --device; requires --with-dropwatch. |
--duration <n> |
0 |
Stop after N seconds (0 = run until Ctrl-C). |
--max-events-per-second <n> |
0 |
BPF-side event rate limit; 0 means unlimited. |
--output <json|text> |
text |
Output format; ignored when --output-storage is set. |
--output-storage <path> |
(none) |
Send events to huatuo-bamai over a Unix socket. |
--task-id <id> |
(none) |
Task ID for the toolstream session; requires --output-storage. |
When both --output and --output-storage are explicitly specified, --output is ignored and a warning is printed.
1.1 Examples
# Text output for all retransmission-related events
sudo tcpshark --mode retransmit --bpf-path bpf/tcp_retransmit.o

# NDJSON output
sudo tcpshark --mode retransmit --bpf-path bpf/tcp_retransmit.o --output json

# BPF-side filter for regular retransmitted SKBs to one destination host and port
sudo tcpshark --mode retransmit --bpf-path bpf/tcp_retransmit.o --filter "dst host 10.0.0.1 and dst port 443"

# Correlate locally; both BPF inputs use the same direction-symmetric filter
sudo tcpshark --mode retransmit --with-dropwatch --bpf-path-dir bpf \
  --filter "tcp and port 443"

# Include Tail Loss Probe events (disabled by default)
sudo tcpshark --mode retransmit --enable-tlp --bpf-path bpf/tcp_retransmit.o

# Emit at most 100 events/second; overflow prints a rate limit hit log
sudo tcpshark --mode retransmit --bpf-path bpf/tcp_retransmit.o \
  --max-events-per-second 100

# Filter all formatted event types to destination port 443 in userspace
sudo tcpshark --mode retransmit --bpf-path bpf/tcp_retransmit.o --output json \
  | jq -c 'select(.tcp_dport == 443)'

# Keep only events classified as RTO for 60 seconds
sudo tcpshark --mode retransmit --bpf-path bpf/tcp_retransmit.o --duration 60 --output json \
  | jq -c 'select(.tcp_reason == "RTO")'

# Forward events to a running huatuo-bamai instance
sudo tcpshark --mode retransmit --bpf-path bpf/tcp_retransmit.o \
  --output-storage /var/run/huatuo-toolstream.sock
jq -c emits compact single-line JSON, which is convenient for NDJSON files and downstream pipelines.
1.2 Integration with huatuo-bamai
tcpshark uses the same --output-storage and toolstream flow as dropwatch. For the common storage workflow, refer to the dropwatch documentation. TCP retransmission tracing adds the following configuration:
[EventTracing.TCPRetransmit]
    # Used by tcpshark in both modes. Default: empty.
    Filter = ""

    # Forwarded as tcpshark --enable-tlp. Default: false.
    EnableTLP = false

    # Run tcpshark with an embedded dropwatch source. Default: false.
    EnableDropwatch = false

    # Forwarded as tcpshark --max-events-per-second. Default: 100; 0 disables it.
    MaxEventsPerSecond = 100
EventTracing.TCPRetransmit.Filter controls retransmission collection in both
modes. With local correlation disabled, an empty value passes no --filter
flag. With local correlation enabled, the normalized expression is passed to
both tcpshark inputs and an empty value becomes tcp.
EventTracing.Dropwatch.Filter remains independent and controls only
standalone dropwatch.
The tcp_retransmit tracer is in the global BlackList by default. Remove it
from the list and restart huatuo-bamai to enable the tracer. Standalone
dropwatch may remain blacklisted because local correlation owns a private
dropwatch source.
2. Filter Expressions
tcpshark uses the same tcpdump-style filter expressions as dropwatch. For complete syntax, limitations, and additional examples, refer to the dropwatch documentation.
# Select one destination host and port
--filter "dst host 10.0.0.1 and dst port 443"

# Select traffic in both directions between two networks
--filter "(src net 10.10.0.0/16 and dst net 10.20.0.0/16) or (src net 10.20.0.0/16 and dst net 10.10.0.0/16)"
In local mode the same expression must cover both traffic directions. A directional selector can exclude reverse ACK or SYN-ACK drop evidence and make the result less useful.
Local mode rejects Ethernet-address primitives such as ether host 02:00:00:00:00:01. Ethertype primitives such as ether proto ip and ether proto ip6 are supported because they can be rewritten as raw-IP version checks.
3. Event Data Structure
Each event is an NDJSON object (types.TCPRetransmitTracing). Fields tagged with omitempty are absent when their value is empty or zero.
| Field |
Type |
Description |
observed_timestamp |
string |
UTC userspace receive/format time (RFC3339Nano), not the kernel hook timestamp. |
kernel_observed_timestamp |
string |
UTC kernel observation time (RFC3339Nano), converted from the raw monotonic clock. |
comm |
string |
Current kernel execution-context command, not necessarily the socket-owning process. |
pid |
uint64 |
Current execution-context TGID, not necessarily the socket owner’s TGID. |
container_id |
string |
Container ID when resolved by huatuo-bamai; see §3.2. |
memory_cgroup_css_addr |
string |
Socket memory-cgroup CSS address in hexadecimal form, used for container resolution. |
net_namespace_cookie |
uint64 |
Socket network-namespace cookie used for container resolution. |
net_namespace_inum |
uint32 |
Socket network namespace inum used for container resolution. |
tcp_saddr |
string |
Source IP address. |
tcp_daddr |
string |
Destination IP address. |
tcp_sport |
uint16 |
Source port. |
tcp_dport |
uint16 |
Destination port. |
tcp_state |
string |
TCP socket state, such as ESTABLISHED, SYN_SENT, or NEW_SYN_RECV. |
phase |
string |
Classifier output: connect, data, or close. |
tcp_reason |
string |
Classifier output: RTO, fast_retransmit, TLP, or unknown. |
event_type |
string |
tcp_retransmit_skb, tcp_retransmit_synack, or tcp_send_loss_probe. |
ca_state |
uint8 |
Congestion-control state: 0=Open, 1=Disorder, 2=CWR, 3=Recovery, 4=Loss. |
icsk_retransmits |
uint8 |
Current retransmission counter snapshot. |
icsk_pending |
uint8 |
Raw pending timer state from inet_connection_sock; see the value table below. |
reord_seen |
uint32 |
Cumulative flow reorder counter. |
dsack_dups |
uint32 |
Cumulative DSACK duplicate counter. |
tcp_seq |
uint32 |
TCP_SKB_CB(skb)->seq for SKB events; snd_nxt for TLP; request snt_isn for SYN-ACK when available. |
tcp_ack_seq |
uint32 |
tcp_sk(sk)->rcv_nxt for SKB events; snd_una for TLP; request rcv_nxt for SYN-ACK when available. |
tcp_end_seq |
uint32 |
TCP_SKB_CB(skb)->end_seq for SKB events; request snt_isn + 1 for SYN-ACK when available; omitted for TLP. |
tcp_flags |
string |
Rendered TCP flag set such as `SYN |
skb_addr |
string |
Retransmission-queue SKB pointer in hex; absent for SYN-ACK and TLP events. |
drop_location |
string |
Correlation classification: software, hardware, or unknown. Equals drop_source for a match; unlike the dropwatch field, it is not a kernel address. |
drop_source |
string |
Matched drop source: software or hardware; an unrecognized ABI source is unknown. Omitted on no-match. |
drop_reason |
string |
Same as dropwatch: a BTF-resolved SKB_DROP_REASON_* name for software, a decimal value if unresolved, or NOT_SUPPORTED on older kernels. Hardware drops use the devlink trap name. |
drop_reason_group |
string |
Devlink trap group, such as l2_drops, for aggregating hardware reasons. Omitted for software drops and no-matches. |
correlation_reason |
string |
One terminal outcome: matched, unsupported, warmup, wait_timeout, queue_full, or interrupted. Omitted when correlation is disabled. |
matched_net_namespace |
bool |
A drop on the same TCP flow was observed in the same namespace, independently of packet and time checks. Always true for a strict match; omitted when false. |
drop_perf_status |
object |
Cumulative embedded-dropwatch counters for an unmatched result. map_counters_available identifies valid map counters; reader lost_samples remains valid on map errors. |
drop_stack |
string |
Matched drop stack; unmatched stacks are not symbolized. |
source |
string |
Event source. It is tools when tcpshark runs standalone and events when huatuo-bamai launches it. |
icsk_pending is a timer-state snapshot at the hook, not a stable retransmission-reason enum. TLP classification uses the explicit event_type=tcp_send_loss_probe and does not depend on icsk_pending=5.
| Value |
Kernel state |
Meaning |
0 |
None |
No transmit-timer event is currently pending. |
1 |
ICSK_TIME_RETRANS |
Retransmission timeout timer (RTO). |
2 |
ICSK_TIME_DACK |
Delayed ACK; modern kernels keep this state in icsk_ack.pending and use a separate delayed-ACK timer, so it normally does not appear in icsk_pending. |
3 |
ICSK_TIME_PROBE0 |
Zero-window probe timer. |
4 |
Version-dependent |
Current mainline kernels no longer define this value; older kernels used it for Early Retransmit, and still older kernels used it for Keepalive. |
5 |
ICSK_TIME_LOSS_PROBE |
Tail Loss Probe (TLP) timer. |
6 |
ICSK_TIME_REO_TIMEOUT |
Reordering timeout, primarily used by RACK loss detection. |
3.1 Text Output Format
Text retains its terminal-friendly layout while covering the same event variables as JSON. Optional variables appear only when non-zero or non-empty, and string values are not JSON-quoted or escaped. For compatibility with the original text format, state, skb, seq, end, ack, flags, ca, retrans, and reason correspond to the JSON fields tcp_state, skb_addr, tcp_seq, tcp_end_seq, tcp_ack_seq, tcp_flags, ca_state, icsk_retransmits, and correlation_reason, respectively.
<timestamp> [<phase>/<tcp_reason>] <saddr>:<sport> > <daddr>:<dport> state=<STATE> event_type=<TYPE> [kernel_observed_timestamp=<UTC>] [SYNACK] [skb=<ADDR>] seq=<N> [end=<N>] ack=<N> [flags=<FLAGS>] pid=<N> comm=<COMM> ca=<N> retrans=<N> icsk_pending=<N> [reord_seen=<N>] [dsack_dups=<N>] [container_id=<ID>] [memory_cgroup_css_addr=<ADDR>] [net_namespace_cookie=<N>] [net_namespace_inum=<N>] [drop_location=<LOCATION>] [drop_source=<SOURCE>] [drop_reason=<REASON>] [drop_reason_group=<GROUP>] [reason=<REASON>] [matched_net_namespace=true] [dropwatch_map_counters_available=<true|false> dropwatch_perf_lost=<N> dropwatch_lost_samples=<N> dropwatch_rate_limited=<N>] [source=<SOURCE>]
Example:
2026-07-23T02:14:40.304775546Z [data/RTO] 127.0.0.1:19996 > 127.0.0.1:42128 state=ESTABLISHED event_type=tcp_retransmit_skb kernel_observed_timestamp=2026-07-23T02:14:40.304Z skb=0xffff931c14fdf800 seq=3154974646 end=3154991030 ack=948393597 flags=ACK|PSH pid=1420 comm=kube-apiserver ca=4 retrans=4 icsk_pending=0 net_namespace_inum=4026531992
The pid and comm in this example describe the execution context in which the hook ran; use container_id and socket metadata for workload attribution.
A non-empty drop_stack is rendered as indented lines after the event line,
not as an inline drop_stack= token.
3.2 Container ID Resolution
tcpshark cannot access the Pod manager directly. In standalone output, container_id is normally absent, while socket memcg and network-namespace metadata are still emitted when available. In huatuo-bamai mode, an empty container_id is resolved in this order: memory_cgroup_css_addr, net_namespace_cookie, then net_namespace_inum.
If all lookups miss, the event is still stored without container_id. Do not use pid or comm as a fallback for socket ownership because they describe the hook execution context.
4. Kernel Events and Classification
4.1 Kernel Hook Points
| Hook |
Kernel location |
What the event means |
Data availability |
tracepoint tcp/tcp_retransmit_skb |
__tcp_retransmit_skb() |
A retransmission was attempted for a retransmission-queue SKB. The tcpshark event does not retain the kernel transmit result. The SKB is headerless, so sequence fields come from TCP_SKB_CB(skb) and ACK comes from tcp_sk(sk)->rcv_nxt. |
SKB pointer, TCP seq/end_seq/ack/flags, socket state, CA state, timers, and reorder counters. |
tracepoint tcp/tcp_retransmit_synack |
tcp_rtx_synack() |
A passive-open SYN-ACK retransmission was successfully submitted by tcp_rtx_synack(). |
Request-socket addresses and ports; no retransmission SKB pointer or TCP seq/ack. |
kprobe tcp_send_loss_probe |
tcp_send_loss_probe() |
A Tail Loss Probe is being prepared; collected only with --enable-tlp. |
Socket metadata plus snd_nxt/snd_una; no SKB pointer or rendered TCP flags. |
The BPF program uses CO-RE field reads (BPF_CORE_READ and related helpers), so supported kernel layouts do not require rebuilding the C source for each kernel version.
4.2 Connection Phase
The regular-SKB phase is derived from sk_state. SYN-ACK events use a fixed phase in userspace.
The TCP three-way handshake below shows the connect phase and its retransmission hook points:
sequenceDiagram
    participant C as Client
    participant S as Server
    Note over C,S: Initial states: CLOSED / LISTEN
    C->>S: ① SYN
    Note left of C: SYN_SENT(2)<br/>phase=connect
    opt SYN is not acknowledged
        C-->>S: SYN retransmission<br/>tcp_retransmit_skb
    end
    Note right of S: SYN_RECV(3) or NEW_SYN_RECV(12)<br/>phase=connect
    S->>C: ② SYN + ACK
    opt Final ACK does not arrive
        S-->>C: SYN-ACK retransmission<br/>tcp_retransmit_synack
    end
    C->>S: ③ ACK
    Note over C,S: ESTABLISHED(1)<br/>subsequent regular data-SKB events use phase=data
The three solid arrows are the initial handshake packets and do not produce tcpshark events. Only the retransmission paths inside the optional blocks are observed. Active-open SYN retries are reported by tcp_retransmit_skb, while passive-open SYN-ACK retries are reported by tcp_retransmit_synack; both are classified as connect.
The complete phase mapping is:
| Phase |
Source state or event |
Description |
connect |
SYN_SENT(2), SYN_RECV(3), NEW_SYN_RECV(12), or tcp_retransmit_synack |
Connection establishment. |
data |
ESTABLISHED(1) or unrecognized/default states |
Data transfer/default classification. |
close |
FIN_WAIT1(4), FIN_WAIT2(5), TIME_WAIT(6), CLOSE_WAIT(8), LAST_ACK(9), CLOSING(11) |
Connection teardown. |
4.3 Reason Classification
| Event or condition |
Reason |
Interpretation |
tcp_retransmit_synack |
RTO |
Fixed userspace label for the SYN-ACK retry timer path. |
tcp_send_loss_probe |
TLP |
Fixed userspace label for the optional Tail Loss Probe hook. |
tcp_retransmit_skb, ca_state=4 (Loss) |
RTO |
The socket is in TCP_CA_Loss. |
tcp_retransmit_skb, ca_state=3 (Recovery) |
fast_retransmit |
Recovery-path retransmission. |
tcp_retransmit_skb, ca_state=0..2, connect/close phase |
RTO |
Phase-based fallback used by the current classifier. |
tcp_retransmit_skb, ca_state=0..2, data phase |
unknown |
The available snapshots are insufficient to assign another label. |
The classifier observes socket state at the hook and cannot reconstruct the complete ACK/loss history. Treat tcp_reason as a grouping label rather than a verified root cause.
4.4 Reorder Heuristic
4.5 Operational Guidance
No event type is unconditionally safe to discard. Prefer rate, ratio, and service-impact thresholds over filtering solely by event_type or tcp_reason. For the common huatuo-bamai noise-filtering mechanism, refer to the dropwatch documentation.
| Pattern |
Typical priority |
Guidance |
tcp_reason=RTO |
High |
Investigate sustained or service-correlated increases; RTO normally has greater latency impact than Recovery-path retransmission. |
tcp_reason=fast_retransmit |
Medium |
Correlate with loss, congestion, and SACK/RACK behavior. |
tcp_reason=TLP |
Context dependent |
Optional signal only; confirm that TLP collection was deliberately enabled before using it in alerting. |
event_type=tcp_retransmit_synack |
Usually low per isolated retry |
Repeated events can indicate handshake reachability, host egress, firewall, or client/network problems. |
When building alerts, aggregate by service or connection and compare against traffic volume. A small absolute count on a busy host can be benign, while a burst affecting a low-volume critical service can be significant.
5. Correlation with dropwatch
With --with-dropwatch, one tcpshark process owns both perf inputs. A retransmission waits up to 100 ms for a delayed dropwatch delivery. A candidate drop must precede the retransmission by no more than one second in kernel monotonic time. The embedded source never emits raw drop documents; separately enabled standalone dropwatch remains an independent raw-event stream.
For the limitations around out-of-order reads across the two perf streams, the 100 ms arrival window, the one-second causal window, and negative evidence, see Challenges of TCP Retransmission and dropwatch Correlation.
Like standalone dropwatch, the embedded source automatically detects and enables devlink DROP trap capture (HardwareAuto). No additional hardware flag is needed. If the tracepoint is unavailable, it logs a warning and continues software capture. Visibility depends on driver reporting; see the dropwatch hardware requirements.
--device, --device-excluded, --filter, and --max-events-per-second use the same names as dropwatch. The interface allowlist or denylist limits only embedded dropwatch, covering both software and hardware events. The allowlist rejects records without device information; the denylist permits them. Retransmissions still use the shared L3 filter, so device filtering can reduce available drop evidence.
Matched output retains drop_source, drop_reason, and the hardware drop_reason_group. drop_reason describes the observed drop, tcp_reason classifies the retransmission trigger, and correlation_reason identifies how this correlation attempt ended. Independent diagnostic fields describe observation limits. The BTF reason table loads once per session. A load failure logs a warning and falls back to numeric software reasons; hardware trap decoding remains available.
# Use the same interface and traffic options as dropwatch to inspect matched hardware drops
sudo tcpshark --mode retransmit --with-dropwatch --bpf-path-dir bpf \
  --device eth0 --filter "tcp and port 443" --output json \
  | jq -c 'select(.drop_source == "hardware")'
Hardware drops must meet the same namespace, TCP, and time constraints. Missing namespace or TCP evidence leaves a retransmission unmatched; no-match does not establish hardware loss. A hardware drop_stack is the driver’s trap-reporting kernel stack, not a location inside the ASIC.
An unrecognized ABI source produces unknown for both drop_source and drop_location, even when packet evidence matches. The source is never inferred from a reason or stack. Such a match still reports correlation_reason=matched.
5.1 Correlation Results
| Result |
Required evidence |
Output |
| Outbound segment match |
Same network namespace, family, direction, tuple, monotonic ordering, and overlapping SYN/data/FIN sequence range. |
correlation_reason=matched, with the drop source, reason, and drop_stack. |
| Reverse ACK match |
Reverse tuple in the same namespace, ACK flag set, monotonic ordering, and ACK covering the retransmitted sequence end. |
correlation_reason=matched, with the drop source, reason, and drop_stack. |
| No strict match |
Missing local evidence does not establish where the packet was lost. |
drop_location=unknown, one terminal correlation_reason, and independent diagnostics. |
There is no tuple-only, SKB-pointer-only, cross-namespace, or ambiguous positive match. The matched_net_namespace diagnostic records a same-namespace drop on the same flow in either direction before packet and time checks. It can be true without a strict match; correlation_reason=matched remains the indication of full correlation. A false or absent flag means no namespace match was observed, not that a different namespace was confirmed. A matched drop is consumed once, while later drops on the same connection remain available. Stack symbolization runs only after a match.
5.2 Correlation Outcome
Each finalized event has exactly one correlation_reason:
| Value |
Meaning |
matched |
Strict drop evidence matched the retransmission, including matches whose drop source is unknown. |
unsupported |
The event lacks the type, namespace, time, or sequence evidence required by the matching rules. |
warmup |
The 100 ms wait elapsed without a strict match, and the retransmission predates embedded-source readiness. |
wait_timeout |
The 100 ms wait elapsed without a strict match, and the retransmission occurred at or after embedded-source readiness. This is a correlation wait, not TCP’s RTO. |
queue_full |
The bounded retransmission wait queue evicted this event before its deadline. |
interrupted |
The correlation loop exited before this event’s wait deadline. This includes normal shutdown and failures. |
Expired entries are finalized before matching or checking capacity. Shutdown uses one time snapshot: expired waits receive warmup or wait_timeout; remaining waits receive interrupted. Each event is finalized once and removed from the queue. Drop records rejected during decoding or evicted from the drop cache do not directly finalize a retransmission.
The scalar field replaces the previous reason array; update tcpshark and its receiver together. Text output uses reason=<value>. Correlation-disabled output omits the field.
warmup is selected only for an expired wait when the retransmission’s kernel timestamp predates embedded-source readiness. Retransmissions at or after readiness receive wait_timeout on expiry, including those within the first second. The one-second drop-to-retransmit limit constrains candidate matching; it does not define warmup. Processing delays do not change this classification. Strict matches, unsupported events, queue evictions, and early interruptions retain their own reasons. The outcome describes observation timing; it does not prove why a drop failed to match.
matched_net_namespace remains an independent boolean diagnostic for both matched and unmatched results. It can coexist with loss counters without changing the terminal reason.
At shutdown, tcpshark stops reading dropwatch records still in the perf ring. An unread tail drop could otherwise have matched an interrupted retransmission.
5.3 Dropwatch Perf Status
Each non-empty output batch reads status once, including batches containing only matches. Unmatched events retain the snapshot:
| Field |
Meaning |
map_counters_available |
Whether both map counters below are available. False distinguishes unavailable values from observed zeros. |
perf_lost |
Cumulative embedded-dropwatch events the kernel failed to write to the perf stream; valid only when map counters are available. |
lost_samples |
Cumulative samples reported by reader-side PERF_RECORD_LOST records; still valid when map reads fail. Omitted when zero. |
rate_limited |
Cumulative events rejected by the embedded rate limiter; valid only when map counters are available. |
On a status read error, map_counters_available is false. The zero values of perf_lost and rate_limited mean unavailable; the snapshot still retains lost_samples. tcpshark attempts to output the batch before returning the status error. A write failure stops the batch and preserves both errors. Matched events retain matched and their drop metadata without an unmatched status snapshot.
Counters belong to this dropwatch instance and reset on reload. They are sampled separately, not atomically, and cannot prove why an individual retransmission failed to match. Loss and rate limiting never replace or add a correlation reason.
5.4 Requirements and Troubleshooting
| Observation |
Checks |
software |
Inspect drop_reason and the matched stack with tuple, direction, sequence, and namespace evidence. |
hardware |
Check the trap group, trap name, and driver documentation; the match remains a correlation based on packet evidence. |
unknown with loss counters |
Narrow the shared filter, increase perf capacity, or adjust the embedded dropwatch rate limit, then capture again. |
correlation_reason=wait_timeout |
No strict candidate arrived within 100 ms; inspect the diagnostic flags and counters. |
correlation_reason=queue_full |
The waiting queue reached capacity; narrow the capture scope. |
correlation_reason=interrupted |
Inspect the collection stop or error; the wait ended early. |
matched_net_namespace=true with an unmatched reason |
A same-flow drop was observed in the same namespace. Check packet and time eligibility; the flag alone does not establish correlation. |
correlation_reason=warmup |
The wait expired for a retransmission that predates source readiness. Capture later retransmissions; this result cannot exclude a drop before source readiness. |
drop_location absent |
Expected in off mode. |
huatuo-bamai passes one normalized EventTracing.TCPRetransmit.Filter value to both local-correlation inputs. Keeping those scopes identical prevents the two sources from observing different traffic, but it does not make a no-match conclusive without a reliable causal-start boundary.
Closing
6.7 - IRQ Tracing
The standalone command collects irq/softirq stacks from every CPU or one selected CPU and builds a flame graph of the sources (who raised the softirq) and the victims (the tasks directly preempted by the softirq). When ksoftirqd services a softirq, it is the executor rather than a victim and is excluded from victim samples. It is the same tool the huatuo-bamai daemon shells out to from its AutoTracing.IRQTracing tracer; running it directly produces the same result without any storage backend or configuration file.
Build
The normal project build discovers cmd/irqtracing automatically and compiles bpf/irqtracing.c:
The command is written to _output/bin/irqtracing and the BPF object to _output/bpf/irqtracing.o; the object must be present at run time (--bpf-path).
Run
sudo ./_output/bin/irqtracing \
  --bpf-path ./_output/bpf/irqtracing.o \
  --duration 5 > irqtracing.folded
--target-cpu is optional and defaults to -1, which traces every CPU. The tool attaches only the irq/softirq_raise and irq/softirq_entry tracepoints. All-CPU mode aggregates sources and directly preempted victims across the system; selecting a non-negative CPU keeps only data from that CPU. Both modes collect for --duration seconds (default 3).
--max-events-per-second-per-cpu N optionally limits the combined number of source and victim stack samples collected per second on each traced CPU. Omitting it or setting it to 0 disables rate limiting; when enabled, N must be between 2 and 8589934590. The per-CPU budget is divided as evenly as possible between softirq_raise and softirq_entry; raise receives the extra sample when the value is odd. In all-CPU mode, the system-wide limit scales with the number of traced CPUs.
Local output is written to stdout. --output text is the default and an alias
for collapsed; it emits folded stacks suitable for flame graph tools:
source;source[raiser,NET_RX];raise_softirq_[k] 12
victim;victim[worker(123),NET_RX];work 4
Use --output flamegraph or --output svg to render an SVG flame graph
directly:
sudo ./_output/bin/irqtracing \
--bpf-path ./_output/bpf/irqtracing.o \
--duration 5 \
--output flamegraph > irqtracing.svg
Use --output json when the platform profile payload and drop count are needed:
sudo ./_output/bin/irqtracing \
--bpf-path ./_output/bpf/irqtracing.o \
--duration 5 \
--output json > irqtracing.json
The JSON contains:
{
"flamedata": { "...": "profile tree, null when nothing was collected" },
"nmissed": 1234
}
flamedata is the same profile format the platform consumes (ProfileType irqtracing:irq:count:irq:count). Every stack is rooted at source or victim, followed by a source[comm,VEC] or victim[comm(pid),VEC] label frame, then the user-space frames and the kernel frames suffixed with _[k]. VEC is one of HI, TIMER, NET_TX, NET_RX, BLOCK, IRQ_POLL, TASKLET, SCHED, HRTIMER, RCU, or VEC<n> for unknown vectors.
nmissed is the total number of samples dropped during the collection window. Samples are dropped either by the first-N budgets enabled through --max-events-per-second-per-cpu or because a counts map is full. Either case means the flame graph is incomplete. When the drop count cannot be read, the tool fails instead of writing a result. A non-zero nmissed also produces a warning line on stderr; the JSON field is the persisted contract consumed by the daemon.
--output-storage <socket> sends the JSON payload over Toolstream instead of
writing local output and requires --task-id. An explicitly supplied
--output is ignored in that mode. Operational logs are discarded; local
results go to stdout and failures or drop warnings go to stderr.
The process exits when the duration elapses, when the caller cancels, or when it receives SIGHUP, SIGQUIT, SIGINT, or SIGTERM.
Use from huatuo-bamai
The daemon’s AutoTracing.IRQTracing tracer invokes the irqtracing binary located next to the daemon executable itself (CoreBinDir is derived from the daemon’s own path; in the source build tree that is _output/bin/irqtracing) when its rules detect an irq/softirq spike or sustained high utilization on some CPU, passing --bpf-path <CoreBpfDir>/irqtracing.o, --target-cpu <cpu>, --duration <RunTracingToolTimeout> and --max-events-per-second-per-cpu <MaxEventsPerSecond>. MaxEventsPerSecond defaults to 1000, so raise and entry each default to 500 events/s. The CLI returns its result over Toolstream and the daemon merges it into the saved tracing data; the daemon additionally records rule, trigger_cpu, trace_duration and hit_cpus.
7 - Development
7.1 - Extending Observability
HUATUO supports three extension types: Metrics, Event, and AutoTracing. They use
the same registration framework but differ in activation, runtime cost, and
data output.
| Type |
Activation |
Data output |
Use case |
| Metrics |
Periodic collection |
Prometheus |
Continuous performance monitoring and long-term trends |
| Event |
Kernel event or threshold |
ES, local files, optional Prometheus |
Continuous operation with anomaly context capture |
| AutoTracing |
System anomaly |
ES, local files, optional Prometheus |
On-demand, higher-cost context capture |
Collection Modes
Metrics
Metrics periodically collect system state through procfs, sysfs, or eBPF and
expose it in Prometheus format. This mode supports real-time monitoring and
long-term trend analysis. Built-in collectors cover:
- CPU: sys, usr, util, load, nr_running, and related metrics.
- Memory: vmstat, memory_stat, directreclaim, and asyncreclaim.
- I/O: d2c, q2c, freeze, and flush.
- Networking: ARP, socket memory, qdisc, netstat, netdev, and sockstat.
Event
Events continuously observe kernel events or threshold conditions and preserve
kernel context when an anomaly occurs. This mode is intended for low-overhead,
always-on observation. Data is written to Elasticsearch and local files and
can also produce Prometheus metrics. Built-in events include:
- Scheduler tick interval anomalies (
sched_tick).
- Abnormal memory allocation (
memory_oom_kill).
- Soft lockups (
softlockup).
- D-state processes (
hungtask).
- Memory reclaim (
memory_reclaim_events).
- Packet drops (
dropwatch).
- Network receive latency (
net_rx_latency).
AutoTracing
AutoTracing invokes diagnostic tools after detecting a system anomaly. It is
intended for flame graphs, context snapshots, and other diagnostic operations
that are too expensive to run continuously. Results are written to
Elasticsearch and local files and can also be converted into Prometheus
metrics. Built-in capabilities include:
- CPU idle and system-time anomaly tracing (
cpuidle, cpusys).
- D-state load tracing (
dload).
- Burst memory allocation tracing (
memburst).
- Disk I/O anomaly tracing (
iotracing).
Event and AutoTracing are both Tracing modes and share the ITracingEvent
interface. They can preserve anomaly context for root-cause analysis and expose
statistics to Prometheus by also implementing Collector.
Adding Metrics
Custom Metrics collectors expose Prometheus metrics through /metrics.
Implement Collector
Create a type under core/metrics that implements Collector:
type Collector interface {
Update() ([]*Data, error)
}
type exampleMetric struct{}
func (c *exampleMetric) Update() ([]*metric.Data, error) {
return []*metric.Data{
metric.NewGaugeData("example", value, "example value", nil),
}, nil
}
Register the collector
Use FlagMetric when registering the implementation:
func init() {
tracing.RegisterEventTracing("example", newExampleMetric)
}
func newExampleMetric() (*tracing.EventTracingAttr, error) {
return &tracing.EventTracingAttr{
TracingData: &exampleMetric{},
Flag: tracing.FlagMetric,
}, nil
}
Manage BPF object
When one implementation provides both Start and Update, the methods may
run concurrently. Do not read and write a bpf.BPF interface directly in a
collector field. Use Reference and Lease from
internal/bpf/bpf_ref.go to manage the
object lifetime:
type example struct {
object bpf.Reference
}
func (c *example) Start(ctx context.Context) (retErr error) {
object, err := bpf.LoadBpf(bpf.ThisBpfOBJ(), nil)
if err != nil {
return err
}
if err := object.Attach(); err != nil {
return errors.Join(err, object.Close())
}
if err := c.object.Publish(object); err != nil {
return errors.Join(err, object.Close())
}
defer func() {
retErr = errors.Join(retErr, c.object.UnPublish())
}()
<-ctx.Done()
return nil
}
func (c *example) Update() ([]*metric.Data, error) {
lease, ok := c.object.Acquire()
if !ok {
return nil, nil
}
defer lease.Release()
items, err := lease.DumpMapByName("example_map")
if err != nil {
return nil, fmt.Errorf("dump example_map: %w", err)
}
return buildMetrics(items), nil
}
The API has these constraints:
Publish transfers ownership of the object to Reference. Do not call object.Close() directly after a successful publish.- The
Lease returned by Acquire pins the BPF object until the current Update completes. Always pair it with Release, and do not copy a Lease.
UnPublish first prevents new acquisitions, then waits for every Lease to be released, closes the BPF object, and returns the close error.- Calls to
Publish and UnPublish must be serialized. The current framework does not run Start concurrently for the same instance.
An Update that has already started can therefore finish with its original
BPF object. During shutdown or restart, Start closes that object only after
those updates complete.
Adding an Event
An Event implements ITracingEvent:
type ITracingEvent interface {
Start(ctx context.Context) error
}
type exampleEvent struct{}
func (e *exampleEvent) Start(ctx context.Context) error {
// Detect the event and capture its context.
// storage.Save writes the data to ES and local storage.
storage.Save("example", containerID, time.Now(), eventData)
return nil
}
Register it with FlagTracing:
func init() {
tracing.RegisterEventTracing("example", newExampleEvent)
}
func newExampleEvent() (*tracing.EventTracingAttr, error) {
return &tracing.EventTracingAttr{
TracingData: &exampleEvent{},
Interval: 10,
Flag: tracing.FlagTracing,
}, nil
}
To expose Prometheus metrics for the event, also implement Collector and add
tracing.FlagMetric to Flag.
Adding AutoTracing
AutoTracing and Event use the same ITracingEvent interface and registration
framework:
type exampleAutoTracing struct{}
func (t *exampleAutoTracing) Start(ctx context.Context) error {
// Capture context after the anomaly trigger fires.
storage.Save("example", containerID, time.Now(), tracingData)
return nil
}
func init() {
tracing.RegisterEventTracing("example", newExampleAutoTracing)
}
func newExampleAutoTracing() (*tracing.EventTracingAttr, error) {
return &tracing.EventTracingAttr{
TracingData: &exampleAutoTracing{},
Interval: 10,
Flag: tracing.FlagTracing,
}, nil
}
See core/metrics, core/events, and core/autotracing for complete examples
covering BPF map interaction, container metadata, storage, and Prometheus
output.
7.2 - Development Debugging
Full-Stack Integration
The development Compose configuration builds an image from the current
workspace and starts the collector, API Server, Elasticsearch, Prometheus, and
Grafana. The collector needs access to the host kernel and cgroups, so run the
command with root privileges from the repository root on a Linux host:
Compose aggregates all component logs in the foreground. After changing the
source, press Ctrl+C and run the command again. Docker reuses the toolchain
layers and Go build cache.
Remove the containers, data volumes, and development image after debugging:
sudo make compose-dev-down
This command removes the Elasticsearch data volume. Do not run it when the
integration data must be retained.
BPF Debugging
BPF code can use the bpf_dbg() and bpf_dbg_msg() macros to emit debug
information from kernel space. The macros are defined in
bpf/include/bpf_dbg.h. Debugging has separate build-time and runtime switches
and is completely disabled by default.
Add debug trace points
Each BPF source file that uses the macros must declare its own debug map:
#include "bpf_dbg.h"
BPF_DBG_MAP(native_cpu);
SEC("perf_event")
int prog(void *ctx)
{
bpf_dbg_msg(ctx, native_cpu, "enter prog");
bpf_dbg(ctx, native_cpu, "pid and addr", pid, addr, 0);
return 0;
}
bpf_dbg_msg() emits a message only. bpf_dbg() also accepts up to three
u64 arguments.
Build debug objects
Set BPF_DEBUG=1 to pass -DDEBUG_BPF to Clang:
To regenerate build artifacts without rebuilding binaries:
make BPF_DEBUG=1 gen-build
BPF_DEBUG=0 is the default. In that mode the macros expand to no-ops, and the
debug perf event array, event structure, bpf_ktime_get_ns, and
bpf_perf_event_output are not emitted into the BPF object.
Enable runtime output
After building the debug objects, pass --log-bpf-debug when starting the
profiler. The option currently applies only to the native profiler:
./profiler --type cpu --language native --log-bpf-debug ...
When loading the BPF object, bpf.NewDbg(true) rewrites the
bpf_dbg_enabled constant to 1 before LoadBpf. When it is disabled, the
verifier eliminates the branch as dead code. Each BPF object maintains an
independent switch.
Read debug output
User space emits each debug event at Debug level with these fields:
file: BPF source file.line: source line number.ts: event timestamp converted to UTC wall-clock time.msg: debug message.args: up to three u64 arguments, omitted when all values are zero.
bpf_dbg: file=native_oncpu_profiler.c line=120 ts=2026-01-11T08:30:00.123456Z msg=enter prog args=[0x1f4 0xffff8881 0x0]
Debug output requires both a build with BPF_DEBUG=1 and the runtime
--log-bpf-debug option.
7.3 - Integration Test
This integration test validates that huatuo-bamai can start correctly with mocked /proc and /sys filesystems and expose the expected Prometheus metrics.
The test runs the real huatuo-bamai binary and verifies the /metricsendpoint output without relying on the host kernel or hardware.
What the Script Does
The integration test performs the following steps:
- Generates a temporary
bamai.conf
- Starts
huatuo-bamai with mocked procfs and sysfs
- Waits for the Prometheus
/metrics endpoint to become available
- Fetches all metrics from
/metrics
- Verifies that all expected metrics exist
- Stops the service and cleans up resources
If any expected metric is missing, the test fails.
How to Run
Run the integration test from the project root:
Pass a file name to run one integration test. The optional second argument is
the repeat count and defaults to 1:
bash integration/run.sh test_metrics_exclude_filter.sh 10
or
Prerequisites and Results
Both suites use integration/run.sh, which defaults to integration.
e2e/run.sh forwards to --suite e2e. Existing make integration, make e2e,
and single-case entry points remain available:
bash integration/run.sh --suite e2e
bash integration/run.sh --suite e2e test_metrics.sh 2
bash e2e/run.sh test_metrics.sh 2
Both suites run in separate UTS and mount namespaces with hostname huatuo-dev
and private mount propagation. Integration cases start their own services;
e2e starts the baseline bamai before each case, then stops it and checks its log.
Integration removes workspaces after passed or skipped cases and preserves them
on failure. E2E retains its workspaces.
The runner checks only that _output exists, without checking individual
project binaries or BPF objects. Run
make build before invoking a runner directly. An existing directory does not
prove that the build is complete; missing artifacts fail when used.
Use the same helper for commands on PATH and executable file paths. Missing
commands skip the case:
require_commands jq curl ss
require_commands "${PROFILER_TOOL_DIR}/bin/asprof"
Use require_readable for input files such as certificates. Unreadable inputs
skip the case and report the affected path:
require_readable "${KUBELET_CERT}" "${KUBELET_KEY}"
skip prints its reason and exits with 77; EXIT cleanup still runs. The runner
classifies 0 as PASS, 77 as SKIP, and other statuses as FAIL. Cleanup failures also
count as FAIL. A suite containing only passed and skipped cases returns 0.
A failure stops subsequent cases and prints the results collected so far.
Each execution counts separately, including repetitions. For example:
summary: total=5 passed=3 skipped=2 failed=0
When root privileges or namespace commands are unavailable, both suites count
all selected executions as SKIP.
On Failure
- The
huatuo-bamai service metrics and logs are printed to stdout
- The temporary working directory is kept for debugging
On Success
- Output the list of successfully validated metrics
Background Process Cleanup
stop_and_wait_by_pid PID [TIMEOUT] stops and waits for a child process,
returning its exit status. An omitted or empty PID returns success immediately,
so callers can pass an initialized PID variable without checking it first.
Clear the variable after waiting; use || true in best-effort cleanup and
assert the exit status when it is part of the test contract.
Network Namespace Helpers
Network tests can source integration/lib_namespace.sh after lib.sh:
namespace_setup NAME creates one network namespace and exposes its name as
NETNS. The caller brings up lo and configures any addresses it needs.namespace_setup_with_pair PREFIX SERVER_ADDR CLIENT_ADDR [PREFIX_LENGTH]
creates two namespaces connected by a veth pair, configures their addresses,
and brings up the interfaces. The prefix length defaults to 24. Names and
addresses are exposed through NETNS_SERVER, NETNS_CLIENT,
NETNS_VETH_SERVER, NETNS_VETH_CLIENT, NETNS_SERVER_ADDR, and
NETNS_CLIENT_ADDR.namespace_cleanup deletes the namespaces created by either helper and
clears their state. Call it from the test’s EXIT cleanup after stopping
processes in those namespaces. Repeated cleanup calls are supported.
How to Add New Metrics Tests
1: Add or Update Fixture Data
If the metric depends on /proc or /sys, add or update mock data under:
The directory structure should match the real kernel filesystem layout.
2: Add Expected Metrics
Create a new file under:
integration/fixtures/expected_metrics/
├── cpu.txt
├── memory.txt
└── ...
Each non-empty, non-comment line represents one expected Prometheus metric line
and must match the /metrics output exactly.
New *.txt files are automatically picked up by the test.
3: Run the Test
The test fails if any expected metric is missing or mismatched.
7.4 - Debug a VM in GitHub Actions
Use the OS Distro QEMU Test workflow to test a branch in a supported Linux
VM. No local VM setup is required.
Prepare Your Fork
- Fork the repository and enable workflows on the fork’s Actions page.
- Add an SSH public key to your
GitHub account. Only the user who starts
the workflow can connect.
- Push the branch that you want to debug to your fork.
Start a VM
- Open Actions > OS Distro QEMU Test > Run workflow in your fork.
- Select your branch.
- Keep the default
ubuntu24.04, enter comma-separated distributions, or
use all to select every supported distribution.
- Select when to retain the VM and the retention time under Debug VM.
- Run the workflow and open its
Test in VM job.
If Run workflow is missing, sync the fork’s default branch first. GitHub
only lists manual workflows that exist on the default branch.
Use Before test to inspect or change the VM before tests run. Use
After test on failure to investigate a failed test, or After test
always to keep the VM regardless of the result.
Connect
Open the job’s Debug VM: Retain ... step and follow its commands:
- Run the displayed SSH command in your local terminal. This connects
to the GitHub runner.
- On the runner, run the displayed
ssh -i ... root@<VM_IP> command to enter
the VM.
The commands already contain the correct key path and VM address.
Finish
Exit the VM, then release the workflow from the runner:
cd "$GITHUB_WORKSPACE"
touch continue
The workflow continues to the tests or cleanup. Disconnecting SSH alone does
not release it; otherwise it waits until the selected retention time expires.
7.5 - BPF ABI Guide
The C structures on the BPF side are the source of truth for the perf event
ABI. Go types are generated automatically from BTF in the BPF objects. Do not
maintain equivalent structures manually.
Conventions
Each ABI domain maps to one C header and one generated Go file:
| Item |
Convention |
| Domain name |
<domain> |
| C header |
bpf/include/abi/<domain>_types.h |
| C structure prefix |
<domain>_ |
| Generated Go file |
internal/bpf/abi/<domain>_types_generated.go |
<domain> must start with a lowercase letter and contain only lowercase
letters, digits, and underscores. Avoid domains with overlapping prefixes,
such as net and net_rx.
Implementation
The following example creates the sample domain.
Create bpf/include/abi/sample_types.h:
// Copyright 2026 The HuaTuo Authors
//
// Licensed under the Apache License, Version 2.0 (the "License");
// you may not use this file except in compliance with the License.
// You may obtain a copy of the License at
//
// http://www.apache.org/licenses/LICENSE-2.0
//
// Unless required by applicable law or agreed to in writing, software
// distributed under the License is distributed on an "AS IS" BASIS,
// WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
// See the License for the specific language governing permissions and
// limitations under the License.
#ifndef __BPF_ABI_SAMPLE_H__
#define __BPF_ABI_SAMPLE_H__
#include "bpf_abi.h"
#define SAMPLE_DATA_LEN 4
struct sample_detail {
u32 code;
u8 data[SAMPLE_DATA_LEN];
};
struct sample_event {
u64 kernel_observed_ns;
struct sample_detail detail;
u32 tgid;
u8 kind;
u8 pad[3];
};
BPF_ABI_EXPORT(sample_detail);
BPF_ABI_EXPORT(sample_event);
#endif /* __BPF_ABI_SAMPLE_H__ */
Requirements:
- Structure names must use the
<domain>_ prefix.
- Every structure that requires a generated Go type must call
BPF_ABI_EXPORT(<type>), including nested structures.
- The header must contain only ABI types and related constants. Do not add BPF
programs, maps, or business logic.
- Array lengths must be compile-time constants and remain consistent across
all BPF compilation units.
The ABI header depends on base types such as u8 and u16. Include it after
vmlinux.h and the project base headers:
#include "vmlinux.h"
#include "bpf_common.h"
#include "abi/sample_types.h"
Use the ABI structure directly when emitting a perf event:
struct sample_event event = {};
event.kernel_observed_ns = bpf_ktime_get_ns();
event.tgid = bpf_get_current_pid_tgid() >> 32;
event.kind = kind;
bpf_perf_event_output(ctx, &events, COMPAT_BPF_F_CURRENT_CPU,
&event, sizeof(event));
The event must be zero-initialized to prevent uninitialized padding from being
written to the perf buffer. Any structure passed to bpf_perf_event_output
must be defined in an ABI header.
3. Generate and Use the Go Type
Run the following command from the repository root:
The generated file is located at:
internal/bpf/abi/sample_types_generated.go
Reference the generated type directly from Go code:
import "github.com/ccfos/huatuo/internal/bpf/abi"
var event abi.SampleEvent
if err := reader.ReadInto(&event); err != nil {
return fmt.Errorf("read sample event: %w", err)
}
The generated file contains the structure, the SampleEventSize size
constant, and layout assertions based on unsafe.Sizeof and
unsafe.Offsetof. Generated files are read-only. Do not edit them manually.
Types and Layout
| Type |
Support |
| Fixed-width integers of 1, 2, 4, or 8 bytes |
Supported |
| Fixed-length arrays with a nonzero length |
Supported |
| Nested structures that meet the same constraints |
Supported |
typedef with a supported target type |
Supported |
Pointers, union, enum, and floating-point types |
Unsupported |
Bit fields and _Bool |
Unsupported |
| Zero-length and flexible arrays |
Unsupported |
| Recursive structures, overlapping fields, or non-byte-aligned structures |
Unsupported |
Layout requirements:
- Use fixed-width integers such as
u8, s16, u32, and s64.
- Order fields according to their alignment requirements. Use
u8 pad[N] to
make padding explicit when necessary.
- Do not use platform-dependent types such as
long or unsigned long.
- Do not use
__attribute__((packed)) to bypass layout validation.
- If a structure with the same name appears in multiple BPF objects, its
fields, offsets, and size must match exactly.
C names are converted to exported Go names by splitting on underscores. For
example, sample_event becomes SampleEvent, and kernel_observed_ns becomes
KernelObservedNS. Field semantics and cross-layer names follow
Event Field Naming. Avoid C names that map to the
same Go name, such as sample_id and sample_i_d.
Verification
Run the following commands after adding or modifying an ABI:
make gen-build
go test ./build/bpfabi-tool
make check
Add a decoding test for each new perf event. At a minimum, cover:
- Integer boundary values and native byte order.
- Nested structures and the first and last array elements.
- Fields before and after padding.
- The sample size and the generated
<GoType>Size constant.
Common Errors
| Error |
Check |
has no "<domain>_" btf anchors |
Confirm that a BPF source includes the header and that the type calls BPF_ABI_EXPORT |
without matching abi header |
Confirm that the header name matches the structure prefix and that domain prefixes do not overlap |
differs between objects |
Check whether conditional compilation, array length macros, or included headers change the layout |
go offset is ... btf offset is ... |
Reorder fields or add explicit padding; do not use packed |
go type name ... collides |
Rename C types or fields that map to the same Go name |
7.6 - Challenges of TCP Retransmission and dropwatch Correlation
This document describes the evidence boundaries and the implementation of
local correlation. The two event streams share no common event ID, so
correlation can only make conservative inferences from the namespace, the
4-tuple, TCP sequence/ACK evidence, and monotonic time.
1. Result Semantics
| Result |
Meaning |
software |
A host software drop was found that satisfies all strict conditions and has not been consumed yet. |
hardware |
A devlink DROP trap record was found that satisfies the same strict conditions. |
unknown |
No strict match was found, or the matched record’s source enumeration is unknown; correlation_reason explicitly distinguishes matched from unmatched terminal outcomes. |
A no-match does not prove that the problem is in the network or in hardware.
The drop may have happened before capture started, in another network
namespace, or the record may have been delivered without the TCP matching
fields.
Shutdown processes the waiting entries with a single time snapshot: expired
entries receive warmup or wait_timeout, and entries that have not expired
receive interrupted. All of these unmatched results report
drop_location=unknown plus independent diagnostics.
2. Three Operating Scenarios
tcpshark --bpf-path <tcp_retransmit.o> only captures and directly outputs
retransmissions.tcpshark --with-dropwatch --bpf-path-dir <dir> loads tcp_retransmit.o
and net_dropwatch.o inside one process, which owns both perf inputs, the
timer, the output, and shutdown.- The huatuo-bamai standalone dropwatch still runs independently through
cmd/dropwatch, outputs only raw DropWatchTracing, and shares no state
with the embedded source.
All three retransmit hooks use the synthetic L3 filter in both modes.
Correlation mode uses only EventTracing.TCPRetransmit.Filter; an empty value
is normalized to tcp, and the same expression is passed to both BPF objects.
Expressions that depend on Ethernet addresses and cannot run equivalently on
synthetic L3 input are rejected before startup.
EventTracing.Dropwatch.Filter controls only standalone dropwatch.
Both commands use HardwareAuto to auto-detect devlink trap support. When the
tracepoint is unavailable, they log a warning and continue software capture;
when it is available, they accept only driver-reported DROP traps.
--device / --device-excluded share their names with standalone dropwatch
and are mutually exclusive; they filter only the embedded source’s software and
hardware records and require --with-dropwatch. The retransmit input still
uses the shared L3 filter.
Drop source and reason are resolved uniformly by
internal/dropwatch.ResolveMetadata. Software reasons are looked up in a BTF
table loaded once per session; unknown values are decimal numbers, and kernels
without support yield NOT_SUPPORTED. Hardware reasons and groups come from
the trap name and the trap group respectively and do not consult the software
reason table. The reader keeps independent source and reason strings and does
not borrow the reusable ABI buffer. After a strict match, the output carries
drop_source, drop_reason, and drop_reason_group; a no-match omits these
fields and outputs the single correlation terminal reason plus independent
diagnostics. drop_location echoes drop_source on a match and is unknown
otherwise; it expresses the correlation classification and differs from the
standalone dropwatch kernel address. An unknown source is never inferred from a
reason or a stack. Strict matching cannot be established when a hardware record
lacks the namespace or TCP matching fields.
3. The Two Time Constraints
dropwatch and retransmit use different perf readers, and events can also come
from different CPUs, so the userspace arrival order does not equal the kernel
occurrence order:
CPU 2: drop monotonic_ns=180, held back in the dropwatch ring
CPU 0: retransmit monotonic_ns=200, reaches userspace first
userspace: retransmit(200) -> drop(180)
The implementation uses two windows on different dimensions:
retransmitRetentionDuration = 100 * time.Millisecond
maxDropToRetransmitAge = time.Second
- 100 ms is the userspace out-of-order delivery budget. When a retransmission
arrives first, it enters the wait queue; if it is still unmatched when the
wait expires, it is reported as
unknown. Records whose deadline has already
passed are finalized before any new event is processed; the timer is only
responsible for waking the loop and does not define the deadline semantics.
- 1s is the causal candidate age, judged with the BPF
kernel_observed_ns. A
candidate must satisfy:
drop.kernel_observed_ns <= retransmit.kernel_observed_ns
retransmit.kernel_observed_ns - drop.kernel_observed_ns <= 1s
observed_timestamp is userspace wall time, affected by scheduling and system
time adjustments, and does not participate in matching. The fixed 1s is the
currently supported contract and is not a theoretical bound for all Linux RTOs;
results outside the window stay unknown.
4. Bounded State
Waiting retransmissions and not-yet-matched drops share the in-package generic
store store[T], each holding an independent instance. The container is
responsible only for capacity, TTL, the flow index, and deletion; strict
matching and result finalization belong to the correlator.
type storeEntry[T any] struct {
value T
flow *flowKey
deadline time.Time
sequence uint64
node *list.Element
}
type store[T any] struct {
byDeadline list.List
byFlow map[flowKey][]*storeEntry[T]
capacity int
ttl time.Duration
nextSequence uint64
}
| Instance |
Stored value |
Capacity |
TTL |
retransmitStore |
waitingRetransmit, inlined in the entry |
1024 |
100ms |
dropStore |
*dropEvent |
4096 |
1s + 100ms |
waitingRetransmit contains only the raw event, the matching fields, and the
cross-namespace candidate flag; it no longer holds a list node, a deadline, or
an independent ID. Drops likewise need no extra cache wrapper type. The list’s
Element.Value and the flow bucket reference the same *storeEntry[T], and
the entry’s node points back to its list element. The entry references the
flow from the business data, which is never modified, avoiding a duplicate
address. Deletion unreferences both indexes at once and clears the tail of the
flow slice; an empty bucket is removed after its last entry is deleted.
The flow index is keyed by the canonical order of the two AddrPort values, so
both directions share one bucket; the original direction is kept in the
business data for strict matching. The namespace is not part of the index key,
so similar cross-namespace candidates can still set the diagnostic flag. Match
scans and slice deletions are O(k), where k is the number of candidates for
that flow; locating the earliest deadline and unlinking from the list are O(1).
Each instance has a fixed TTL, and the correlation loop passes a monotonically
non-decreasing processing time, so list insertion order is also deadline order.
The list serves expiry cleanup and capacity eviction and exposes no FIFO
consumption interface to business code. When the wait capacity is full, the
record with the earliest deadline is finalized as queue_full; when the drop
capacity is full, the candidate with the earliest deadline is evicted directly.
Causal decisions still use kernel_observed_ns.
The two readers deliver events through unbuffered channels, and the container
is accessed only by a single correlation loop, with no locks and no separate
cleanup goroutine. One timer always takes the earliest deadline of the two
instances, so cleanup happens on schedule even when only the drop cache holds
data and no retransmission is waiting. On every input and timer wakeup, expired
entries are cleaned first, then matching and capacity checks run;
now >= deadline means expired. The 100 ms is the matching deadline; blocking
in synchronous output can still delay actual cleanup and result delivery.
5. Strict Matching
A forward segment candidate requires:
- the same network namespace, address family, and direction 4-tuple;
- a drop no later than the retransmission, with a time difference of at most 1s;
- an overlap between the TCP SYN/data/FIN sequence range and the retransmitted
range;
- RST and unsupported retransmission types produce no forward match.
A reverse ACK candidate uses the reverse 4-tuple and requires the ACK to cover
the retransmitted sequence end. SYN and SYN-ACK use their own stricter ACK/SYN
conditions.
Among multiple drop candidates, the largest drop.kernel_observed_ns is
selected first; on a time tie, the larger insertion sequence number wins. When
a drop arrives late, it selects the strictly matched retransmission with the
smallest insertion sequence number while scanning the remaining candidates to
record each retransmission’s namespace-match status. After a strict match, the
entry is removed from both the deadline and flow indexes immediately and can be
consumed only once. Forward segment and reverse ACK share the flow index; the
namespace is checked first, then the packet and time conditions.
When a drop with the same namespace appears on the same flow, netNamespace
is set to true; the flag is retained even when time or sequence fails the
strict conditions, and later non-matching candidates do not clear it. A strict
match always yields true. With no candidates, only other namespaces, or an
incomparable namespace, the value is false, meaning no match was observed; it
does not establish that the namespaces differ. The output preserves this
status through NetNamespace; the JSON and text field is
matched_net_namespace, omitted when false.
6. Mutually Exclusive Correlation Outcomes
types.CorrelationReason is a string type; each correlation outputs exactly
one correlation_reason:
| Go constant |
JSON value |
Meaning |
CorrelationMatched |
matched |
Strict match succeeded, including drops whose source is unknown. |
CorrelationUnsupported |
unsupported |
The current rules cannot handle this retransmission; it does not enter the wait queue. |
CorrelationWarmup |
warmup |
The wait expired without a match, and the retransmission predates source readiness. |
CorrelationWaitTimeout |
wait_timeout |
The wait expired without a match, and the retransmission occurred at or after source readiness. |
CorrelationQueueFull |
queue_full |
The retransmission was evicted before expiry because the wait queue was full. |
CorrelationInterrupted |
interrupted |
The correlation loop exited, and the unexpired wait was interrupted early. |
Each terminal branch assigns correlationResult.reason directly. The output
side uses this enum to classify results and validates that matched must carry
a drop while the other five outcomes must not; empty values, unknown values, or
contradictory combinations return an error. Correlation-disabled output omits
the field; once correlation is enabled, every finalized event contains one
valid terminal outcome. The scalar field replaces the previous reason array;
tools and receivers migrate in lockstep.
On wait expiry, the terminal outcome is chosen by the retransmission’s kernel
time: earlier than source readiness yields warmup, at or after readiness
yields wait_timeout, including waits under 1s after readiness. The 1s
drop-to-retransmit limit applies only to candidate matching and plays no part
in the warmup decision. Userspace processing delay does not change the
classification. This decision runs only in the expiry branch; strict matches,
unsupported events, queue evictions, and early interruptions keep their own
reasons. Warmup neither blocks matching nor ends the wait early.
matched_net_namespace remains an independent diagnostic flag: a drop with the
same namespace was observed on the same flow, independent of the packet and
time conditions; it cannot substitute for correlation_reason=matched.
The flag can coexist with rate limiting and loss counters without changing the
single terminal outcome. Drops that fail normalization and drop-cache capacity
evictions do not directly end a retransmission wait and do not produce a
retransmission-level reason.
7. Perf Status
The status consists of three independent channels; each reports on its own and
none is summed with another:
perf_lost: the cumulative per-CPU bpf_perf_out_dropwatch map (the common
perf output accounting facility bpf_perf_output.h); BPF increments it when
bpf_perf_event_output returns a negative value (for example, when the
current CPU has no attached reader).lost_samples: the userspace cumulative count of ring buffer overflows
reported by PERF_RECORD_LOST, visible only while the reader runs, and
queryable through ReadStatus once the lost records are processed.rate_limited: the total_missed value of the rate-limit status map
bpf_rlimit_dropwatch.
On success, ReadStatus sets HasMapCounters=true, serialized as
map_counters_available=true. On error the flag is false and PerfLost and
RateLimited are zero, meaning unavailable rather than an absence of loss or
rate limiting; LostSamples remains valid and the output keeps that snapshot.
These values are per-instance cumulative counters, sampled separately by the
map and the reader, and cannot explain why any individual retransmission failed
to match.
Userspace sums perf_lost across all CPUs and returns the current snapshot each
time; it does not check for counter regressions or uint64 addition overflow.
This status describes evidence integrity only and never promotes a no-match
into a deterministic network classification. The old active-epoch, dual-slot,
inflight, frontier, and drain watermark mechanisms have been removed.
The correlation side computes the TCP sequence span from the IPv4 total length
or the IPv6 payload length. Under GSO/offload the IP header length may not
cover the whole skb; matching is not widened on that basis today.
The dropwatch hot path is:
software: hardware marker lookup/delete -> device/pcap filter
-> status map lookup -> bpf_ktime_get_ns() -> rate limit -> perf output
hardware: device/pcap filter -> status map lookup -> bpf_ktime_get_ns()
-> rate limit -> perf output
Consequently, events rejected by the filter pay no status lookup, event-time
helper, or counter update cost; a software drop first consumes any existing
hardware dedup marker so rejected kfree paths leave no marker behind.
8. Shutdown
tcpshark uses one errgroup.WithContext to manage the retransmit rate-limit
reader, the retransmit reader, the embedded dropwatch reader, and the
correlation loop. All command workers share the same groupCtx; when any
worker returns an error the rest are canceled, and Wait returns the first
worker error. Resource close errors are merged by each owner with
errors.Join; shutdown no longer maintains a private error-aggregating group.
internal/dropwatch.Tracer owns the dropwatch object, the readers, and the
rate-limit alert worker. The instance context derives from groupCtx; a
rate-limit alert failure cancels instance reads, and the concrete error is
returned by Close. ReadInto checks close and cancellation causes before
reading; once the underlying read is entered, the read result is returned
as-is and is no longer overwritten by a subsequent close or cancellation.
ReadStatus can still read the final counters after the context is canceled.
Close first cancels the instance, detaches, and closes the event and alert
readers, then waits for the alert worker to exit, and finally releases the
object; closing the alert reader wakes an idle read, so no polling deadline
needs to elapse. The status type is types.DropwatchStatus, the output field
is drop_perf_status, and it includes the map-counter availability flag.
On normal completion or worker failure:
- Cancel the shared
groupCtx;
- the two
ReadInto readers and the correlation loop exit;
- records still in the dropwatch perf ring that were never handed to the
correlator are no longer read;
drainRetransmits(now) is called to finalize expired entries with the same
time snapshot, then clear the unexpired ones, writing output in deadline
order;- after all workers exit, the dropwatch and retransmit Tracers are closed,
collecting internal alert-worker and resource-release errors;
- finally the socket output is finished; the caller-provided io.Writer is not
closed by the session.
At shutdown, expired entries report warmup or wait_timeout and unexpired
entries report interrupted, all retaining drop_location=unknown, the
diagnostic flags, and the perf status. Already matched or already evicted
events are never finalized twice. Tail drops can still be lost, so a
retransmission that could have matched may also be ended early.
9. File Responsibilities
cmd/tcpshark/
├── main.go # signals, version, CLI entry point
├── cli.go # argument validation, path and filter normalization
├── run.go # global BPF lifecycle, timeout, feature dispatch
└── retransmit/ # retransmit feature package
├── config.go # Config, RunConfig
├── run.go # Run: resource assembly, execution, and cleanup
├── tracer.go # Open, ReadInto, Close, and the rate-limit worker
├── bpf_load.go # loadBPF, attachBPF, and probe selection
├── event_reader.go # dual-stream reading, conversion, and channel delivery
├── correlation_loop.go # select, timer, and exit finalization
├── correlation.go # correlation state machine, expiry finalization
├── correlation_match.go # candidate selection, consumption, and namespace-match status
├── match.go # matching types: namespace/flow/sequence/ktime
├── store.go # entry storage, flow index, capacity and expiry management
├── event.go # conversion of the two ABI record types
├── classify.go # retransmission classification
├── correlation_output.go # status completion, symbolization, correlation output fields
└── output.go # text, JSON, and socket output
The top level runs the retransmit feature through
retransmit.Run(ctx, *RunConfig) and does not touch ABI records, channels, the
correlation timer, or status counters. The CLI validates scalars and argument
combinations first, then compile-checks the filter. When a non-empty
--output-storage is set, the --output value is not validated; if the latter
is given explicitly, a note on stderr says it is ignored. Without storage, only
json or text is accepted. RunConfig.Tracing is the capture configuration;
when Dropwatch is nil, it reads and outputs directly; when non-nil, it uses two
read workers and a single correlation loop. The correlation capability is a
composition of the retransmit feature, not a general capture framework.
Run builds the output before attaching probes and, before returning, completes
waiting for all session workers, final finalization, Tracer closing, and output
completion. Configuration failures, cancellation, and run failures all release
the resources already acquired. Draining kernel buffers at close is not
guaranteed. Plain mode creates no correlation channels or timers.
retransmit.Tracer still owns only the retransmit BPF object, the readers, and
the rate-limit alert worker; event conversion, classification, correlation, and
output belong to the feature session in the same package and stay out of the
Tracer. An Open failure rolls back every acquired resource; Close is still
required after the session context is canceled. A rate-limit worker failure
cancels the capture, and the original error is also preserved by Close. Once
reading has started, ReadInto keeps the underlying result as-is and no longer
checks close or cancellation state. Close may interrupt a read, but callers
must serialize Close calls. Process-level bpf.Init/Shutdown and the run
timeout are managed centrally at the command layer.
The correlator uniformly cleans up expired candidates while handling each input
and timer wakeup; the caches do not repeat expiry checks. The correlator
returns match evidence, a single terminal outcome, and diagnostic flags, and
does not modify output fields; correlation_output.go builds the final output in
one place. Each non-empty output batch reads the dropwatch status once at its
entry, and empty batches read nothing; symbols are resolved only for matched
drops. Status is read even when the whole batch is matches; on a read failure
the batch is still written out and the status error is returned afterwards; if
the write fails, batch output stops and the write error is merged with the
status error. Only no-match events carry the status snapshot and diagnostic
flags; a failed read still keeps valid reader counters, and matched events do
not carry these fields. Internal retransmission events keep only the ABI record
and the observedAt from a successful read; the wait queue does not store full
presentation objects. Matching constructs netip addresses directly from ABI
addresses and uses the ABI event enums, with no string conversions.
IPv4-mapped IPv6 is still normalized to IPv4. Single-event reads handle
lost-record retries and read times in one place; plain mode reuses the event
and outputs synchronously, while correlation mode reads into a dedicated event
before sending it, avoiding overwriting data that is still waiting. run.go
creates the channels and starts the read workers in one place, and the sender
closes the channels; read functions start no goroutines and use neither
consumer callbacks nor borrowed-event contracts. TCPRetransmitTracing is
constructed only at final output; ObservedTimestamp uses the original read
time, not the correlation end time. The ABI, SYNACK flag completion, and
matching rules stay unchanged.
cmd/tcpshark/retransmit does not enforce a Go internal import restriction;
the convention is that only tcpshark uses it, and it does not depend back on
the command layer. The capture implementation shared by the two commands lives
in:
internal/dropwatch/
├── config.go # Config, HardwareMode, and configuration validation
├── tracer.go # Tracer API, newTracer resource takeover, rollback, and worker lifecycle
├── load.go # loadBPF, attachBPF: loading, map/reader preparation, and probe attachment
├── netdev.go # device filtering and map configuration
├── status.go # ReadStatus: output failures, ring loss, and rate-limit counters
├── reason.go # LoadReasonNames: kernel BTF reason table and numeric fallback
├── metadata.go # ResolveMetadata: source, software reason, hardware trap/group
└── decode.go # DecodePacket: ABI header adaptation and packet.Parse
Open(ctx, *Config) returns a concrete *Tracer. Each instance allows only
one ReadInto caller; status reads and closing may run concurrently, but
Close on the same instance must be serialized by the resource owner. The
first close returns cleanup errors; later calls return nil, never retry
cleanup, and never return the first error again. The caller owns global BPF
initialization and shutdown, and must close the Tracer after the final
finalization. DecodePacket results do not borrow the original record memory.
Symbolization and the DropWatchTracing presentation conversion stay in the
standalone command; TCP correlation keeps KernelObservedNS, the namespace,
stack PCs, and the resolved drop source and reason directly from the ABI. No
general BPF consumption-loop interface is introduced.
7.7 - Time Format Contract
Canonical timestamp format for integrations and storage.
HUATUO serializes timestamps in UTC with fixed nanosecond precision:
2006-01-02T15:04:05.000000000Z
For example, an event captured at half past midnight on 22 July 2026 is written as:
2026-07-22T00:30:00.123456789Z
Why fixed UTC precision
- Every host emits the same timezone (
Z), so distributed queries do not need timezone-specific handling.
- The nine fractional digits keep the string width fixed. Lexical ordering therefore matches chronological ordering, which is useful for log files and keyword-indexed storage.
- Nanoseconds preserve the precision supplied by Go’s
time.Time and by event-tracing pipelines.
Integration guidance
When producing data for HUATUO, format times with the canonical helper:
timestamp := timeutil.FormatUTC(time.Now())
When consuming timestamps, use timeutil.Parse. It accepts the canonical format and RFC 3339 timestamps with zero to nine fractional digits so that legacy records remain readable. The returned value is always normalized to UTC.
Do not compare timestamps as strings unless both values have been generated by FormatUTC; third-party RFC 3339 values can have variable fractional precision or non-UTC offsets.
7.8 - Event Field Naming
Event fields must use consistent semantics before following the naming
conventions of each layer. The same name must not represent different concepts.
Layer Rules
| Layer |
Rule |
Example |
| BPF C |
Names reflect the original kernel semantics and units |
tgid, kernel_observed_ns |
| Go |
MixedCaps; initialisms remain uppercase |
TGID, KernelObservedNS |
| JSON |
Use user-facing statistical semantics |
pid, observed_timestamp |
| CLI flags |
Lowercase kebab case |
--pid, --cpuid |
| CLI text and headers |
Use standard uppercase initialisms |
PID, CPU, COMM |
CPUs and Tasks
| Concept |
Definition |
BPF C |
Go |
JSON |
CLI |
| Logical CPU number |
Number returned by bpf_get_smp_processor_id() |
cpu |
CPU |
cpu |
--cpu, CPU |
| Process ID |
Userspace process identifier, namely the Linux TGID |
tgid |
TGID in raw events; PID in output |
pid |
--pid, PID |
| Thread ID |
Linux task PID |
tid |
TID |
tid |
--tid, TID |
| Parent process ID |
Parent process TGID |
parent_tgid |
ParentTGID, or ParentPID in the output layer |
parent_pid |
PPID |
| Task comm |
Kernel task comm, which may be a thread name |
comm |
Comm |
comm |
COMM |
Time and Numeric Units
| Concept |
Definition |
BPF C |
Go |
JSON |
| Raw kernel observation time |
CLOCK_MONOTONIC nanoseconds, excluding system suspend |
kernel_observed_ns |
KernelObservedNS |
Internal correlation only; not serialized |
| Kernel observation time |
Raw monotonic timestamp converted to UTC |
Not applicable |
KernelObservedTimestamp |
kernel_observed_timestamp |
| Userspace observation time |
UTC time when the event producer observes the event in userspace |
Not applicable |
ObservedTimestamp |
observed_timestamp |
| Unix nanosecond time |
Unix time in nanoseconds |
timestamp_ns |
TimestampNS |
timestamp_ns |
| Nanosecond duration |
Difference between two time points |
<name>_ns |
<Name>NS |
<name>_ns |
| Nanosecond threshold |
Duration corresponding to a trigger condition |
<name>_threshold_ns |
<Name>ThresholdNS |
<name>_threshold_ns |
| Count |
Unitless cumulative value |
<name>_count |
<Name>Count |
<name>_count |
| Bytes |
Data size, not bit count |
<name>_bytes |
<Name>Bytes |
<name>_bytes |
Containers, Cgroups, and Network Namespaces
| Concept |
BPF C |
Go |
JSON |
CLI |
| Container ID |
container_id |
ContainerID |
container_id |
--container-id, CONTAINER_ID |
| Cgroup ID |
cgroup_id |
CgroupID |
cgroup_id |
CGROUP_ID |
| Cgroup CSS address |
<subsystem>_css_addr |
<Subsystem>CSSAddr |
<subsystem>_css_addr |
<SUBSYSTEM>_CSS_ADDR |
| Network namespace inode |
netns_inum |
NetNamespaceInum |
net_namespace_inum |
NETNS_INUM |
| Network namespace cookie |
netns_cookie |
NetNamespaceCookie |
net_namespace_cookie |
NETNS_COOKIE |
| Network device index |
ifindex or <name>_ifindex |
Ifindex or <Name>Ifindex |
ifindex or <name>_ifindex |
IFINDEX |
Kernel terms inum and ifindex remain single words in Go. Do not split them
into INum or IfIndex. User-facing Go and JSON fields expand netns to
NetNamespace and net_namespace.
Observation times and compatibility
kernel_observed_timestamp, observed_timestamp, and uploaded_timestamp
represent kernel observation, userspace observation, and storage write time.
Kernel observation means the hook execution time, which may differ from the
onset of a physical hardware error or network fault.
Document stores UTC timestamps at the top level and excludes
kernel_observed_ns. Producers without kernel timestamps and older
documents omit kernel_observed_timestamp; userspace or upload timestamps must
not fill it. Historical RAS documents used observed_timestamp for kernel
observation, so their userspace observation time cannot be reconstructed.
tcpshark and dropwatch use kernel_observed_timestamp for kernel observation
time in JSON and text output. Upgrade tools and Agent together. Existing
documents are not rewritten or backfilled. Conversion requires the same host,
boot, and host time namespace. Historical events spanning a realtime clock
step or system suspend cannot be mapped exactly to UTC from monotonic time alone.
UTC conversion caches the monotonic-to-realtime offset. The first call one hour
after the last successful sample refreshes it; ordinary calls do not extend
its lifetime. Sampling failures are returned and retried on the next call.
Realtime clock steps and system suspend do not trigger an early refresh; the
offset is updated on the first call after the cache expires.
8 - FAQ
Metrics
-
Why do the memory_others_* metrics (e.g. directstall_time) have no data?
The memory_others collector reads memory cgroup extension interfaces provided by the Didi Cloud custom kernel (memory.directstall_stat, memory.asynreclaim_stat, memory.local_direct_reclaim_time). Mainline and common distribution kernels do not expose these interfaces, and no loadable kernel module provides them, so these metrics are simply not emitted on standard kernels — this is expected behavior.
To observe container direct reclaim behavior on standard kernels, use the eBPF-based memory_reclaim_container_directstall metric instead; see the Memory System section in “Key Features / Kernel-Wide Insight”.
9 - Contribute
9.1 - Code Contributions
Contributing to HUATUO
Thank you for your interest in contributing to HUATUO! This guide will help you get started.
Ways to Contribute
There are many ways to contribute to HUATUO:
- Code — Fix bugs, add features, improve performance
- Documentation — Improve docs, translate content, write tutorials
- Testing — Write unit tests, integration tests, report bugs
- eBPF — Add new kernel probes, improve kernel compatibility
- Review — Review pull requests from other contributors
Development Environment
Prerequisites
| Tool |
Requirement |
Note |
| Go |
1.24+ |
The project is written in Go |
| Linux |
Kernel 4.18+ |
eBPF programs require a Linux kernel |
| Clang/LLVM |
Any recent version |
Required for compiling eBPF C programs |
| Kernel headers |
linux-headers |
Required for BPF compilation |
| Docker |
(optional) |
For containerized development |
| Git |
Any recent version |
For version control |
Clone the Repository
# Fork the repository on GitHub, then:
git clone https://github.com/YOUR_USERNAME/huatuo.git
cd huatuo
git remote add upstream https://github.com/ccfos/huatuo.git
Build and Test
Build
make build # Build BPF programs and Go binaries
make gen-build # Regenerate BPF and generated Go artifacts
make docker-build # Build Docker image
Full Container Integration
Build the development image from the current source and start the collector,
API Server, Elasticsearch, Prometheus, and Grafana:
Stop the environment and remove its containers, volumes, and local development
image:
Test
make test # Run all tests
make unit # Run unit tests only
make check # Run linting and formatting checks
Note: make test requires /etc/kubernetes/pki for E2E tests. If you don’t have a K8s cluster, use make unit instead.
To test or debug on another distribution without a local VM, use
GitHub Actions VM debugging.
Contribution Workflow
1. Find or Create an Issue
- Check the open issues for bugs and features
- If you find an unassigned issue, comment to ask for assignment
- If you have a new idea, create an issue first
2. Create a Branch
git checkout -b fix/short-description
# or: git checkout -b feat/short-description
# or: git checkout -b docs/short-description
Branch name prefixes:
| Prefix |
Purpose |
fix/ |
Bug fixes |
feat/ |
New features |
docs/ |
Documentation |
refactor/ |
Code restructuring |
test/ |
Adding tests |
3. Make Your Changes
- Keep changes focused on a single issue
- Add or update tests to cover your changes
- Run
make check to ensure code style compliance
- Run
make unit to verify tests pass
4. Commit Your Changes
Use conventional commits:
git commit -s -m "fix(scope): brief description
Detailed explanation if needed.
Closes #issue-number
Signed-off-by: Your Name <your.email@example.com>"
The -s flag adds the required DCO Signed-off-by line.
5. Push and Create a Pull Request
git push origin your-branch-name
Then go to ccfos/huatuo and create a draft Pull Request. When ready for review, click Ready for review.
6. Code Review
- A maintainer will review your PR
- Address review comments by pushing new commits
- Once approved, the maintainer will merge your PR
Commit Messages
HUATUO follows Conventional Commits:
<type>(<scope>): <description>
[optional body]
[optional footer]
Types
| Type |
Description |
fix |
A bug fix |
feat |
A new feature |
docs |
Documentation changes |
test |
Adding or updating tests |
refactor |
Code restructuring without behavior change |
chore |
Build process, dependencies, etc. |
perf |
Performance improvements |
Examples
fix(pod): preserve response body read errors in httpDoRequest
feat(bpf): add probe for kernel scheduling latency
docs(contributing): add development setup guide
test(request): verify response body is readable after doRequest
Code Style
| Language |
Tool |
| Go |
gofumpt + goimports |
| C (eBPF) |
clang-format (config in .clang-format) |
| Shell |
shfmt |
| YAML/JSON |
2-space indent |
Run make check before every commit to ensure compliance.
DCO Sign-off
All contributions must include a Developer Certificate of Origin (DCO) sign-off.
Every commit must end with:
Signed-off-by: Your Name <your.email@example.com>
Use git commit -s to add this automatically.
The sign-off certifies that you wrote the code or have the right to contribute it under the project’s license (Apache 2.0).
- GitHub Issues — Report bugs and request features
- GitHub Discussions — Ask questions and share ideas
- WeChat — Scan the QR code in the README to join the group
Thank you for contributing to HUATUO!
10 - Change Log
Unreleased
Added
- Added
tcpshark --with-dropwatch --bpf-path-dir <dir> to correlate TCP
retransmissions with an embedded dropwatch source using one shared filter.
- Added
EventTracing.TCPRetransmit.EnableDropwatch for the
huatuo-bamai tcpshark child.
- Added a single
correlation_reason for every finalized local correlation,
including warmup for expired waits whose retransmission predates source readiness,
and an independent namespace-match diagnostic.
Changed
- Replaced the daemon-wide tuple cache with strict local matching across
namespace, direction, sequence or ACK evidence, and monotonic ordering.
- No-match results now report
unknown with cumulative embedded-dropwatch
loss counters, map-counter availability, and one terminal reason. Retransmissions wait up to 100 ms, while
candidate drops have a one-second causal age limit.
EventTracing.TCPRetransmit.Filter now controls retransmission collection in
both modes. Local mode applies it to both inputs, defaults an empty filter to
tcp, and rejects Ethernet-address filters that cannot run equivalently on
synthetic L3 data.- Shutdown now finalizes pending local results inside tcpshark before the child
exits. Embedded drops remain private; standalone dropwatch raw output is
unchanged.